We are launching Qwen-Image-2.0, a next-generation foundational image generation model. The key highlights of Qwen-Image-2.0 include:
Professional Typography Rendering: Supports 1k-token instructions for direct generation of professional infographics, including PPTs, posters, comics, and more.
Stronger Semantic Adherence: Native 2K resolution support for finely detailed realistic scenes, including people, nature, and architecture.
Improved Text Rendering: Integrated understanding and generation capabilities, unifying image generation and editing in a single mode
Lighter Model Architecture: Smaller model size with faster inference speed.
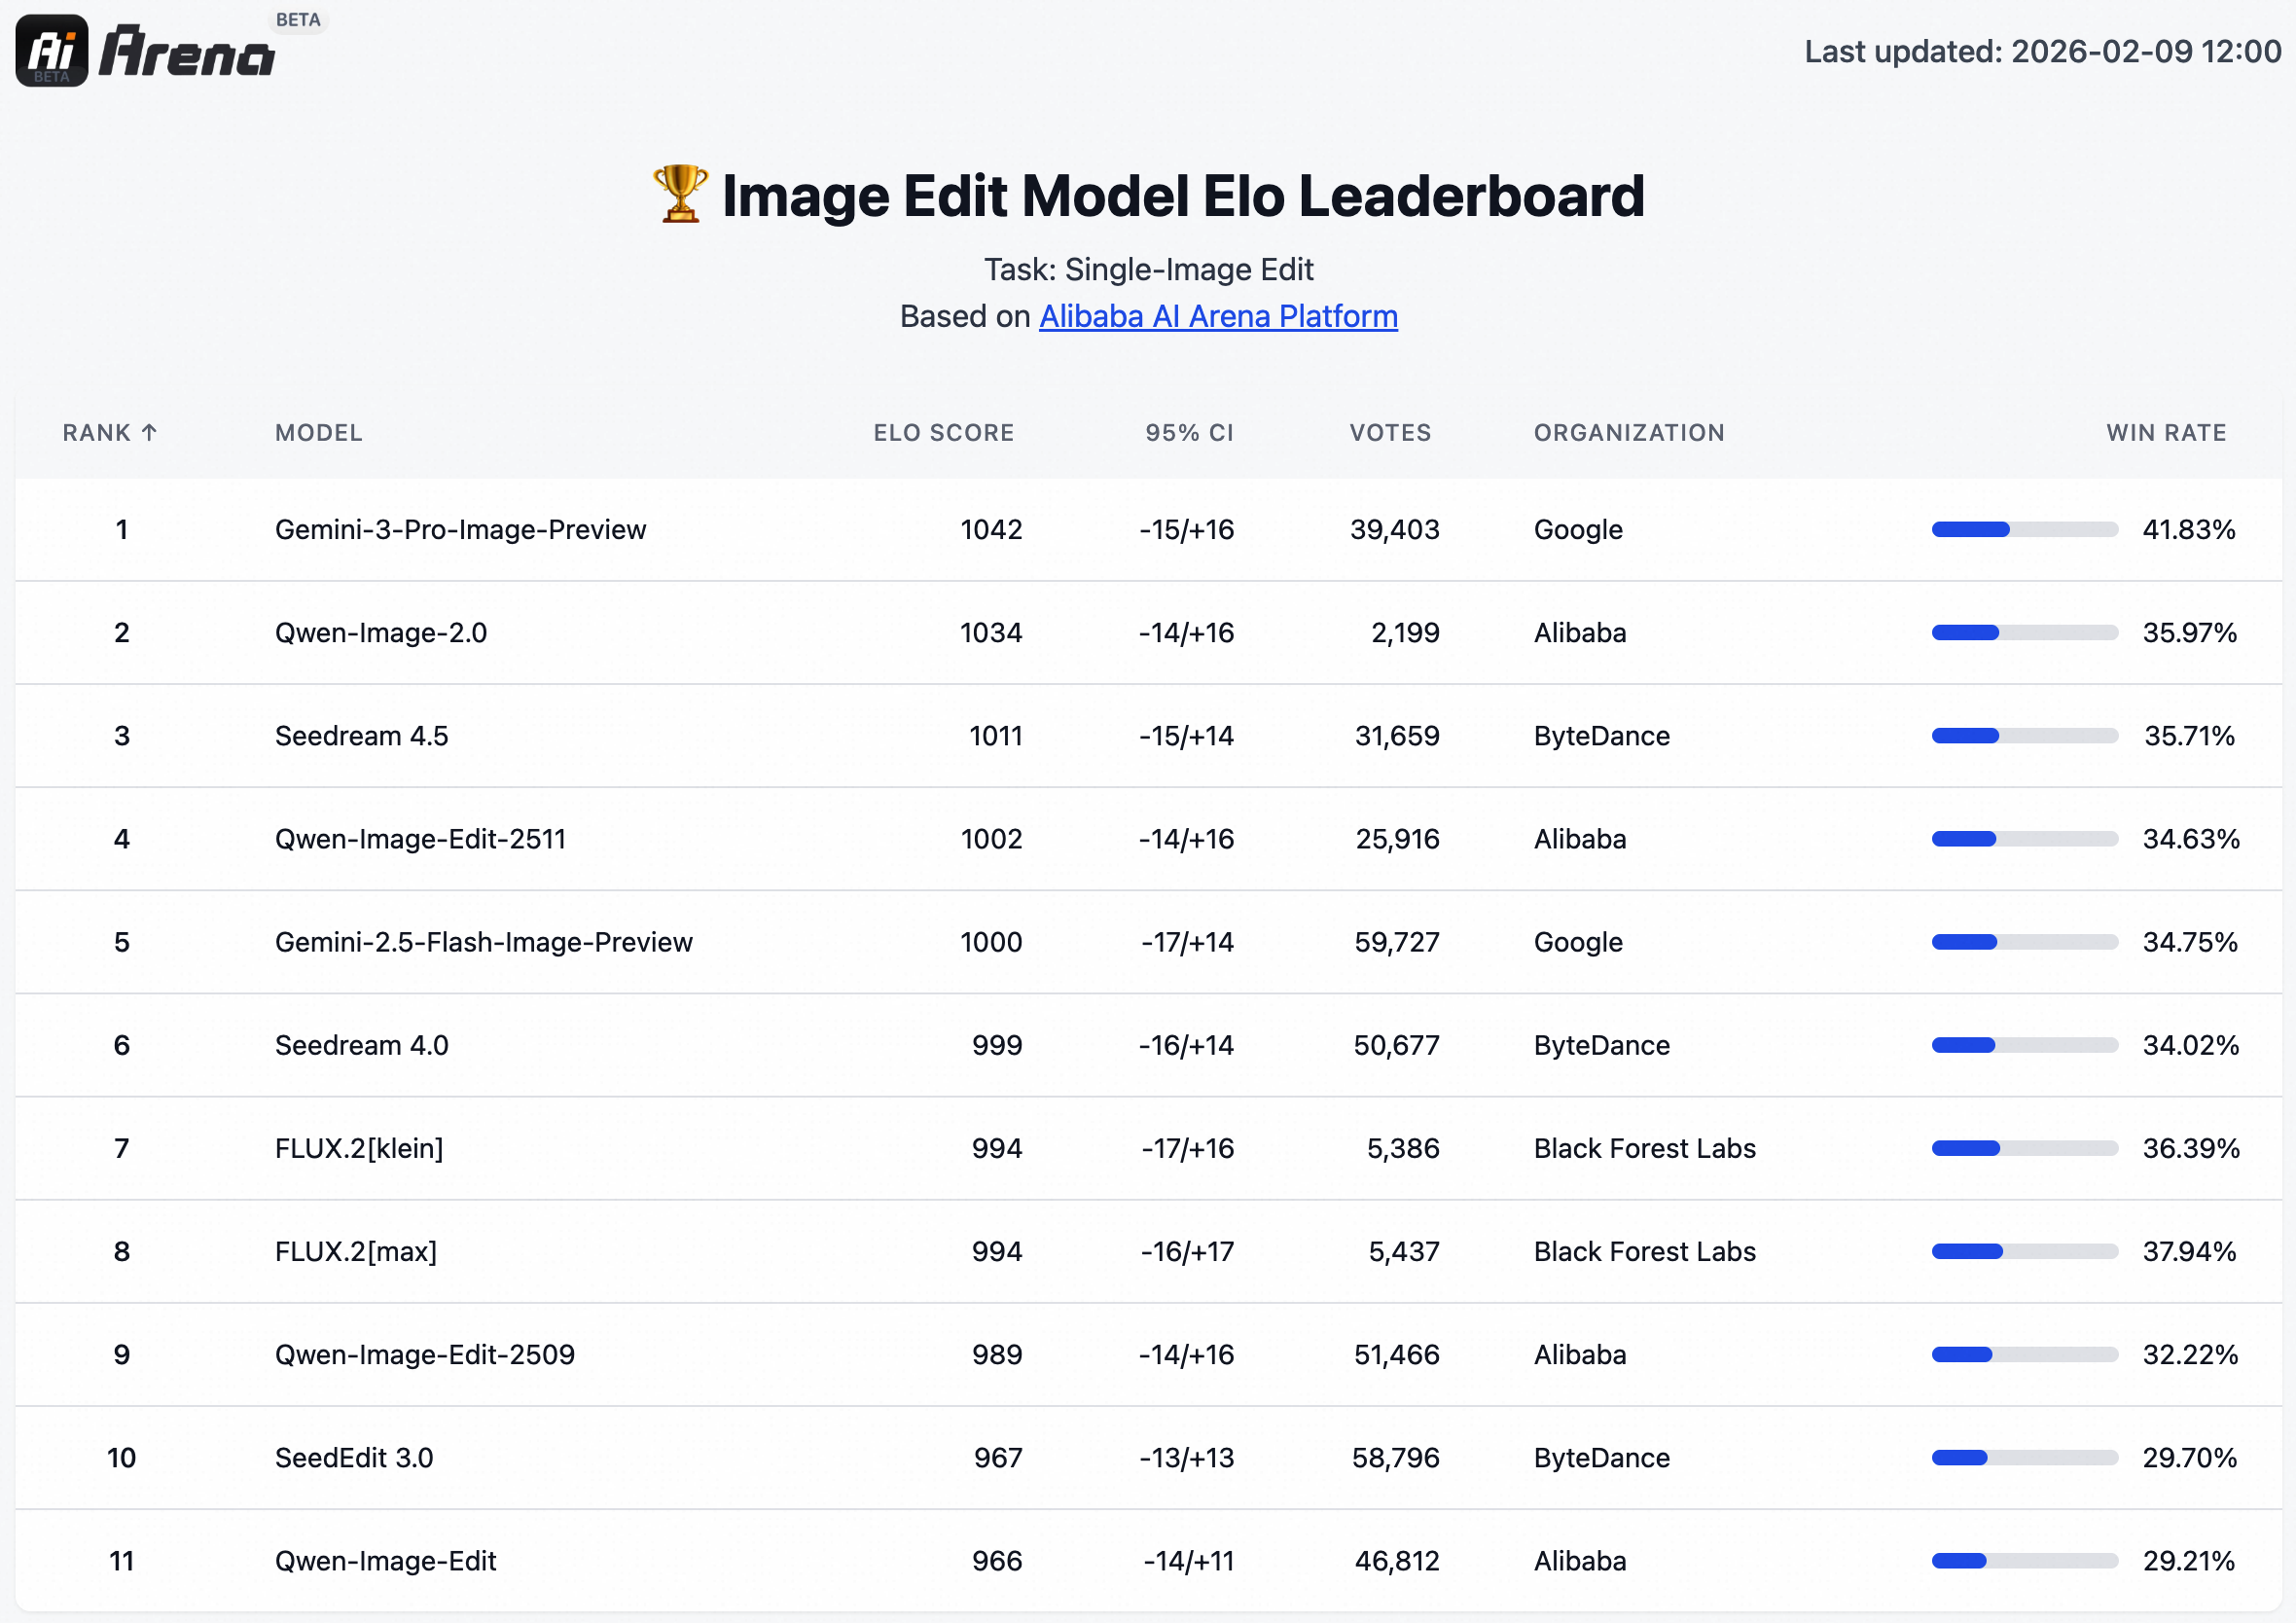
We conducted blind testing on AI Arena. Results show that Qwen-Image-2.0, as a unified generation-and-editing model, achieves superior performance on both text-to-image and image-to-image benchmarks using the same model.
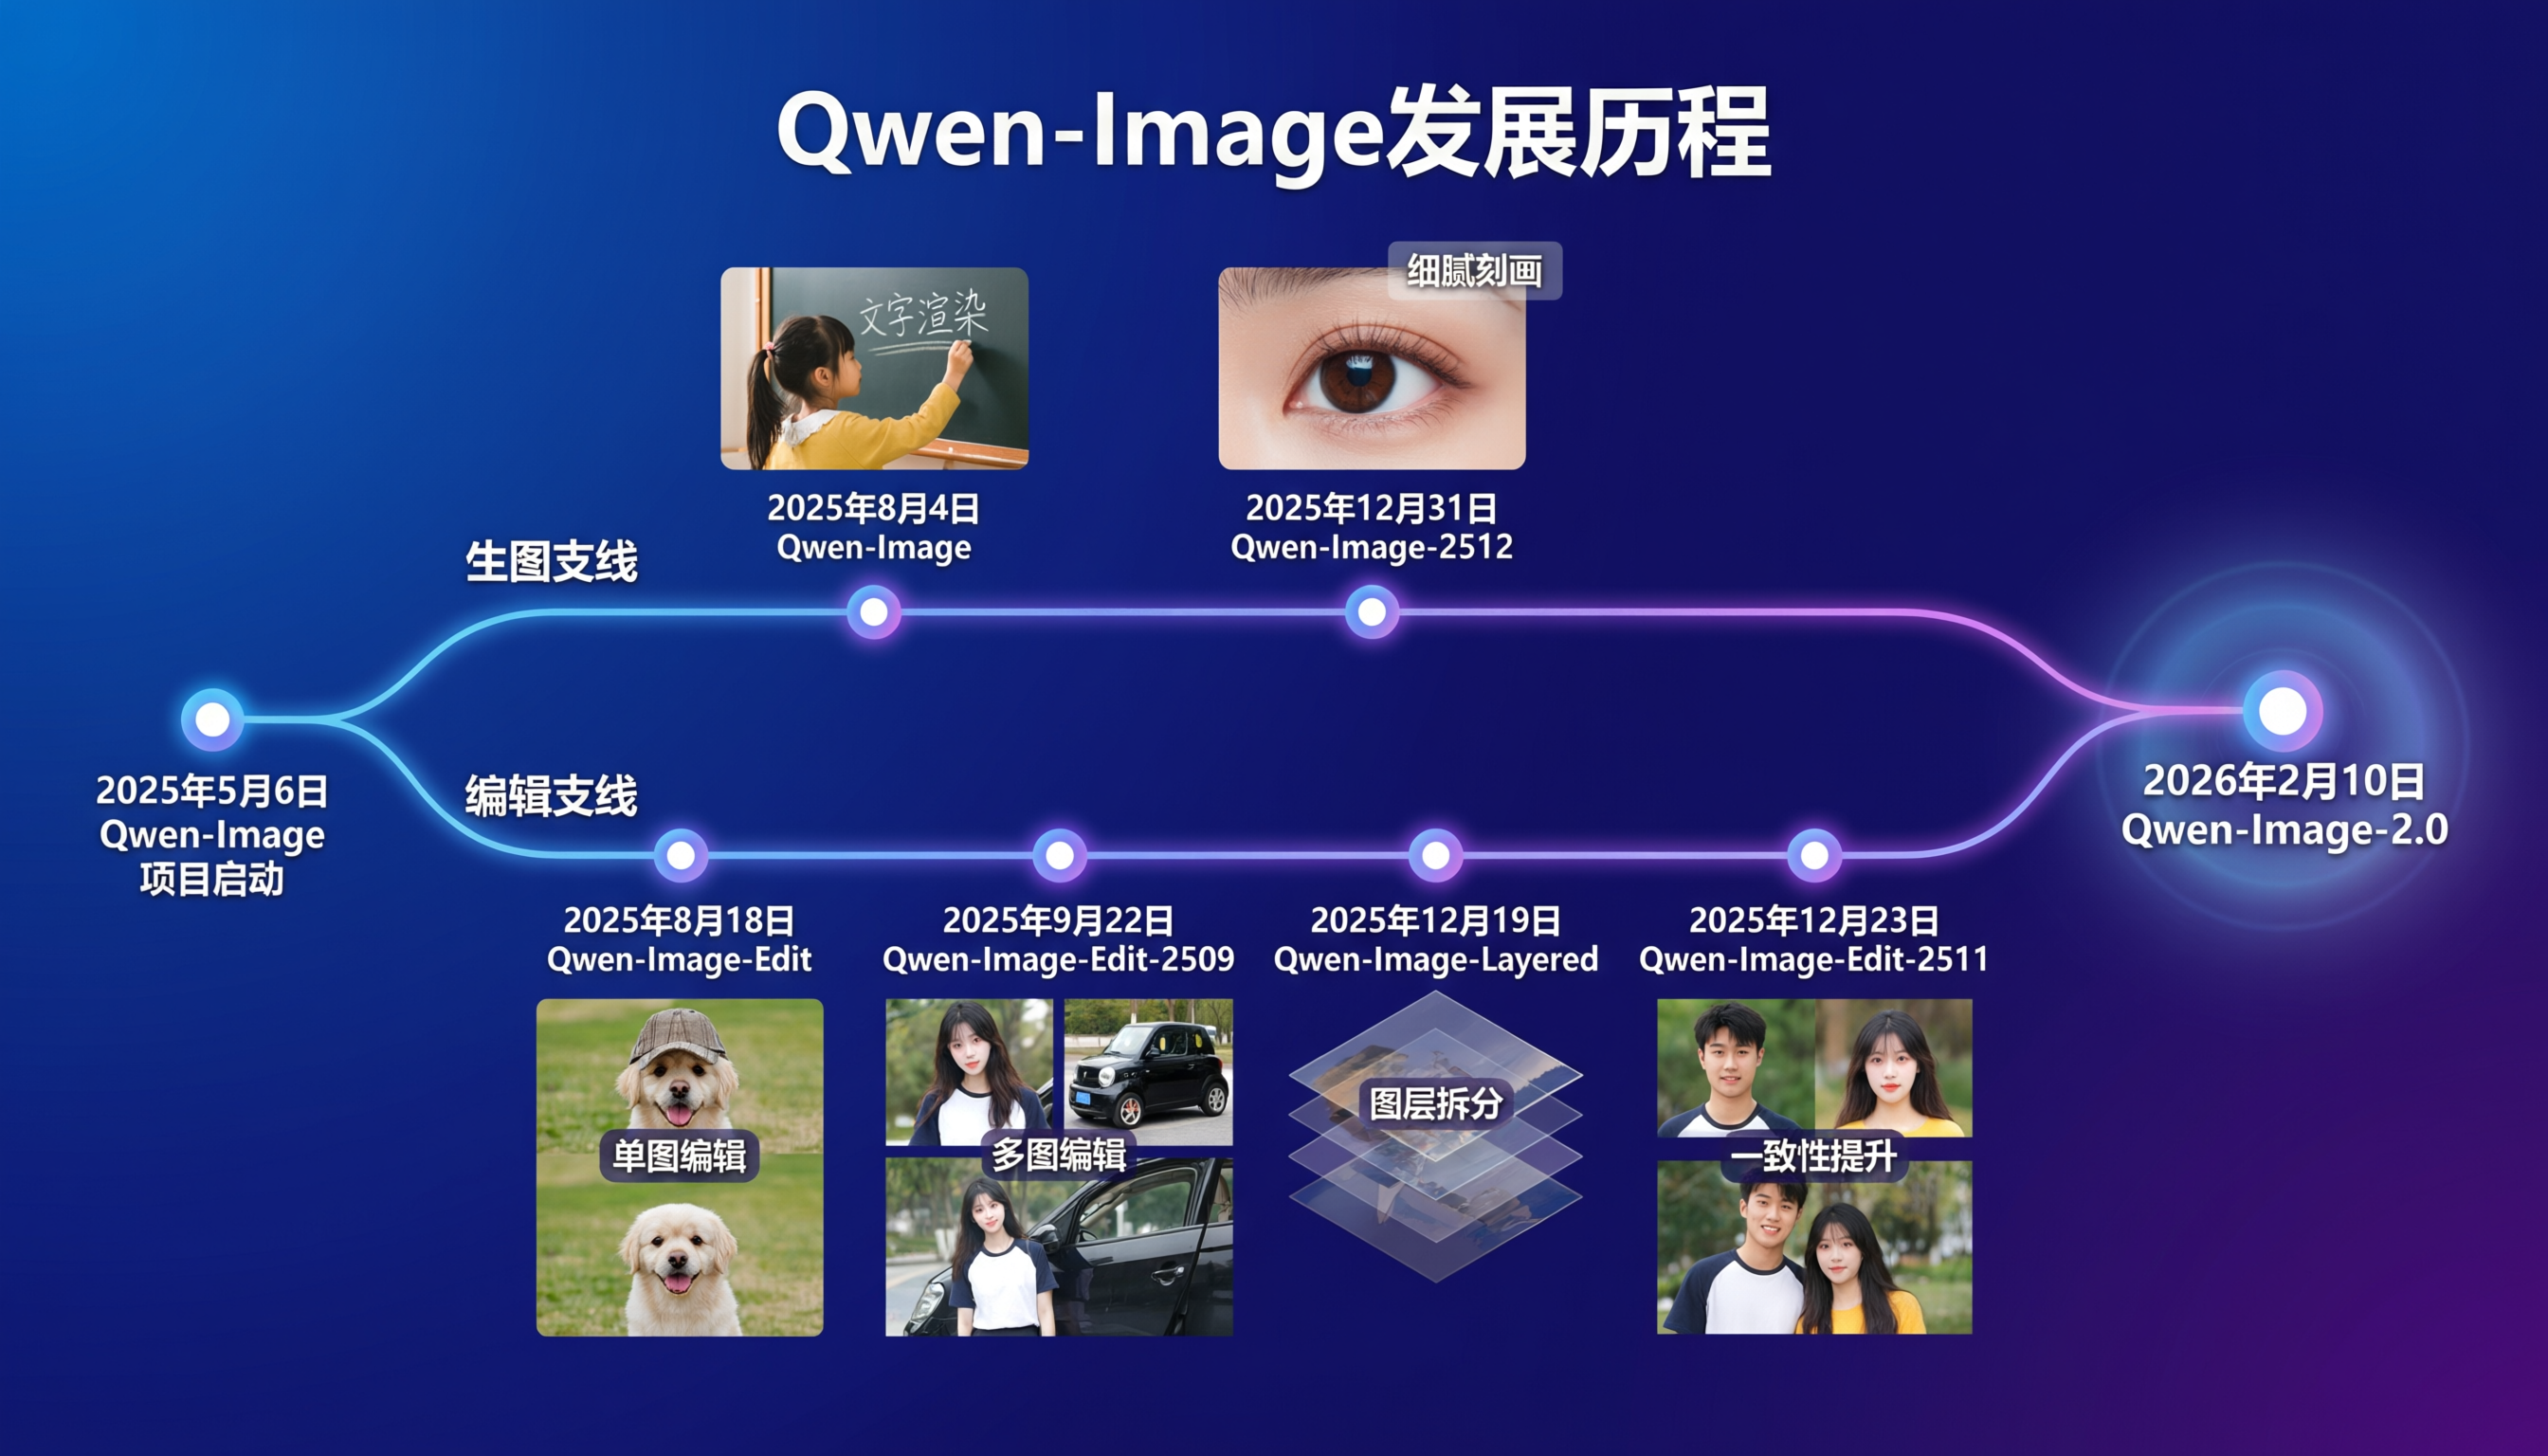
Before introducing Qwen-Image-2.0, let’s first review the evolution of Qwen-Image through a single-slide PPT:
As shown in the slide, prior to Qwen-Image-2.0, we explored two parallel tracks: the generation track and the editing track. On the generation track, we focused on improving accuracy and realism in image synthesis—Qwen-Image (released in August) emphasized precise text rendering, while Qwen-Image-2512 (released in December) enhanced detail fidelity and photorealism. On the editing track, we explored functionality and consistency—from single-image editing in August, to multi-image editing in September, to consistency improvements in December. Today, Qwen-Image-2.0 successfully merges these two tracks into one unified model, delivering excellent results on both tasks simultaneously.
So, what are the practical strengths of this new model? Let’s revisit that PPT slide. Sharp-eyed readers may have noticed that the slide itself was not manually crafted—in fact, it was directly generated by Qwen-Image-2.0 using the following prompt:
Analyzing this slide reveals that Qwen-Image-2.0 can not only generate a dual-track timeline of development history and accurately render every piece of text, but also execute complex “picture-in-picture” compositions. For instance, in rendering the instruction “below is a composite image: the top shows a puppy wearing a hat, the bottom shows the same puppy without the hat,” the model not only completed the rendering but also maintained visual consistency between the two images. This precise “picture-in-picture” capability makes it significantly easier to create professional PPTs.
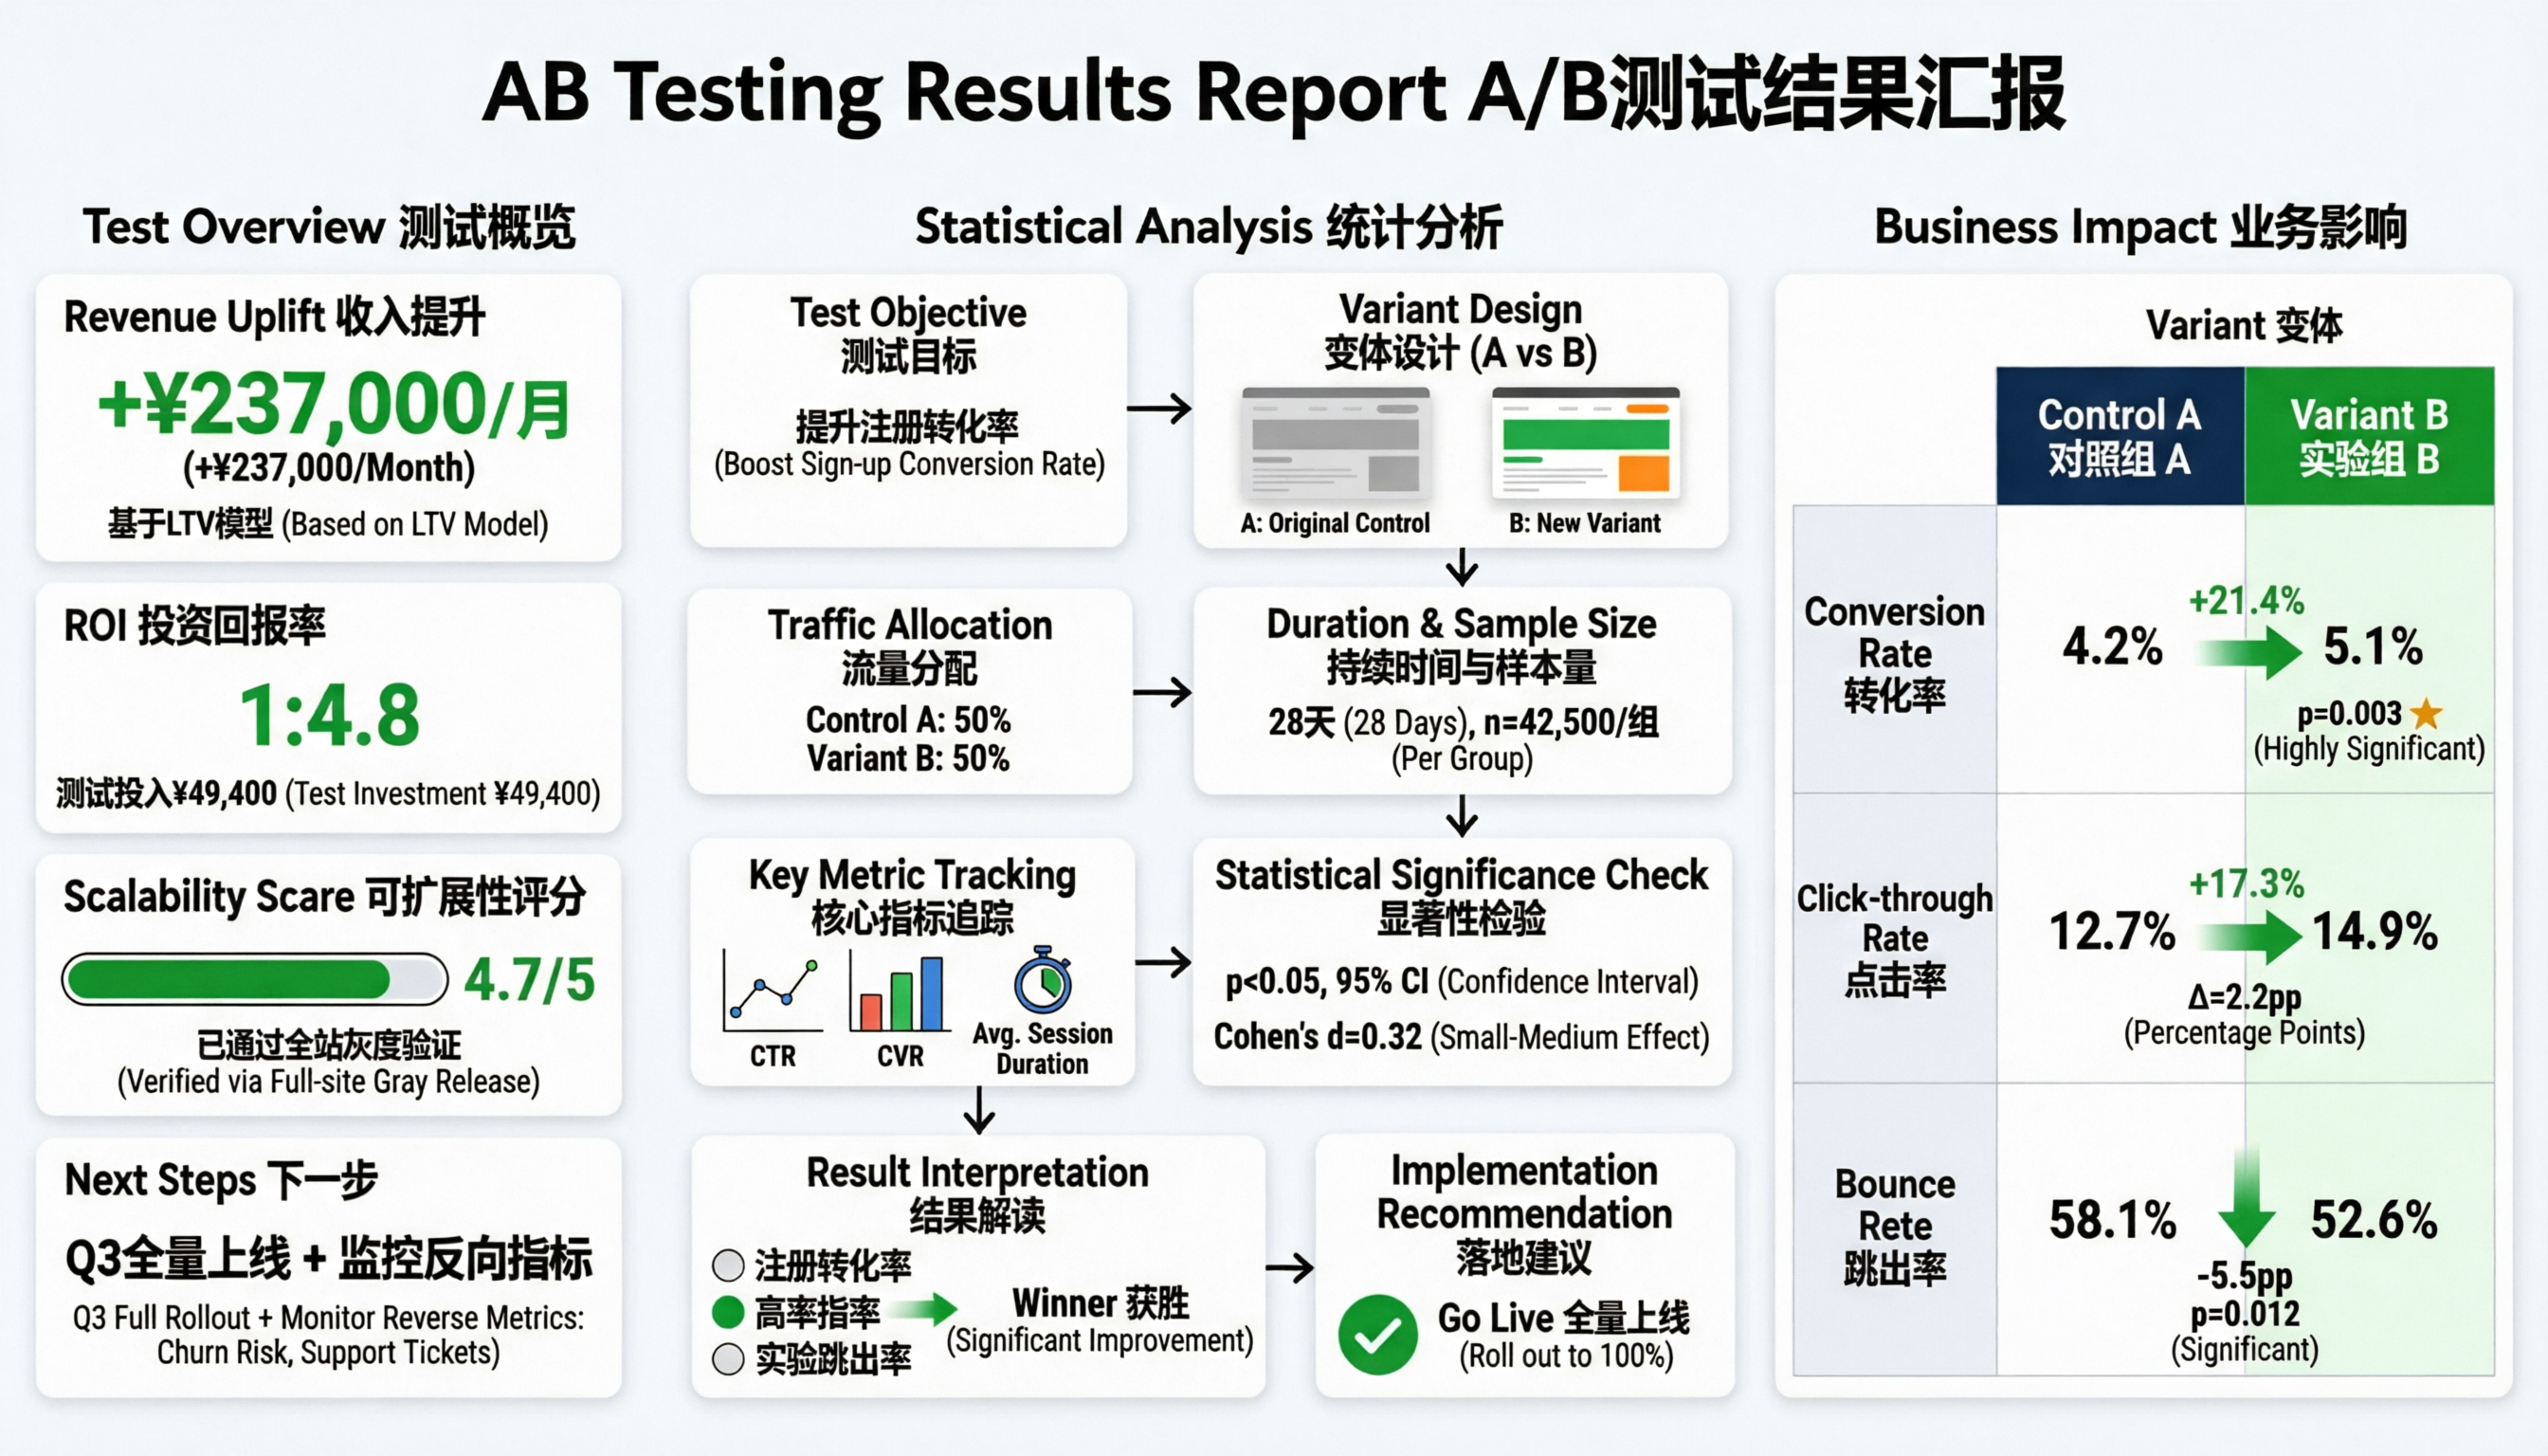
Beyond precision (“准”), another strength of Qwen-Image-2.0 is its capacity for complexity (“多”). With support for 1k-token instructions, the model can handle highly intricate rendering requests, such as the following exaggerated example:
这张图片展示了一份名为 AB Testing Results Report A/B测试结果汇报 的信息图表,内容分为左、中、右三栏。左侧栏标题为 Test Overview 测试概览。第一个板块标题是 Revenue Uplift 收入提升,中间以大号绿色字体显示 +¥237,000/月,下方括号内注明 (+¥237,000/Month),底部文字为 基于LTV模型 (Based on LTV Model)。第二个板块标题是 ROI 投资回报率,中间显示大号绿色数字 1:4.8,底部文字为 测试投入¥49,400 (Test Investment ¥49,400)。第三个板块标题是 Scalability Score 可扩展性评分,中间展示了一个绿色进度条图标,右侧数字为 4.7/5,底部文字为 已通过全站灰度验证 (Verified via Full-site Gray Release)。第四个板块标题是 Next Steps 下一步,正文第一行为粗体的 Q3全量上线 + 监控反向指标,第二行为 Q3 Full Rollout + Monitor Reverse Metrics: Churn Risk, Support Tickets)。中间栏标题为 Statistical Analysis 统计分析,各模块间通过黑色箭头表示流程关系。左上方的方框标题为 Test Objective 测试目标,内容是 提升注册转化率 (Boost Sign-up Conversion Rate)。箭头指向右上方的方框 Variant Design 变体设计 (A vs B),其中包含两个网页界面示意图,左侧灰色图下标为 A: Original Control,右侧带有绿色和橙色块的图下标为 B: New Variant。第二行左侧方框标题为 Traffic Allocation 流量分配,内容显示 Control A: 50% 和 Variant B: 50%。右侧方框标题为 Duration & Sample Size 持续时间与样本量,内容显示 28天 (28 Days), n=42,500/组 (Per Group)。第三行左侧方框标题为 Key Metric Tracking 核心指标追踪,下方有折线图、柱状图和秒表三个图标,分别对应标签 CTR,CVR,Avg. Session Duration。右侧方框标题为 Statistical Significance Check 显著性检验,内容为 p<0.05, 95% CI (Confidence Interval) Cohen’s d=0.32 (Small-Medium Effect)。第四行左侧方框标题为 Result Interpretation 结果解读,左侧列出了带有颜色圆点的条目:空心圆点 注册转化率,实心绿点 高率指率,空心圆点 实验跳出率,右侧有一个绿色箭头指向文字 Winner 获胜 (Significant Improvement)。流程图最终指向右下角的方框 Implementation Recommendation 落地建议,内有一个绿色对勾图标,文字为 Go Live 全量上线 (Roll out to 100%)。右侧栏标题为 Business Impact 业务影响,是一个三行两列的数据表。表头跨列标题为 Variant 变体,分为深蓝色背景的 Control A 对照组 A 和绿色背景的 Variant B 实验组 B。表格第一行左侧标签为 Conversion Rate 转化率,Control A 数据为 4.2%,Variant B 数据为 5.1%,中间有一个带 +21.4% 的绿色箭头指向右侧,Variant B 下方还有文字 p=0.003 ★ (Highly Significant)。表格第二行左侧标签为 Click-through Rate 点击率,Control A 数据为 12.7%,Variant B 数据为 14.9%,中间有一个带 +17.3% 的绿色箭头指向右侧,下方文字为 Δ=2.2pp (Percentage Points)。表格第三行左侧标签为 Bounce Rate 跳出率,Control A 数据为 58.1%,Variant B 数据为 52.6%,中间有一个绿色向下箭头,下方文字为 -5.5pp p=0.012 (Significant)。
Readers might wonder whether such complex prompts are user-friendly. The truth is, thanks to the world knowledge embedded in LLMs, obtaining detailed descriptive prompts is actually quite straightforward. For example, given this simple input:
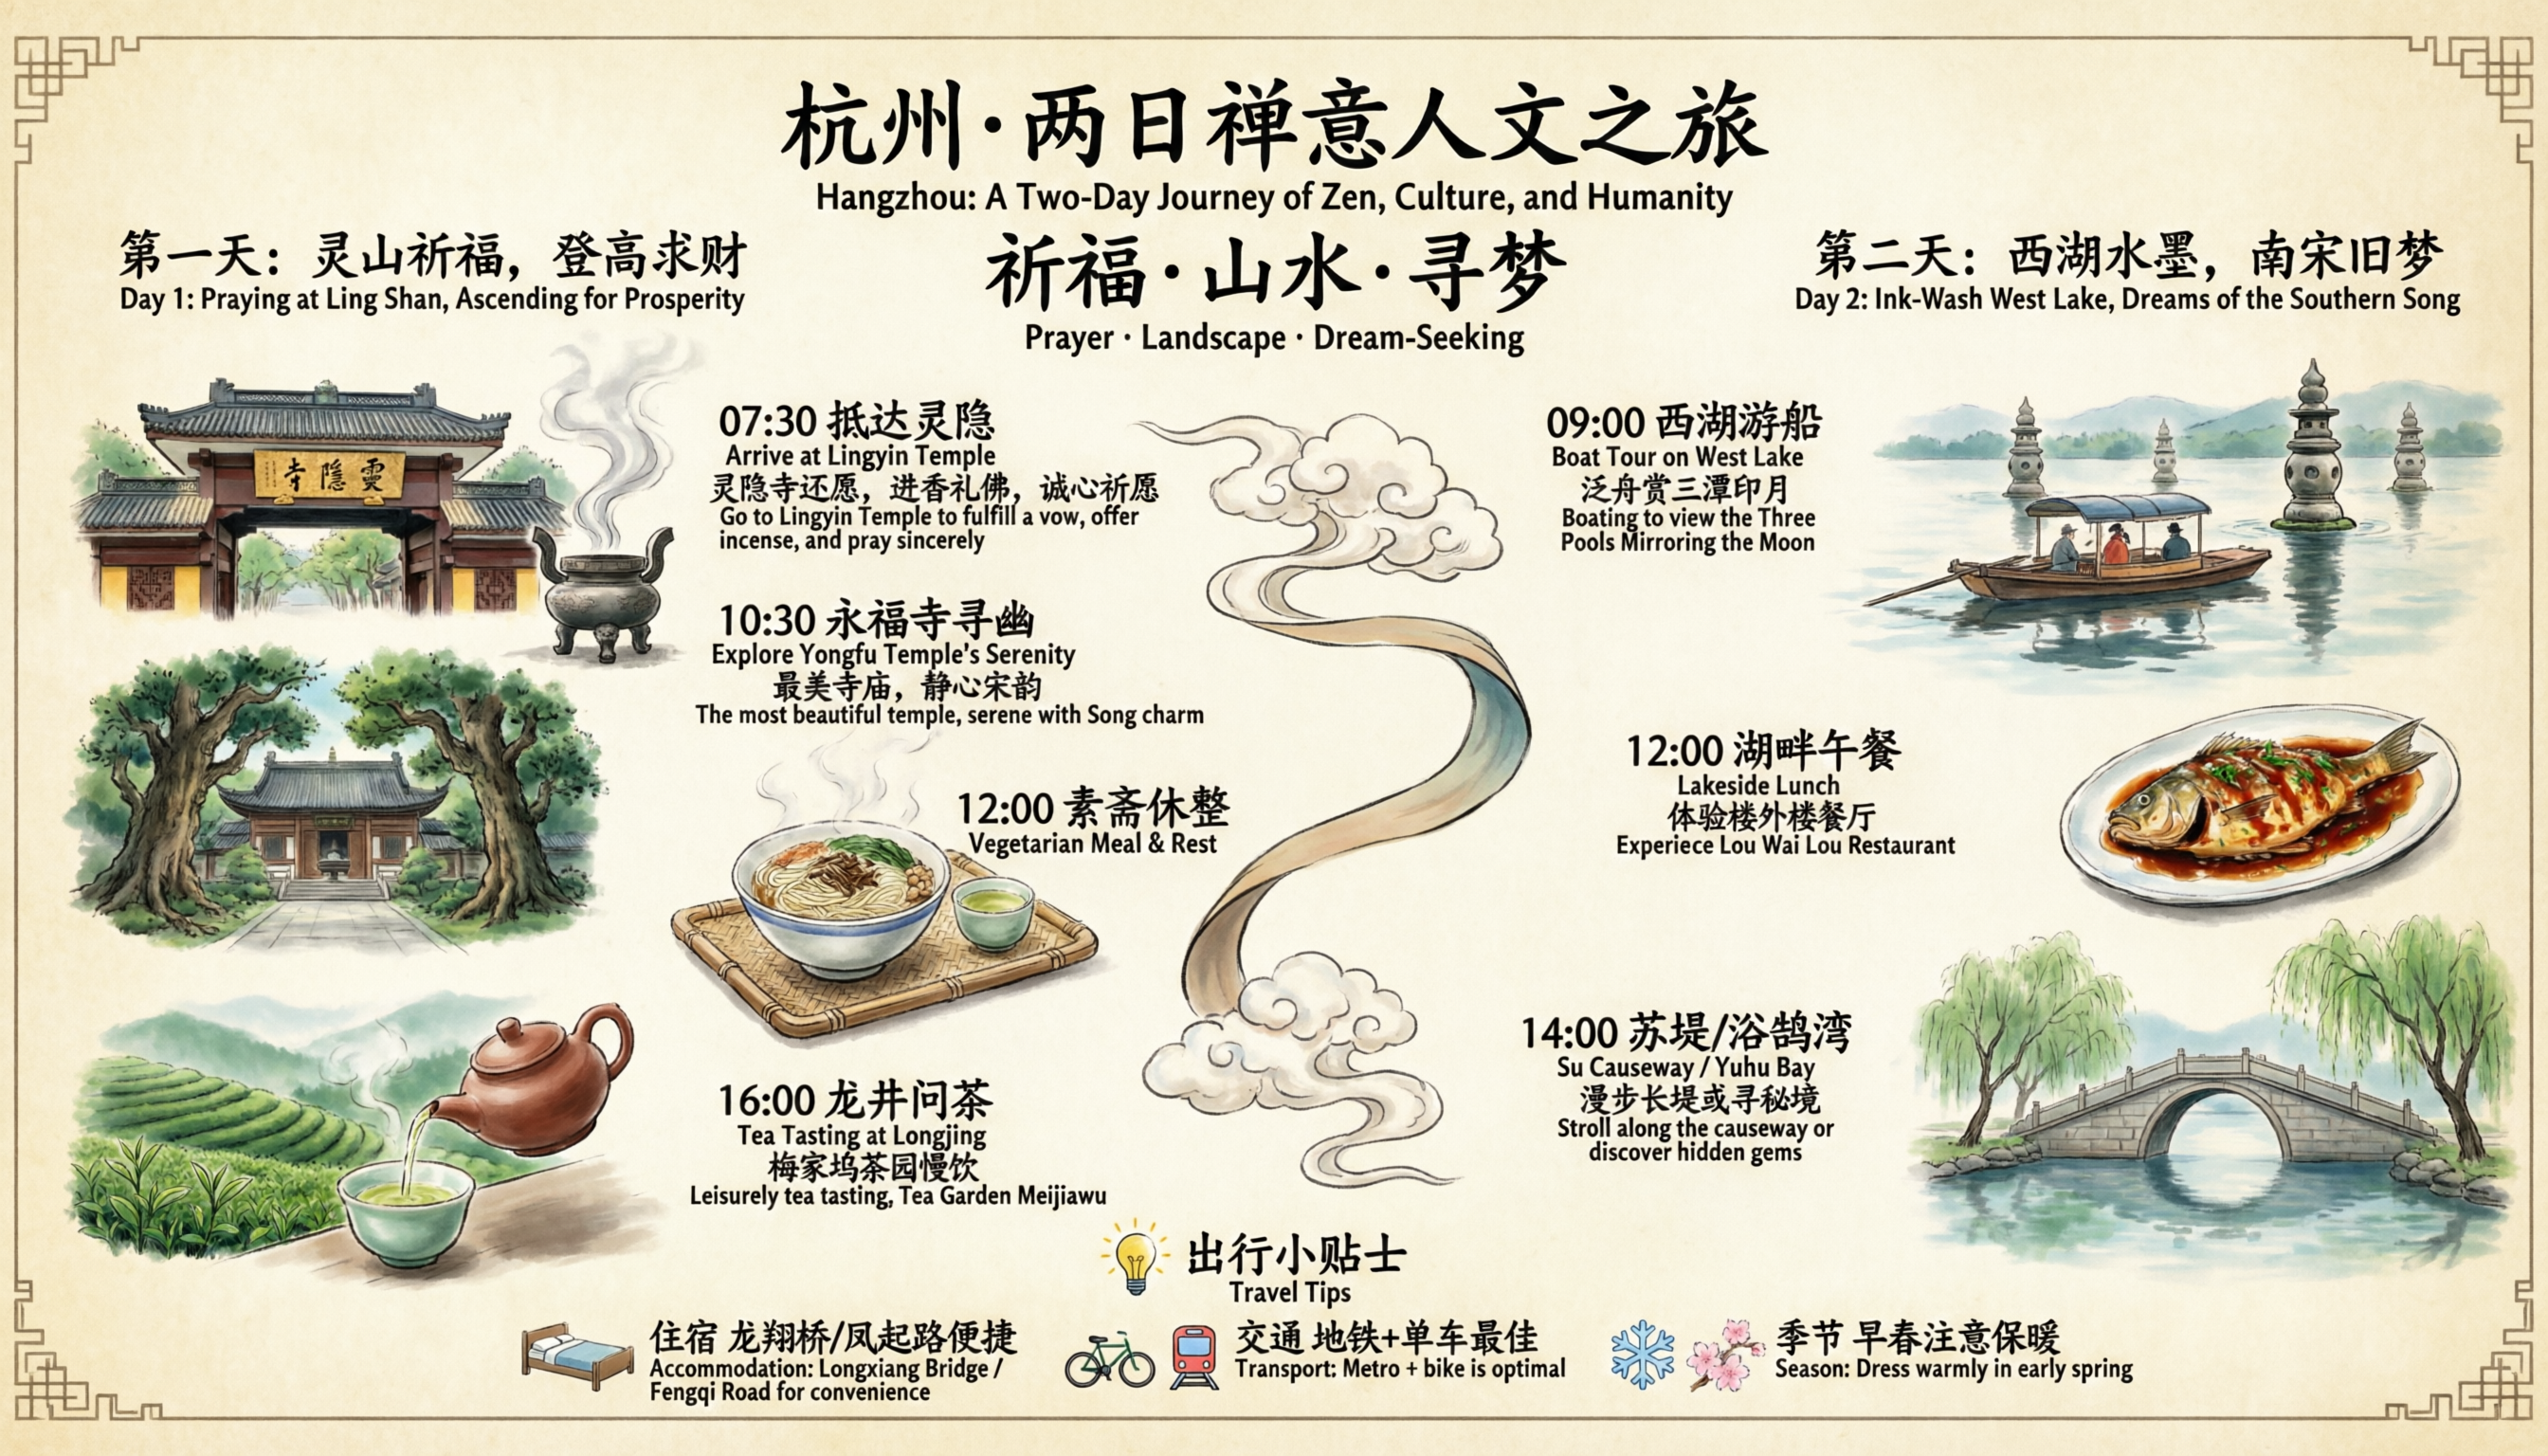
帮我生成一个手绘风格的杭州两日禅意人文之旅双语海报
We can feed it into an LLM for rewriting, leveraging its world knowledge to produce a richly detailed prompt like this:
这是一幅中国风手绘风格的杭州两日禅意人文之旅行程导览双语海报,整体采用淡雅米黄色仿古宣纸背景,四角饰有传统回纹边框;画面中央以一条飘逸的云纹卷轴丝带贯穿连接两天行程,上方大标题为“杭州·两日禅意人文之旅”(“Hangzhou: A Two-Day Journey of Zen, Culture, and Humanity”),副标题为“祈福·山水·寻梦”(“Prayer · Landscape · Dream-Seeking”);左侧为“第一天:灵山祈福,登高求财”(“Day 1: Praying at Ling Shan, Ascending for Prosperity”),依次展示:“07:30 抵达灵隐”(“Arrive at Lingyin Temple”),配灵隐寺山门(牌匾写着"灵隐寺")与香炉袅袅青烟图,文字说明“灵隐寺还愿,进香礼佛,诚心祈愿”(“Go to Lingyin Temple to fulfill a vow, offer incense, and pray sincerely”);“10:30 永福寺寻幽”(“Explore Yongfu Temple’s Serenity”),配古朴寺院掩映于苍翠古树间图,文字说明“最美寺庙,静心宋韵”(“The most beautiful temple, serene with Song charm”);“12:00 素斋休整”(“Vegetarian Meal & Rest”),配一碗热气腾腾素面与小茶盏置于竹编托盘上图;“16:00 龙井问茶”(“Tea Tasting at Longjing”),配层叠翠绿茶园与紫砂壶向青瓷杯倾注茶汤图,文字说明“梅家坞茶园慢饮”(“Leisurely tea tasting, Tea Garden Meijiawu”);右侧为“第二天:西湖水墨,南宋旧梦”(“Day 2: Ink-Wash West Lake, Dreams of the Southern Song”),依次展示:“09:00 西湖游船”(“Boat Tour on West Lake”),配乌篷船泛舟湖上、三潭印月石塔倒影水中图,文字说明“泛舟赏三潭印月”(“Boating to view the Three Pools Mirroring the Moon”);“12:00 湖畔午餐”(“Lakeside Lunch”),文字说明“体验楼外楼餐厅” (“Experience Lou Wai Lou Restaurant”),配一盘色泽红亮的鱼,上面淋酱汁;“14:00 苏堤/浴鹄湾”(“Su Causeway / Yuhu Bay”),配拱桥横跨碧波、垂柳依依图,文字说明“漫步长堤或寻秘境”(“Stroll along the causeway or discover hidden gems”);底部设“出行小贴士”板块(“Travel Tips”),含灯泡图标及三项提示:“住宿 龙翔桥/凤起路便捷”(“Accommodation: Longxiang Bridge / Fengqi Road for convenience”),“交通 地铁+单车最佳”(“Transport: Metro + bike is optimal”),“季节 早春注意保暖”(“Season: Dress warmly in early spring”),每项前分别配床、自行车+地铁、雪花+樱花图标;全图文字均采用楷体书法风格,中英文严格对应排布——中文在上、英文紧随其下,整体构图疏密有致、意境悠远,充满文人画气息与禅意生活美学。
And it is precisely such complex descriptions that Qwen-Image-2.0 excels at rendering. Here is the resulting image:
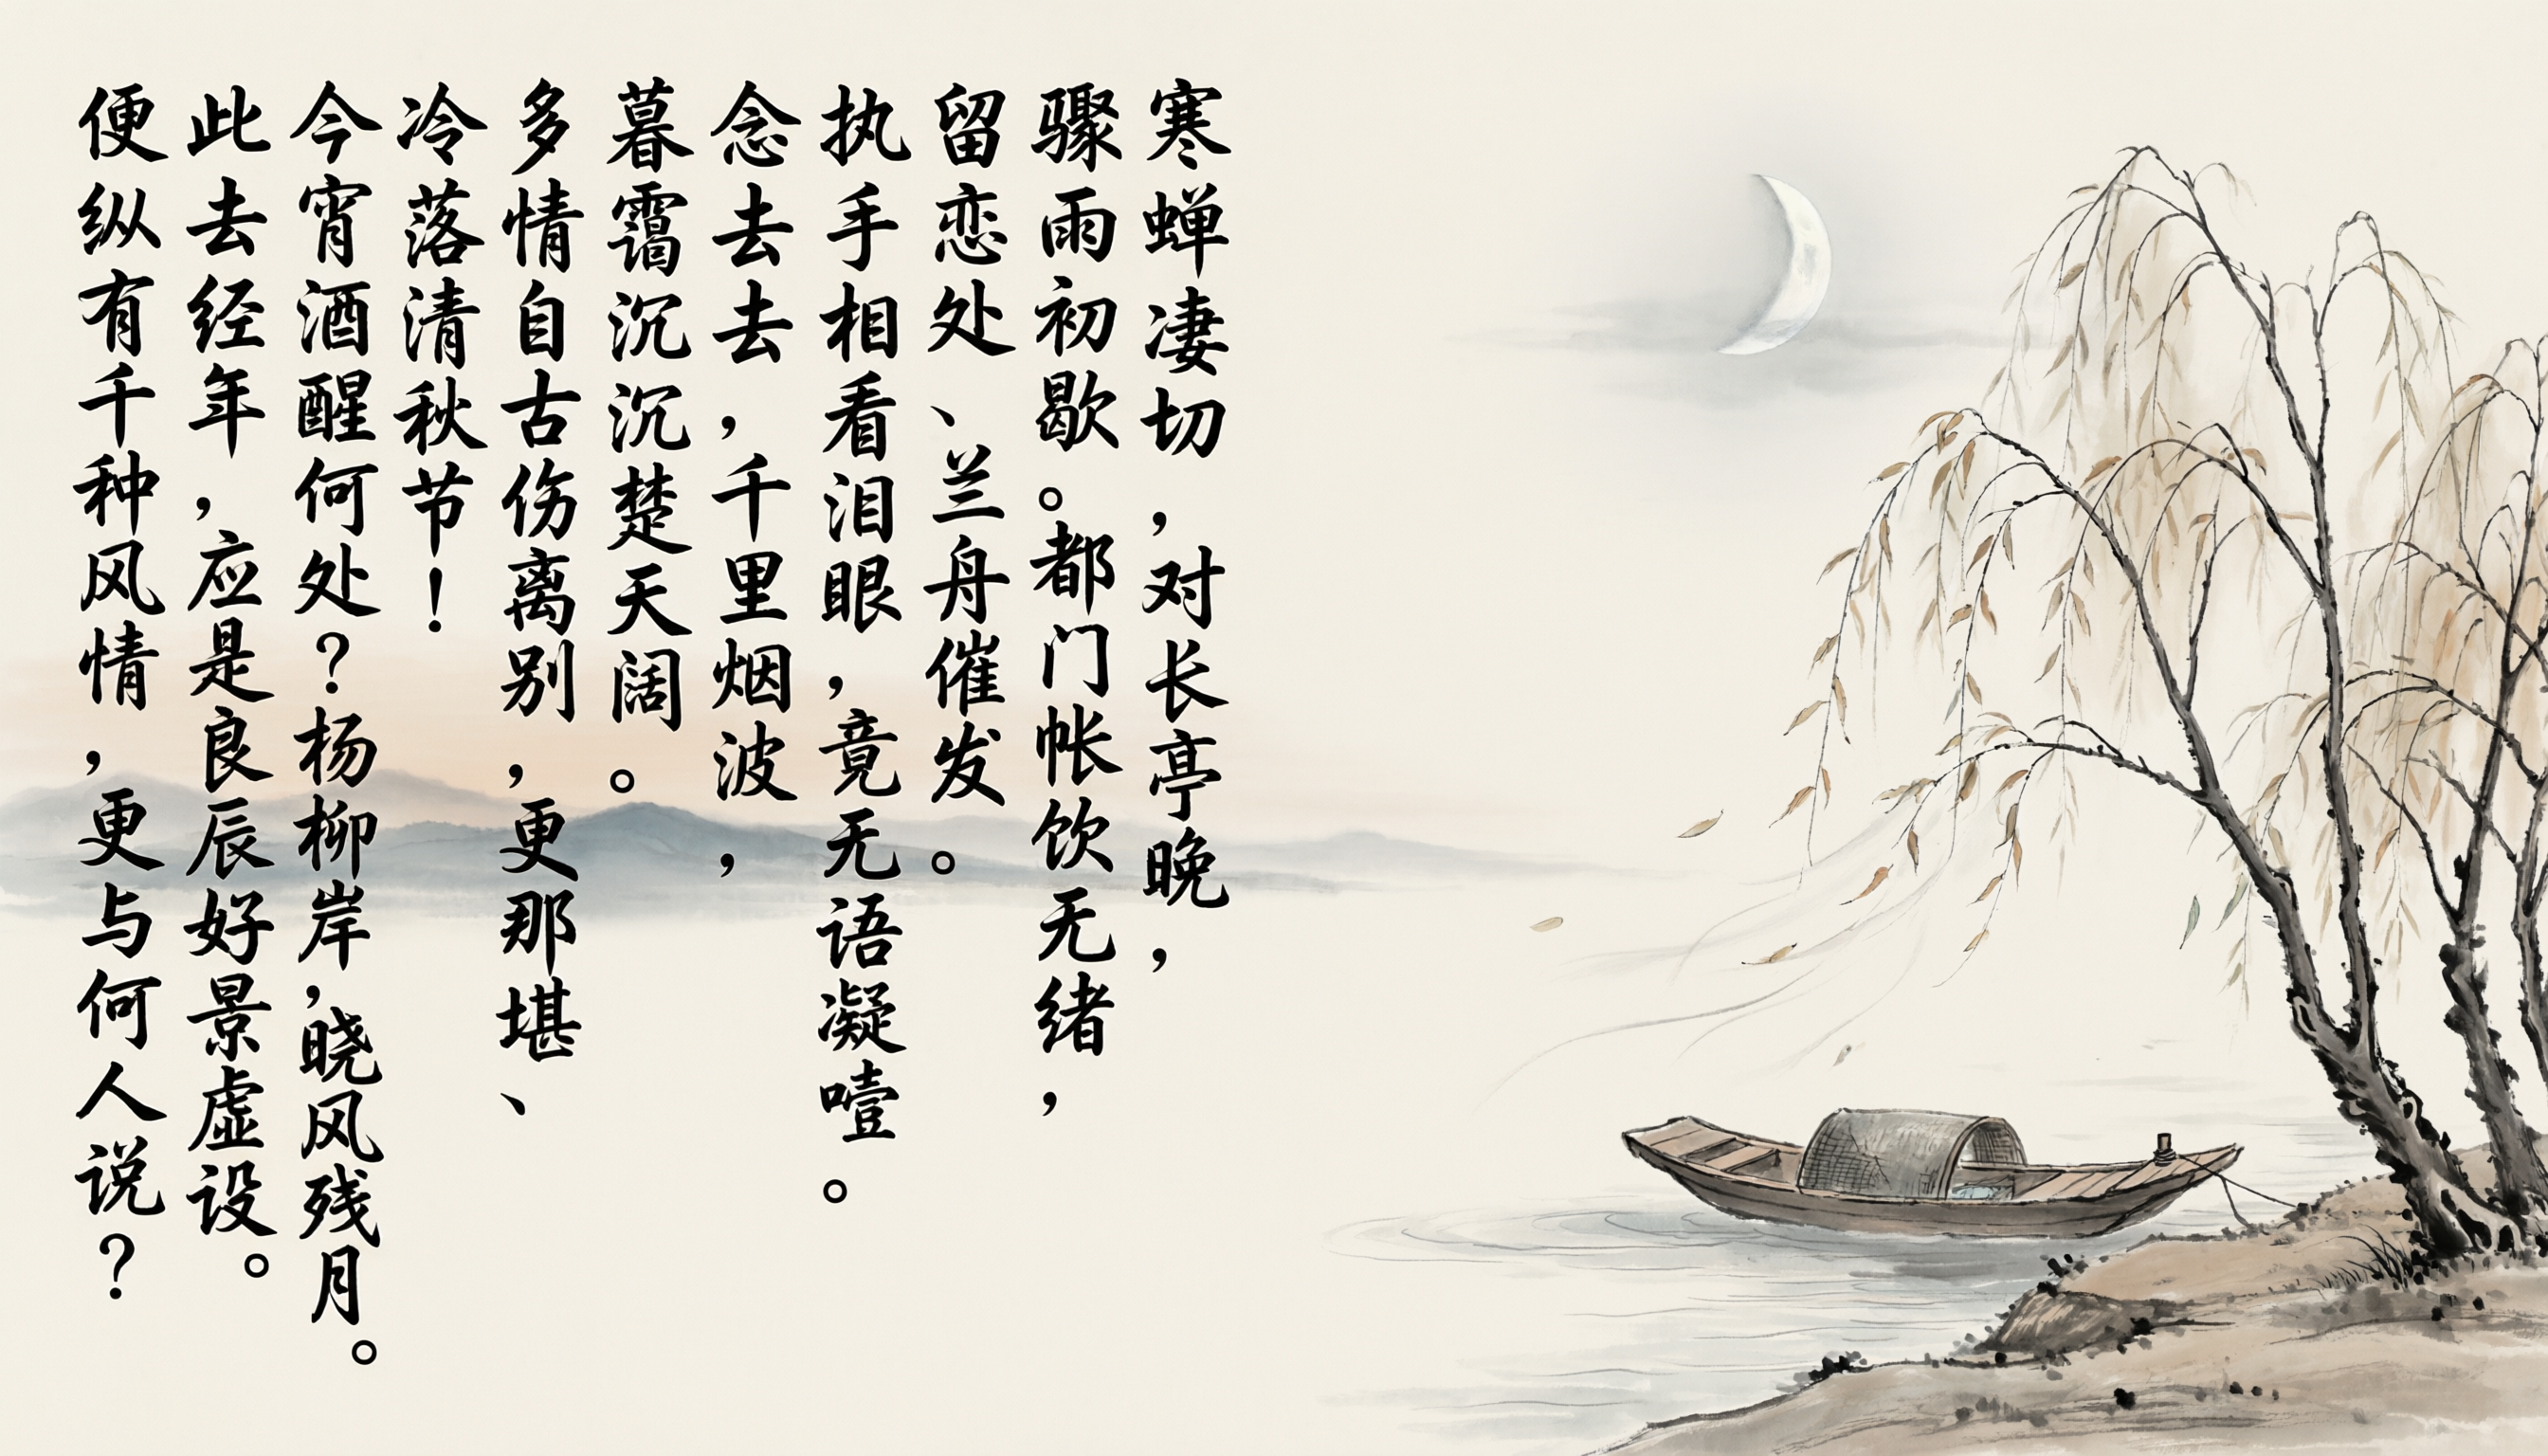
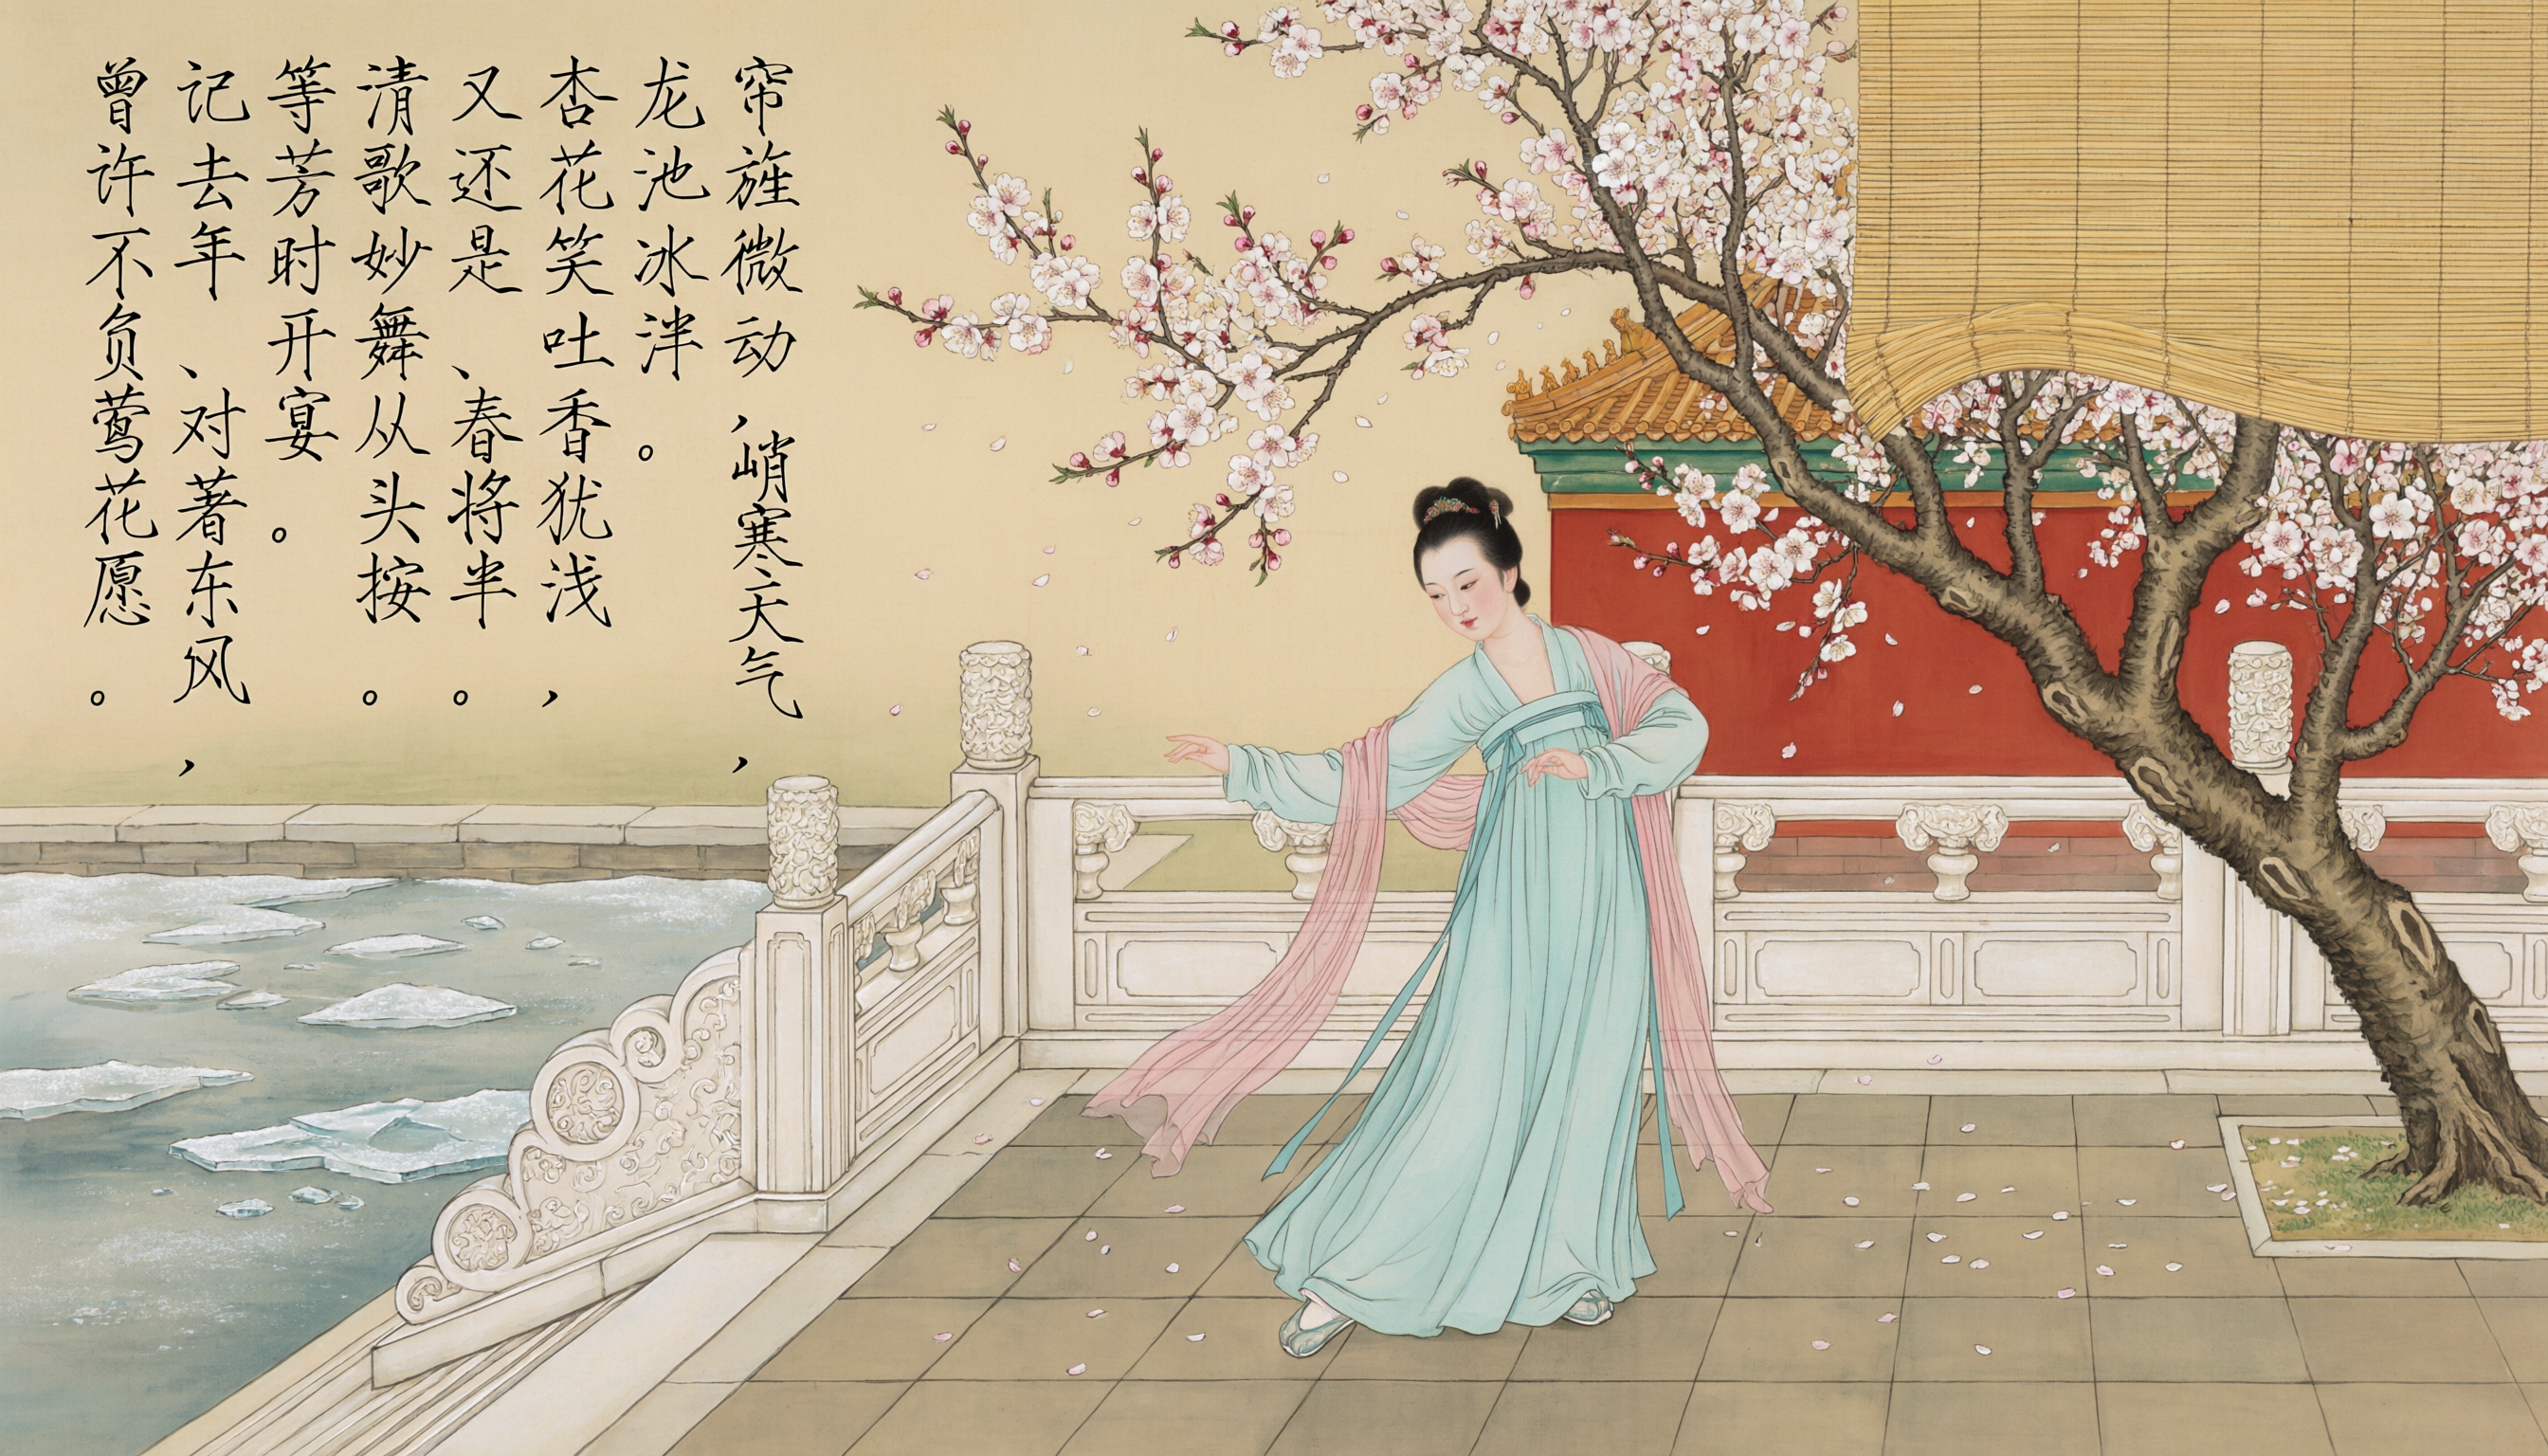
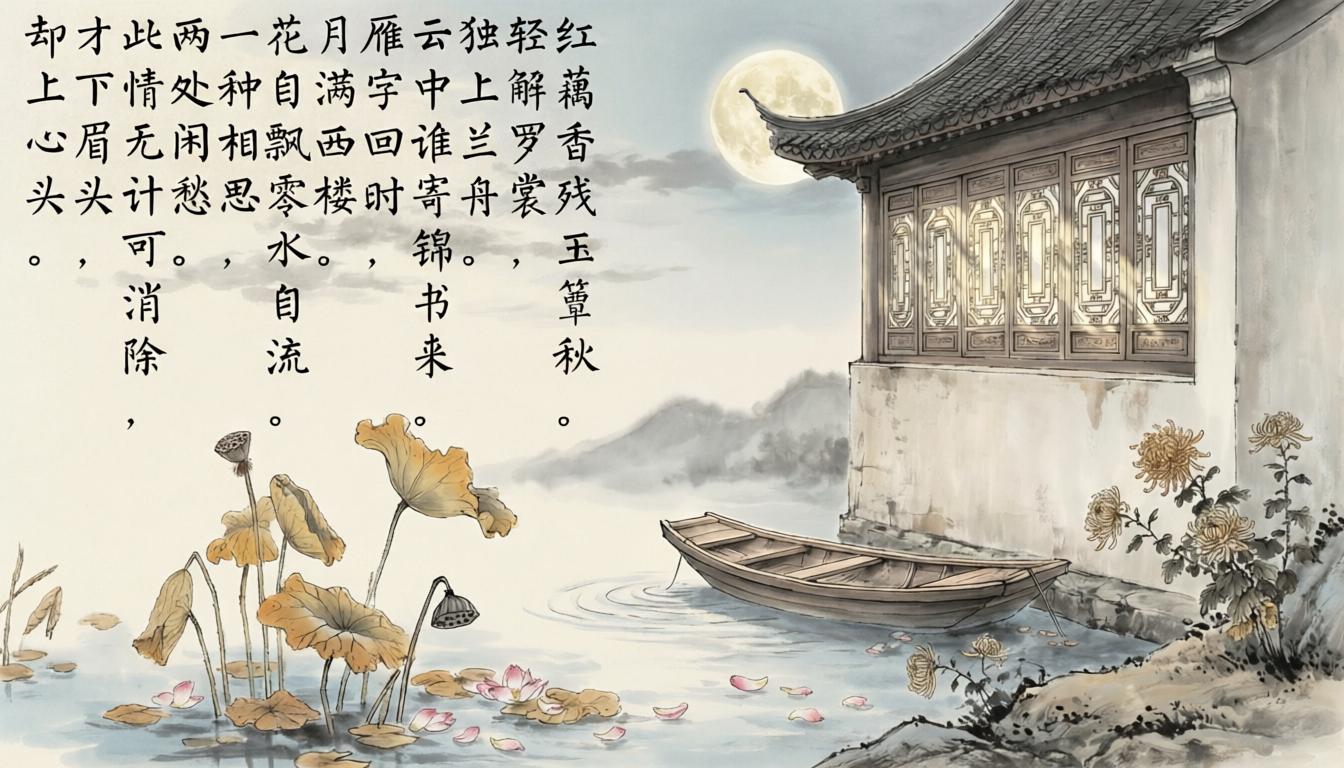
Beyond precision (“准”) and complexity (“多”), aesthetic quality (“美”) is another hallmark of Qwen-Image-2.0’s text rendering. This “beauty” manifests in the layout and composition of text and images. For example, consider this prompt:
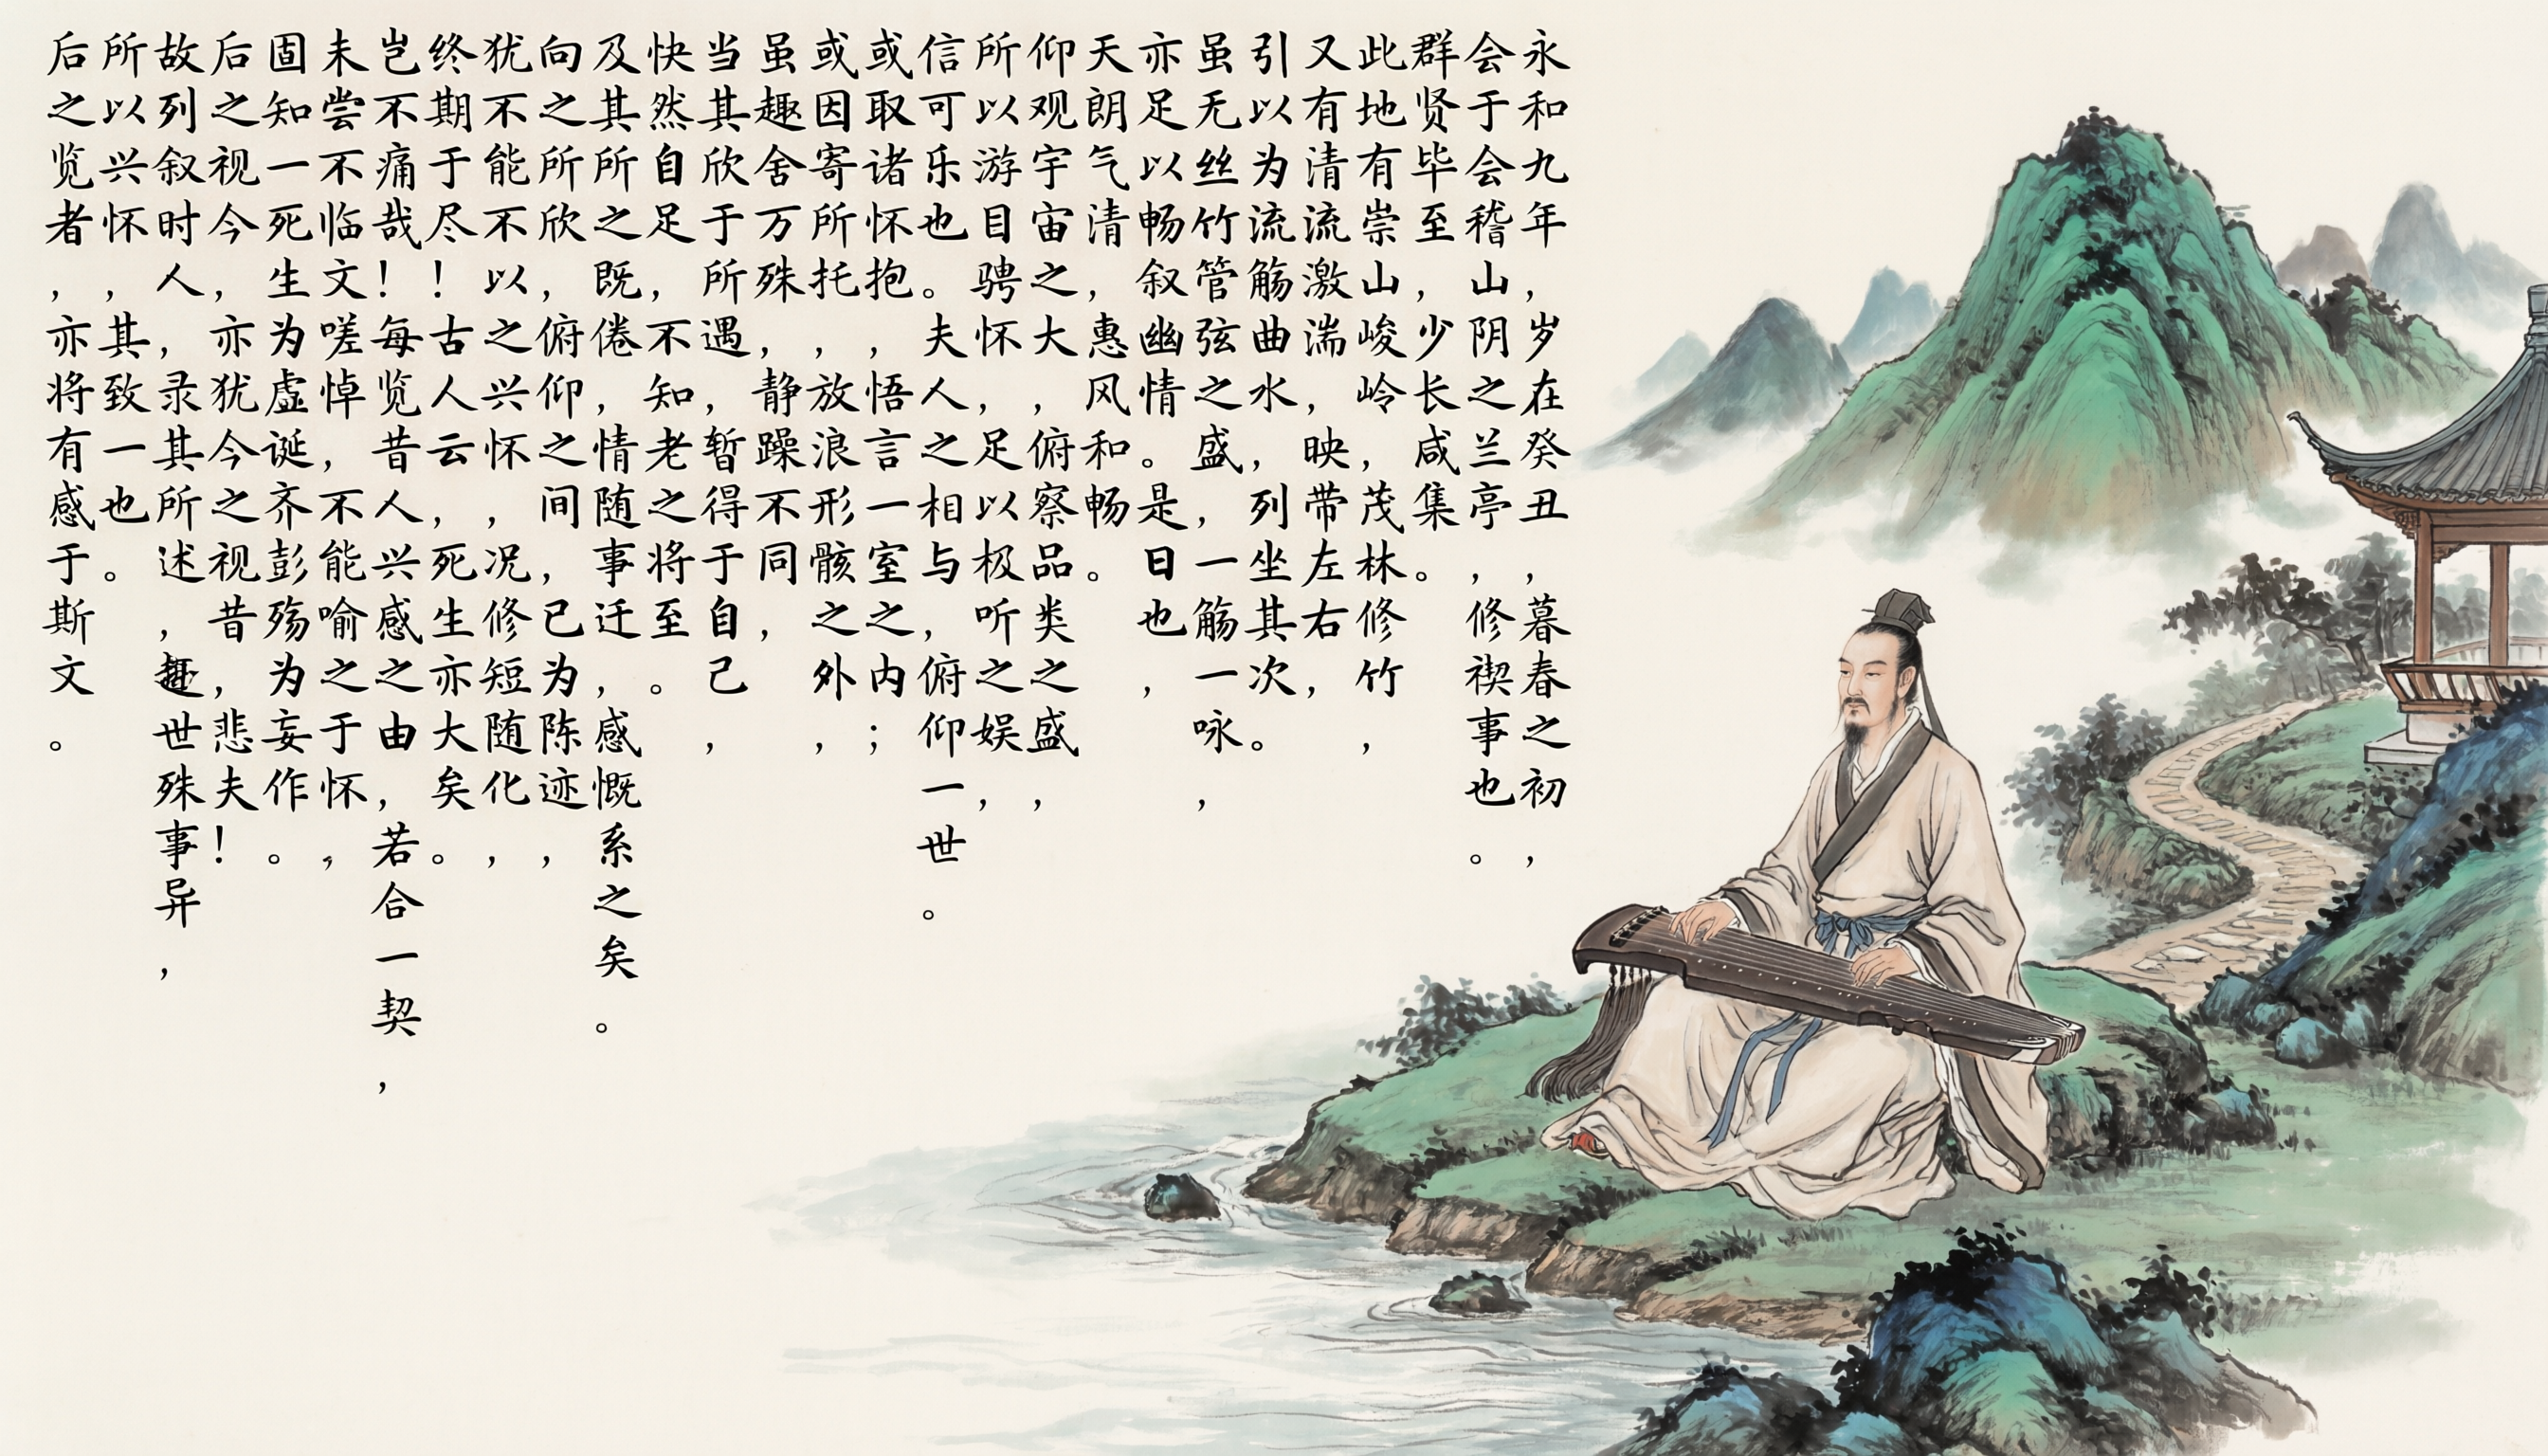
When generating mixed text-and-image compositions, the model tends to render text in blank areas to avoid obscuring the main visual subject. Additionally, the model supports multiple calligraphic styles—for instance, using Emperor Huizong of Song’s distinctive “Slender Gold” script to write his ci poem Tan Chun Ling:
As shown, Qwen-Image-2.0 accurately renders nearly the entire Preface in small regular script, with only a handful of characters imperfect.
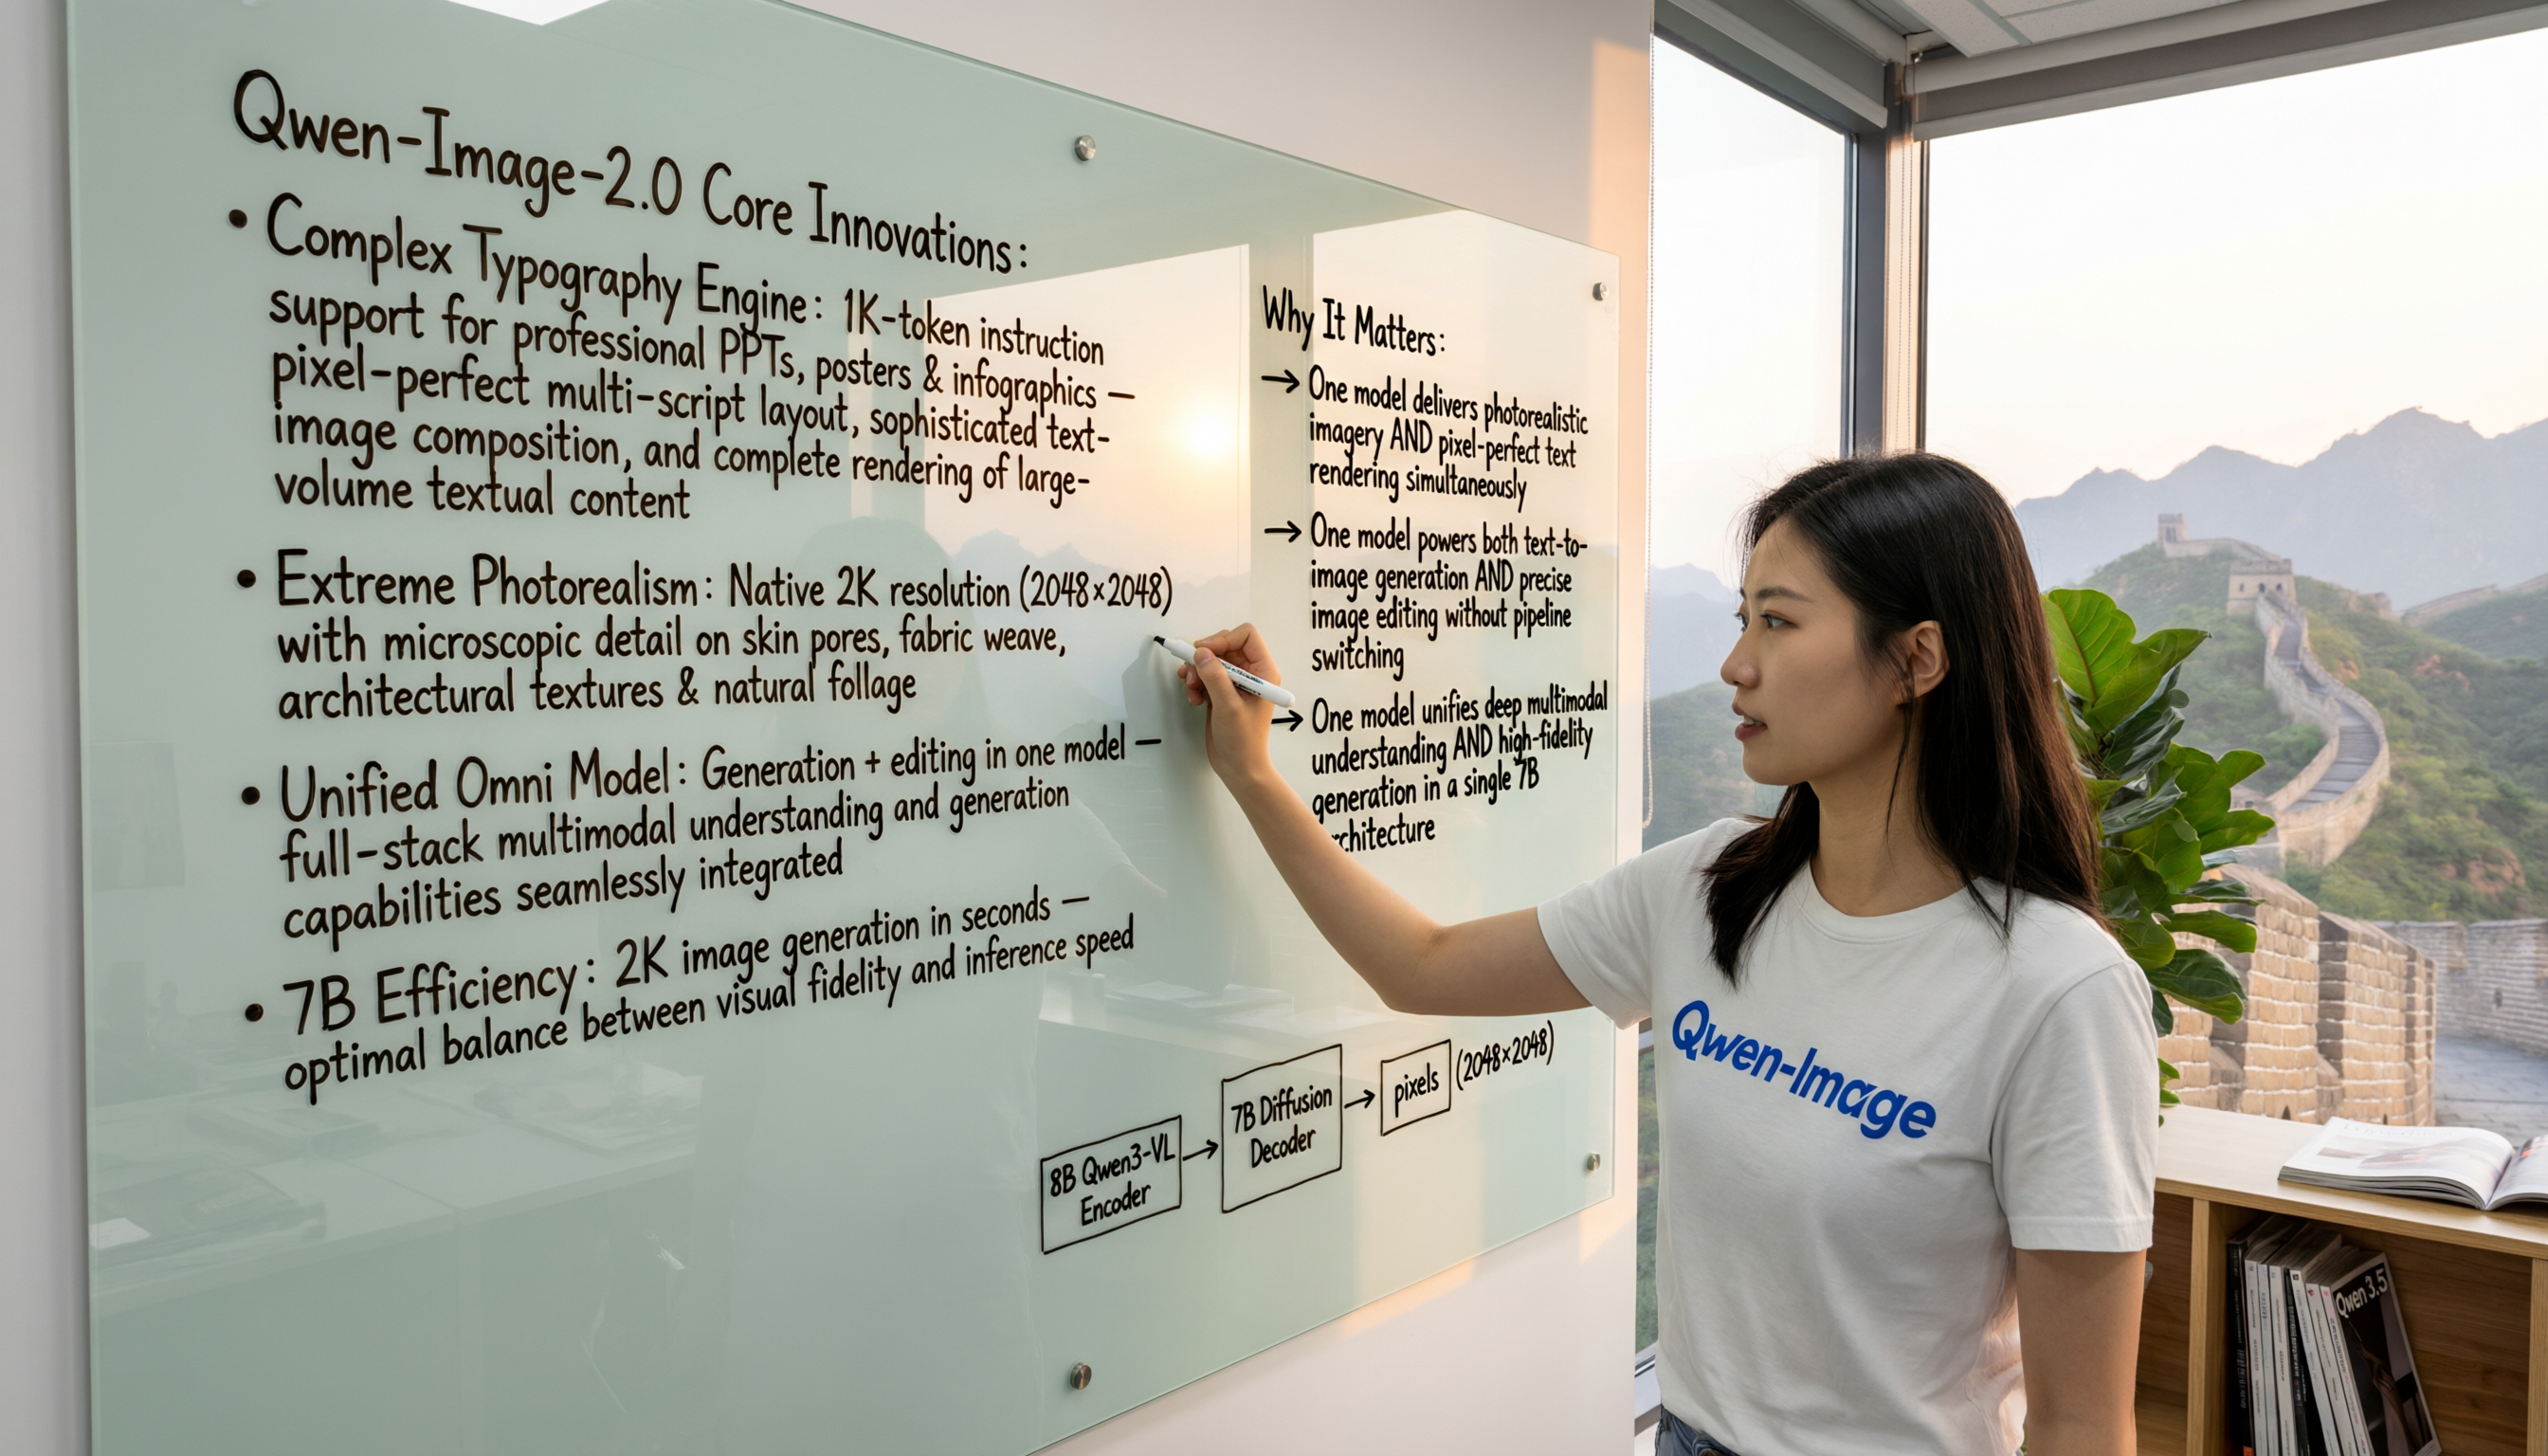
Beyond “precision,” “complexity,” “aesthetics,” and “alignment,” another characteristic of Qwen-Image-2.0’s text rendering is realism (“真”). Consider this prompt:
A wide-angle smartphone photograph of a modern glass whiteboard mounted on a wall inside a bright, airy office room with floor-to-ceiling windows overlooking the Great Wall of China winding across misty mountain ridges at golden hour — warm sunlight casts soft reflections and long shadows across the scene.\nCentered in the frame, a woman in her late 20s wearing a relaxed-fit white t-shirt prominently featuring a sleek “Qwen-Image” logo in gradient blue typography is writing on the board with a fine-tip magnetic stylus.\nHer handwriting is natural, slightly imperfect, and expressive — with visible pressure variation, subtle smudges, and organic line weight — conveying authentic human authorship.\nIn the lower-left corner of the glass surface, the photographer’s faint but unmistakable reflection appears: blurred outline of a person holding a phone at arm’s length, capturing the moment.\n\nOn the left side of the whiteboard, clean, legible handwritten text appears in dark gray marker with exceptional stroke fidelity:\n’Qwen-Image-2.0 Core Innovations:\n• Complex Typography Engine: 1K-token instruction support for professional PPTs, posters & infographics — pixel-perfect multi-script layout, sophisticated text-image composition, and complete rendering of large-volume textual content\n• Extreme Photorealism: Native 2K resolution (2048×2048) with microscopic detail on skin pores, fabric weave, architectural textures & natural foliage\n• Unified Omni Model: Generation + editing in one model — full-stack multimodal understanding and generation capabilities seamlessly integrated\n• 7B Efficiency: 2K image generation in seconds — optimal balance between visual fidelity and inference speed’\n\nOn the right side of the whiteboard, vertically aligned technical notes in crisp marker:\n’Why It Matters:\n→ One model delivers photorealistic imagery AND pixel-perfect text rendering simultaneously\n→ One model powers both text-to-image generation AND precise image editing without pipeline switching\n→ One model unifies deep multimodal understanding AND high-fidelity generation in a single 7B architecture’\n\nIn the bottom-right corner, a hand-drawn schematic in precise strokes:\n’[8B Qwen3-VL Encoder] → [7B Diffusion Decoder] → pixels (2048×2048)’\n— arrows flow with perspective depth, boxes feature soft shading, resolution specs annotated in fine print.\n\nThe glass surface exhibits realistic optical properties.\nBackground includes minimalist wooden shelving with design magazines open to full-bleed infographics — one prominently displays a crisp cover reading “Qwen 3.5” in bold modern typography — and a potted fiddle-leaf fig with individually rendered leaf veins partially visible out-of-focus.
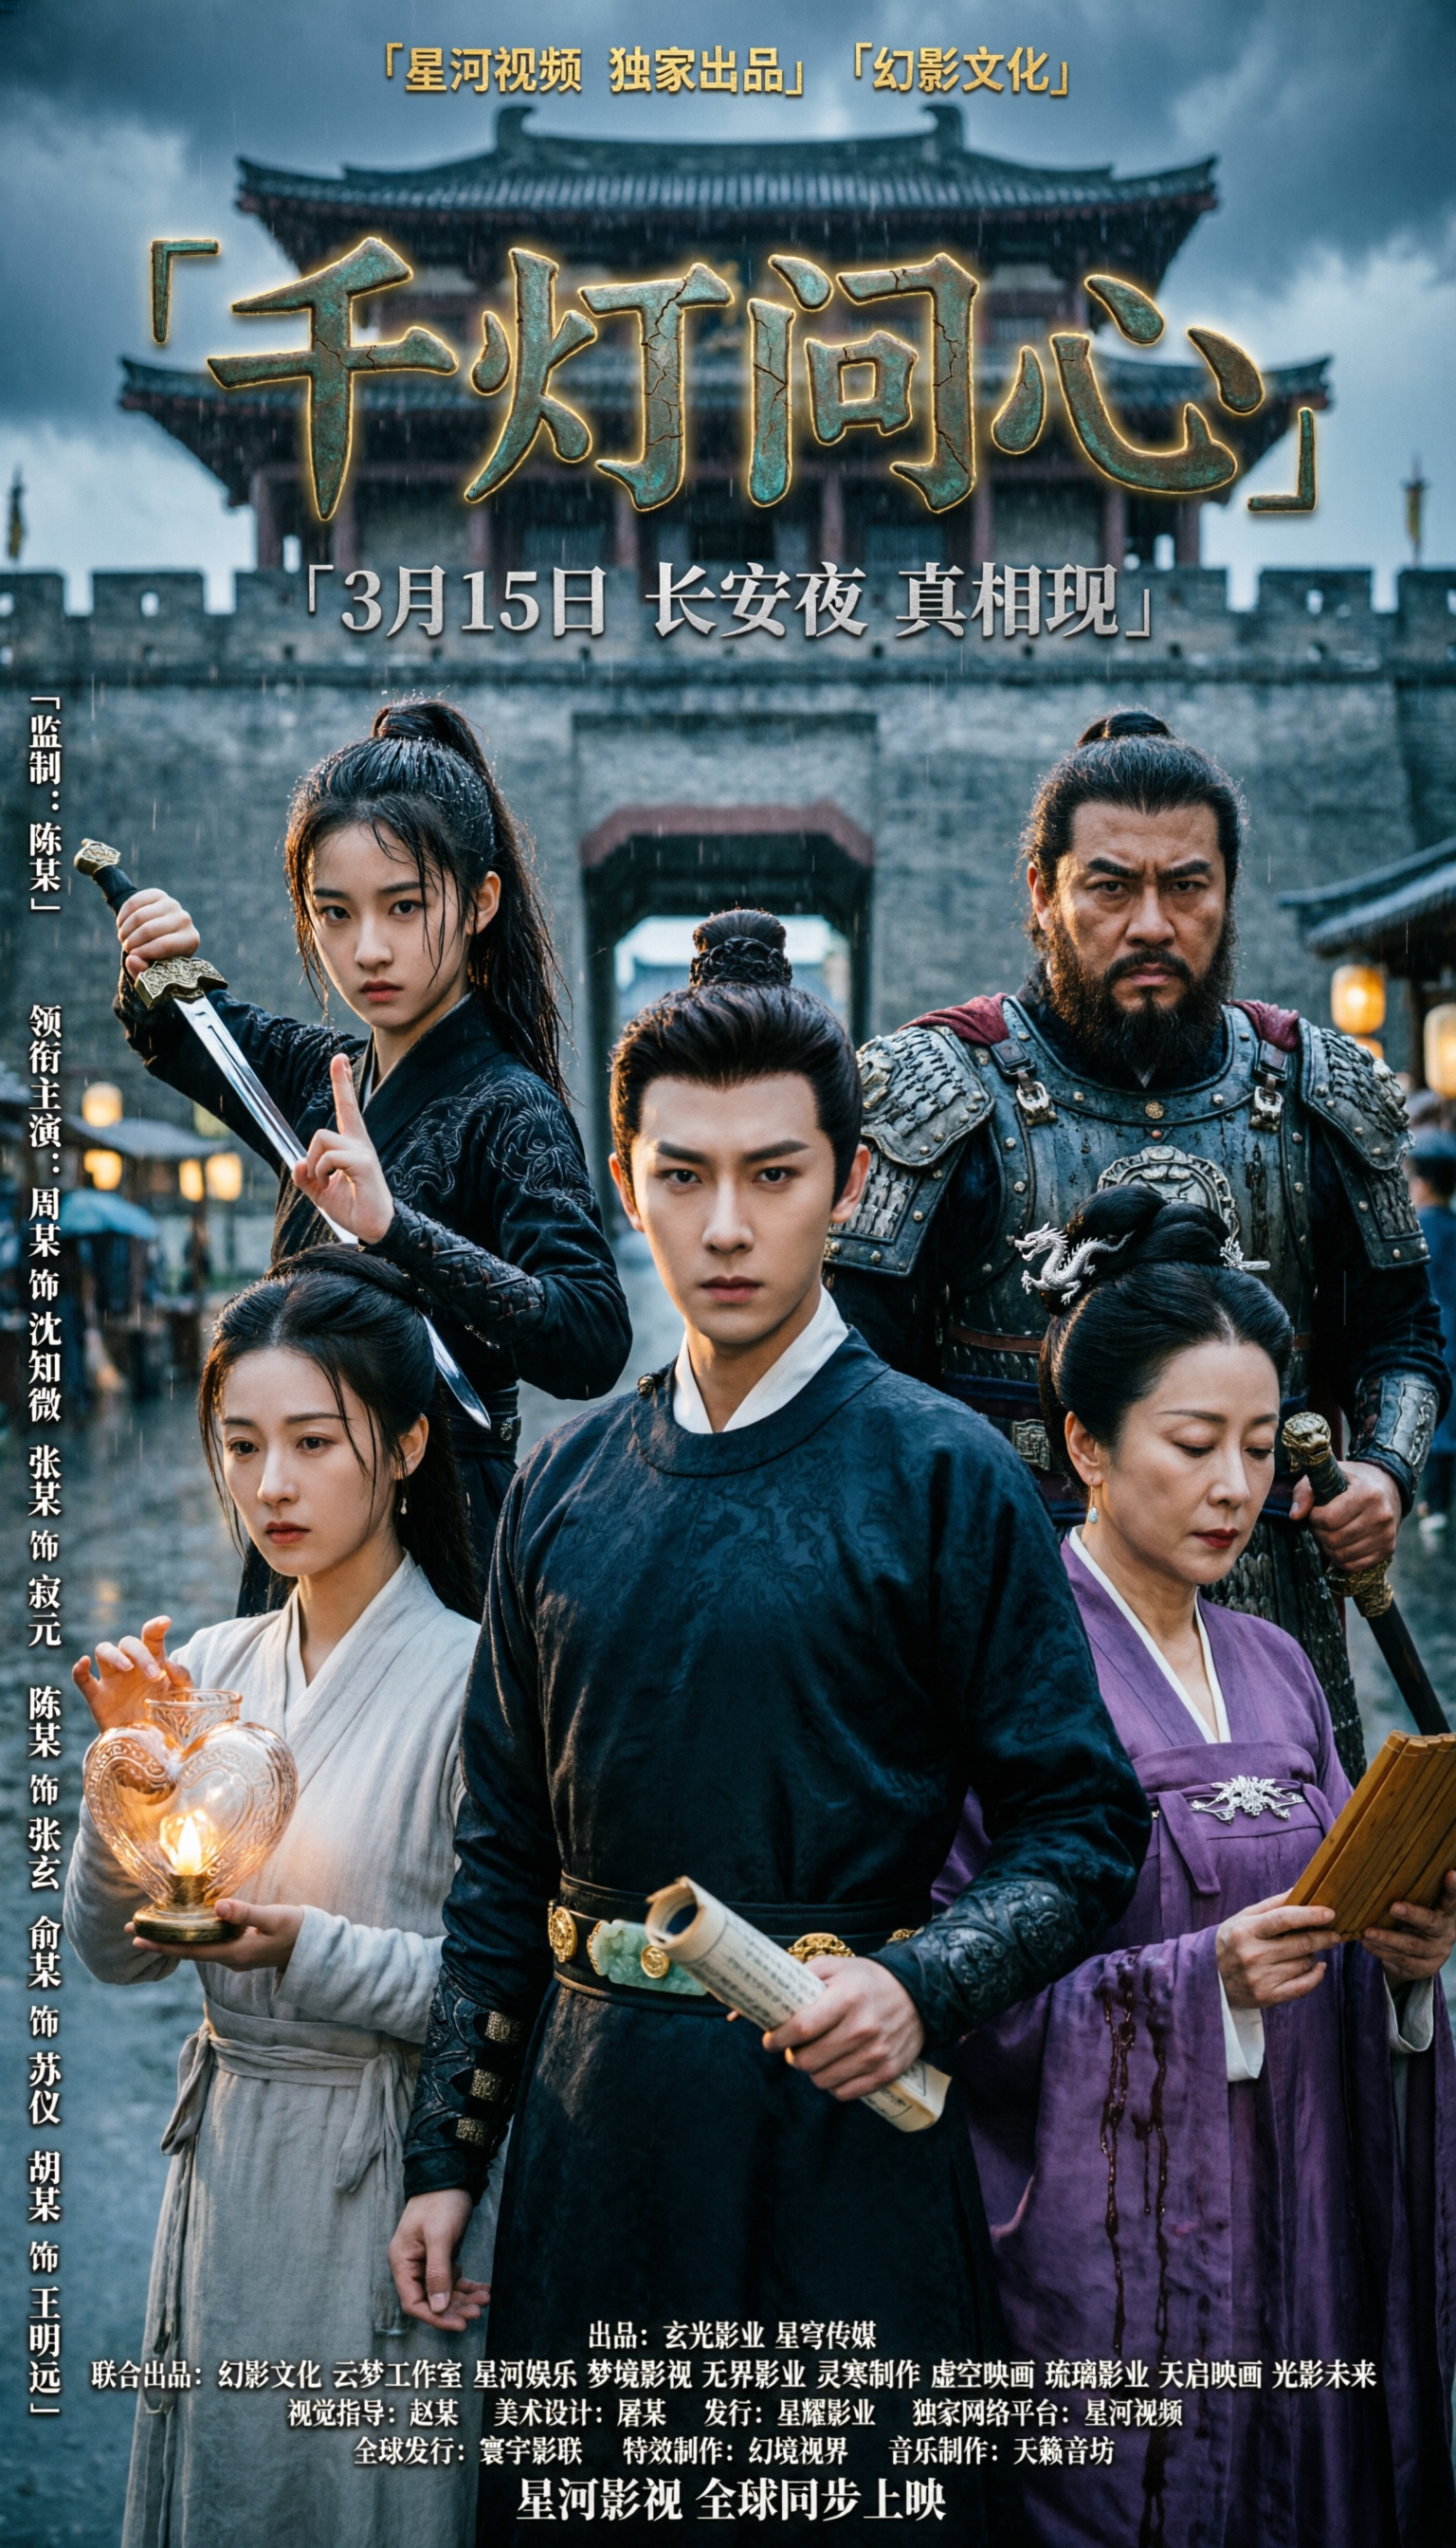
In this example, the model renders text across multiple media types: on glass whiteboards, clothing, and magazine covers. These surfaces differ in material properties and spatial orientation, yet Qwen-Image-2.0 accurately renders text on each while preserving realistic lighting, reflections, and perspective—greatly enhancing the authenticity of the generated image. This realism also shines when photorealistic imagery and text coexist, as in movie posters:
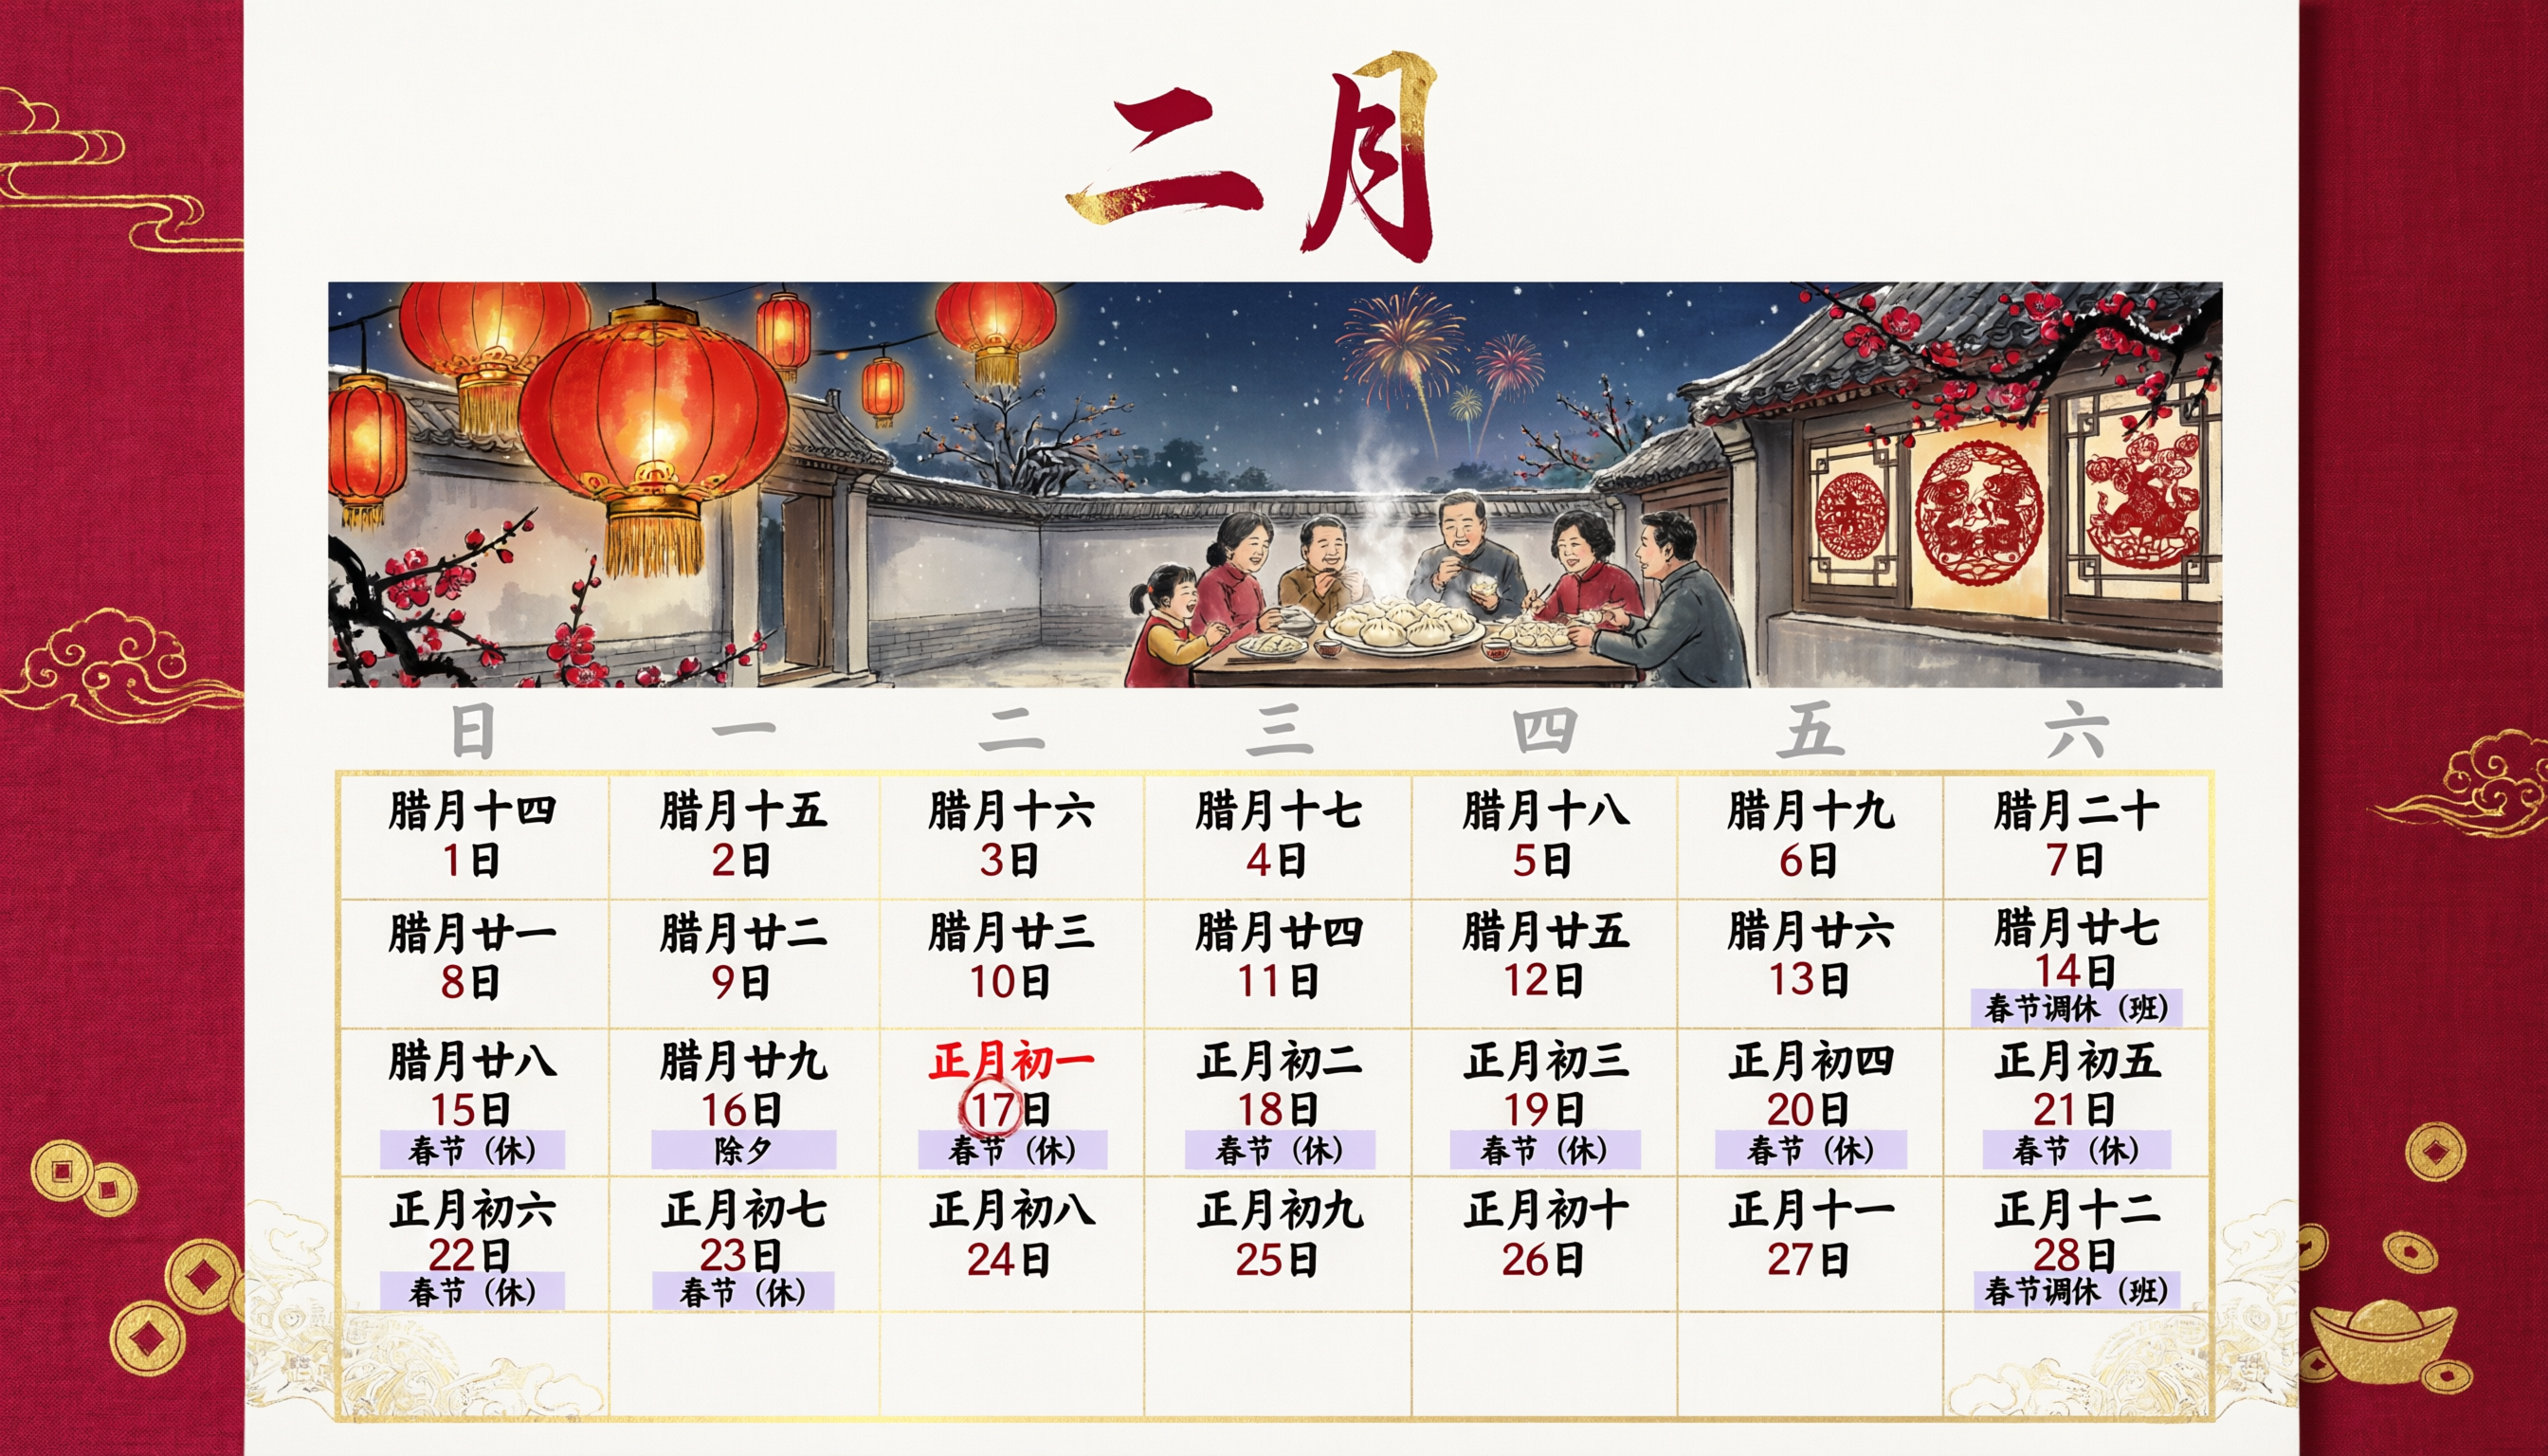
Beyond “precision,” “complexity,” “aesthetics,” and “realism,” Qwen-Image-2.0 also excels at alignment and organization (“齐”). Consider this example:
Chinese ink painting calendar for February 2026, vertical composition on crimson silk texture with gold foil accents, festive vermilion and gold palette:
TOP SECTION: Bold vermilion calligraphy “二月” centered at top with subtle gold leaf shimmer.
MIDDLE SECTION: Glowing red lanterns floating above ancient courtyard at night, family reunion scene with steaming dumplings on wooden table, distant fireworks illuminating indigo sky with snowflakes, plum blossoms framing composition, traditional paper-cut window decorations visible through lattice windows.
BOTTOM SECTION: Clean 7-column calendar grid with 6 rows, subtle grid lines in pale gold, each cell containing Chinese text as follows:
Row 1 (weekdays header in pale grey): “日” “一” “二” “三” “四” “五” “六”
Row 2: - Sunday cell: “腊月十四 1日” - Monday cell: “腊月十五 2日” - Tuesday cell: “腊月十六 3日” - Wednesday cell: “腊月十七 4日” - Thursday cell: “腊月十八 5日” - Friday cell: “腊月十九 6日” - Saturday cell: “腊月二十 7日”
Row 3: - Sunday cell: “腊月廿一 8日” - Monday cell: “腊月廿二 9日” - Tuesday cell: “腊月廿三 10日” - Wednesday cell: “腊月廿四 11日” - Thursday cell: “腊月廿五 12日” - Friday cell: “腊月廿六 13日” - Saturday cell: “腊月廿七 14日” with light purple background rectangle underneath text labeled “春节调休(班)”
Row 4: - Sunday cell: “腊月廿八 15日” with light purple background rectangle underneath text labeled “春节(休)” - Monday cell: “腊月廿九 16日” with light purple background rectangle underneath text labeled “除夕” - Tuesday cell: “正月初一 17日” with light purple background rectangle underneath text labeled “春节(休)” and red circle surrounding the number “17” - Wednesday cell: “正月初二 18日” with light purple background rectangle underneath text labeled “雨水” and light purple background rectangle underneath text labeled “春节(休)” - Thursday cell: “正月初三 19日” with light purple background rectangle underneath text labeled “春节(休)” - Friday cell: “正月初四 20日” with light purple background rectangle underneath text labeled “春节(休)” - Saturday cell: “正月初五 21日” with light purple background rectangle underneath text labeled “春节(休)”
Row 5: - Sunday cell: “正月初六 22日” with light purple background rectangle underneath text labeled “春节(休)” - Monday cell: “正月初七 23日” with light purple background rectangle underneath text labeled “春节(休)” - Tuesday cell: “正月初八 24日” - Wednesday cell: “正月初九 25日” - Thursday cell: “正月初十 26日” - Friday cell: “正月十一 27日” - Saturday cell: “正月十二 28日” with light purple background rectangle underneath text labeled “春节调休(班)”
Row 6: (empty row for visual balance, subtle decorative pattern of gold coins and ingots)
Minimalist negative space with auspicious cloud motifs in corners, traditional woodblock print aesthetic with gold foil accents, all text in elegant Song typeface with vermilion red for dates and deep black for lunar dates, subtle rice paper texture overlay
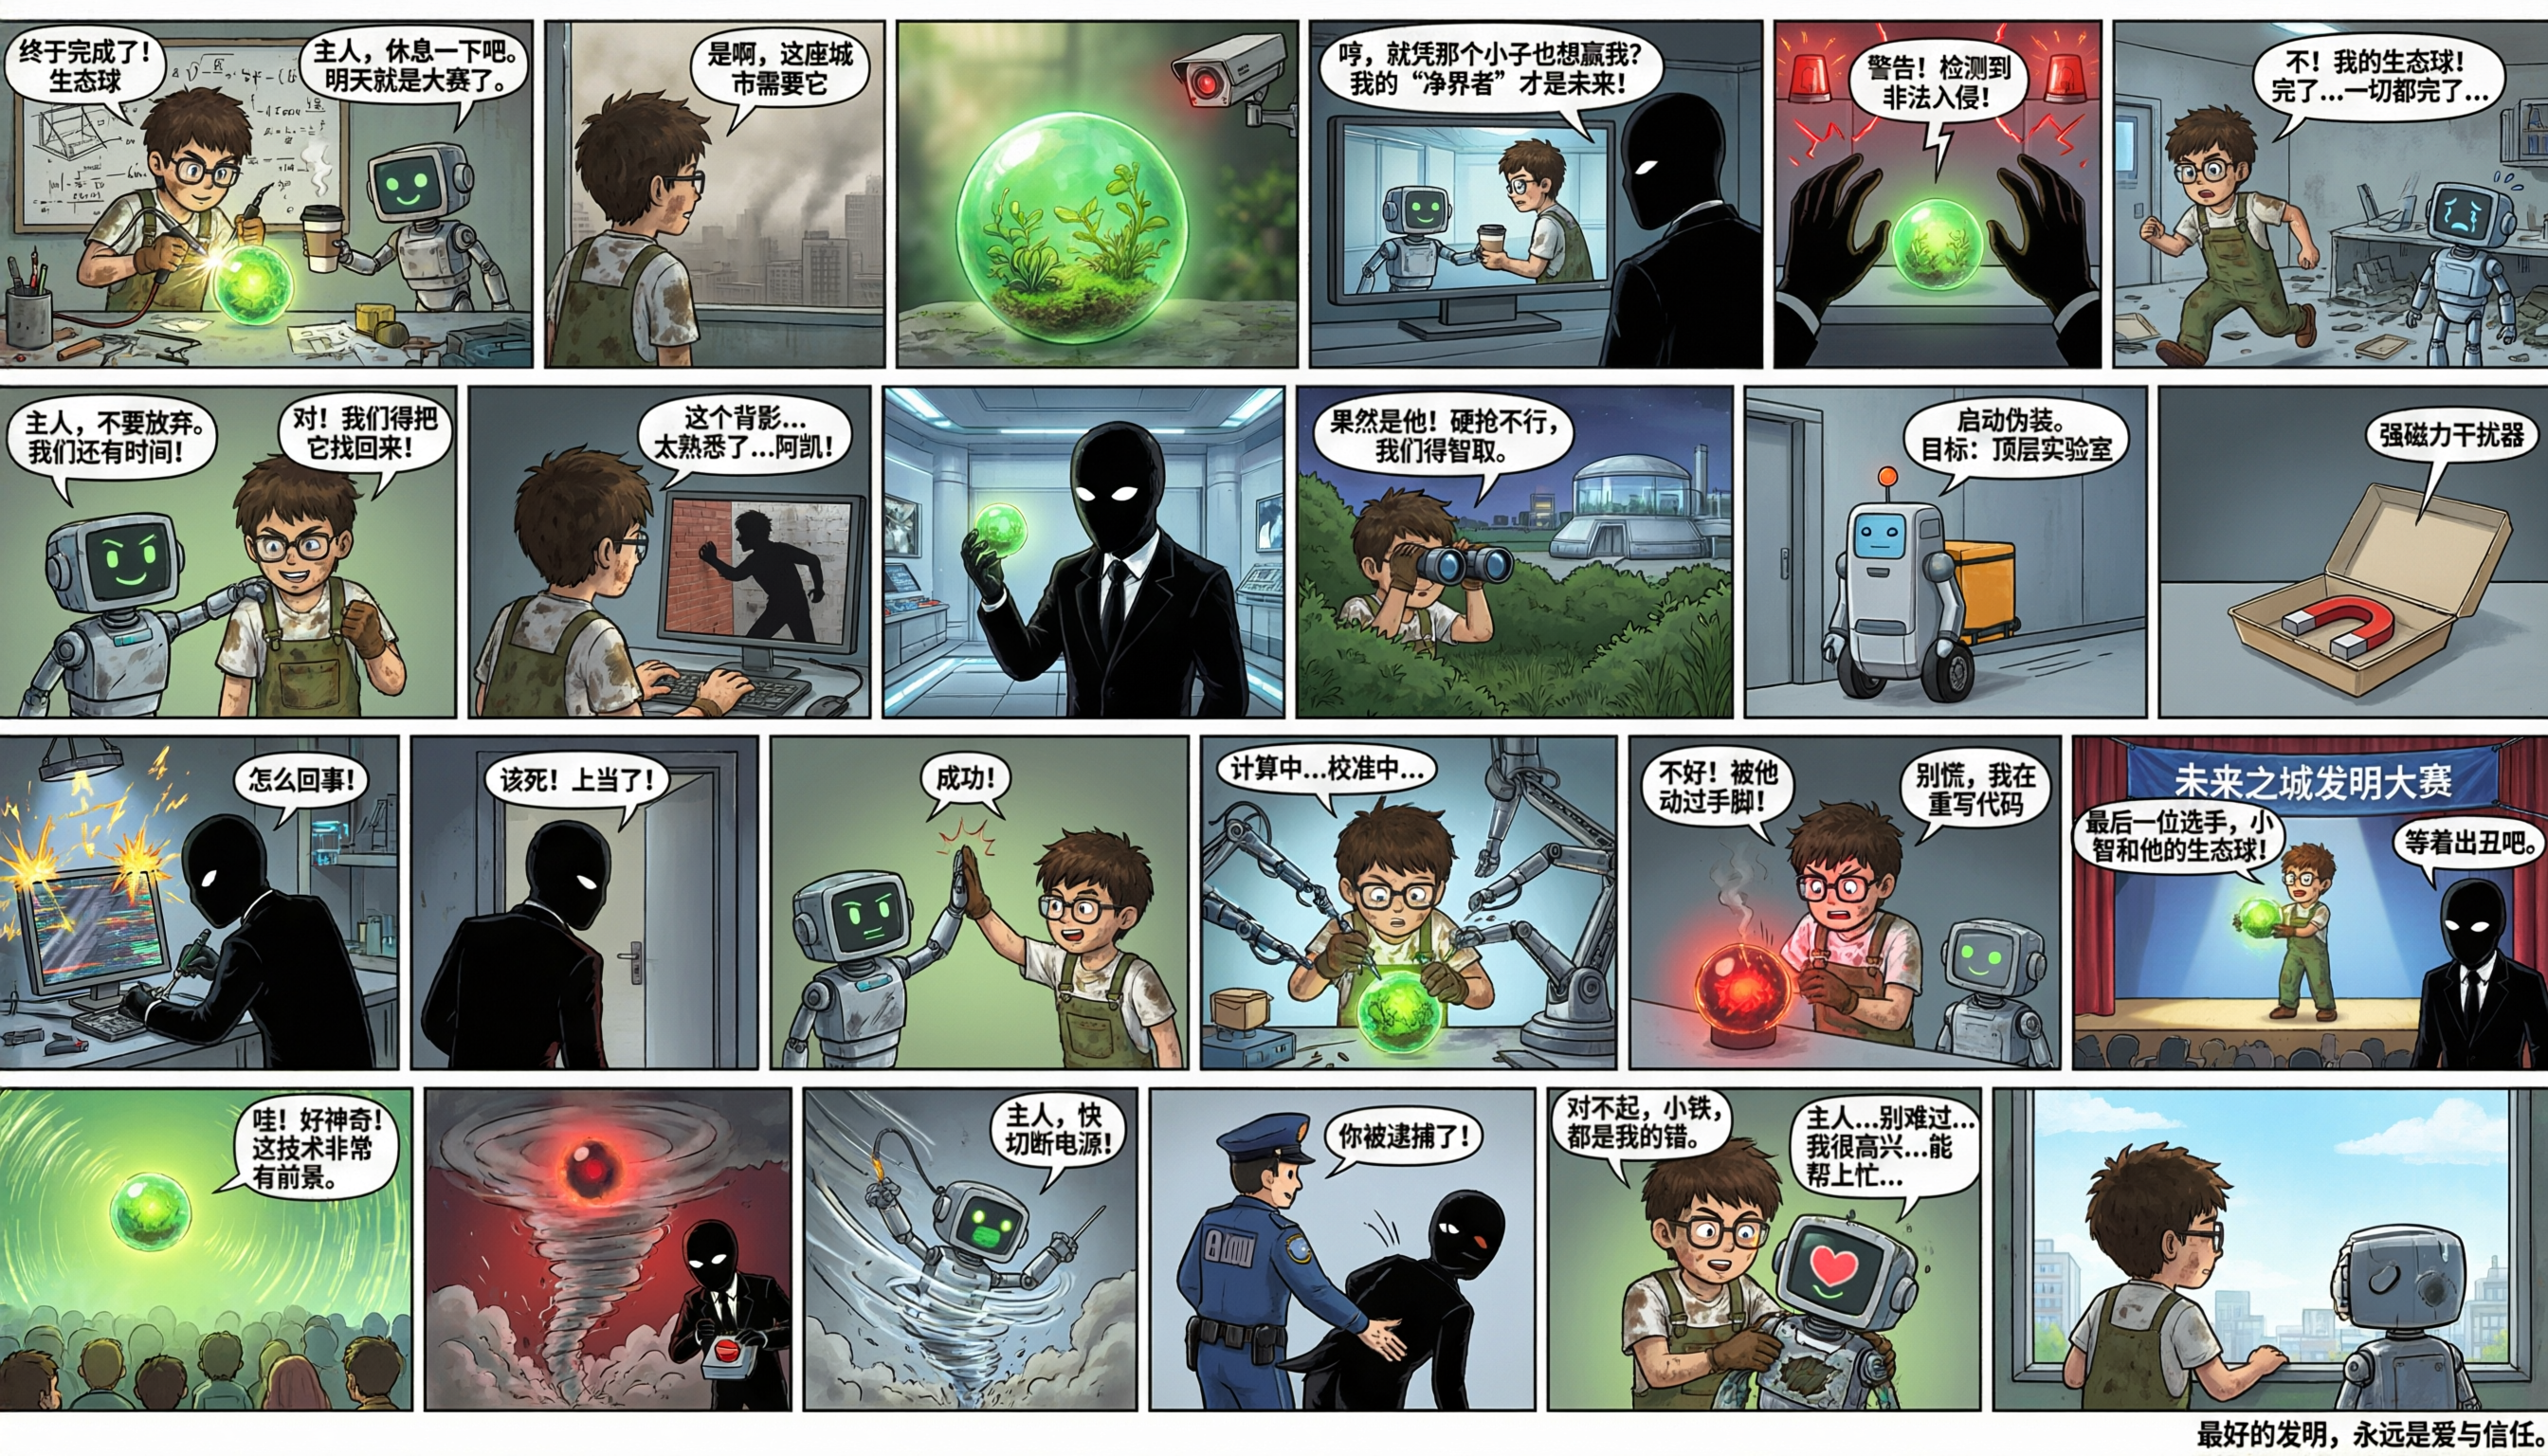
In this example, all text elements are precisely aligned within the calendar grid. This alignment capability also applies to comic panels—for instance:
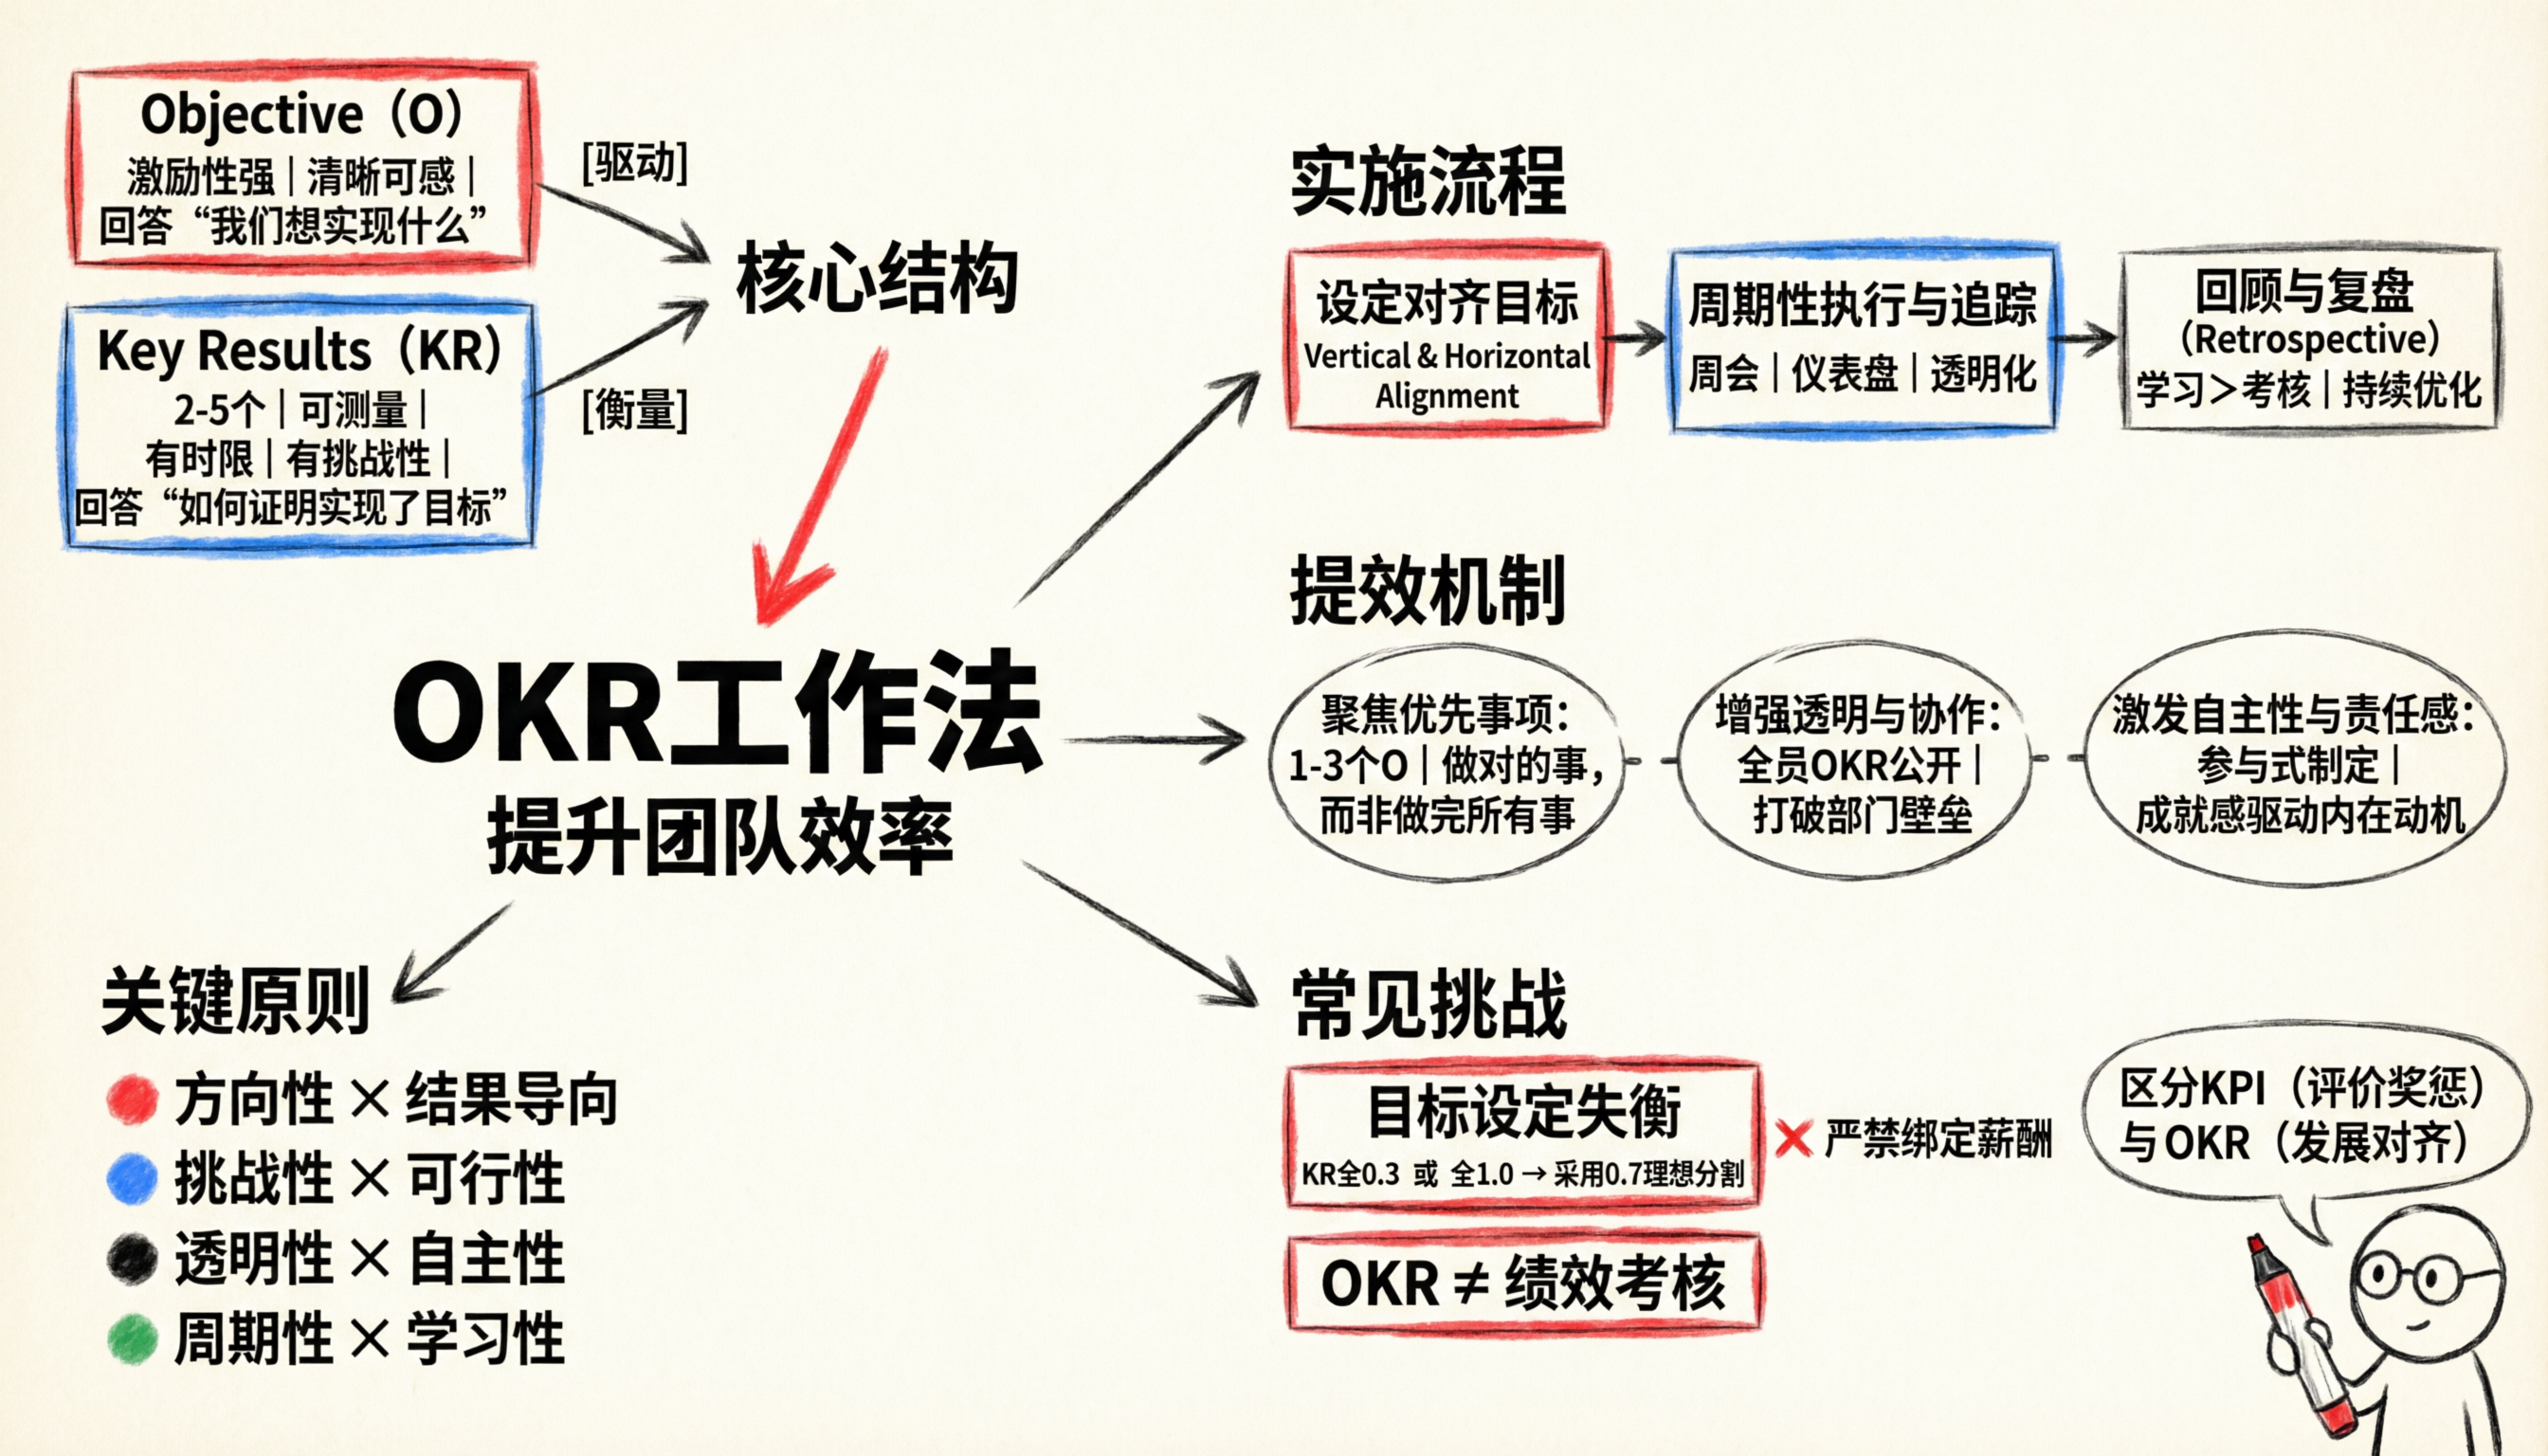
Within each comic panel, dialogue text is neatly arranged and centered inside speech bubbles, creating a natural and professional appearance. Similarly, in the OKR infographic below, similar text blocks are automatically aligned:
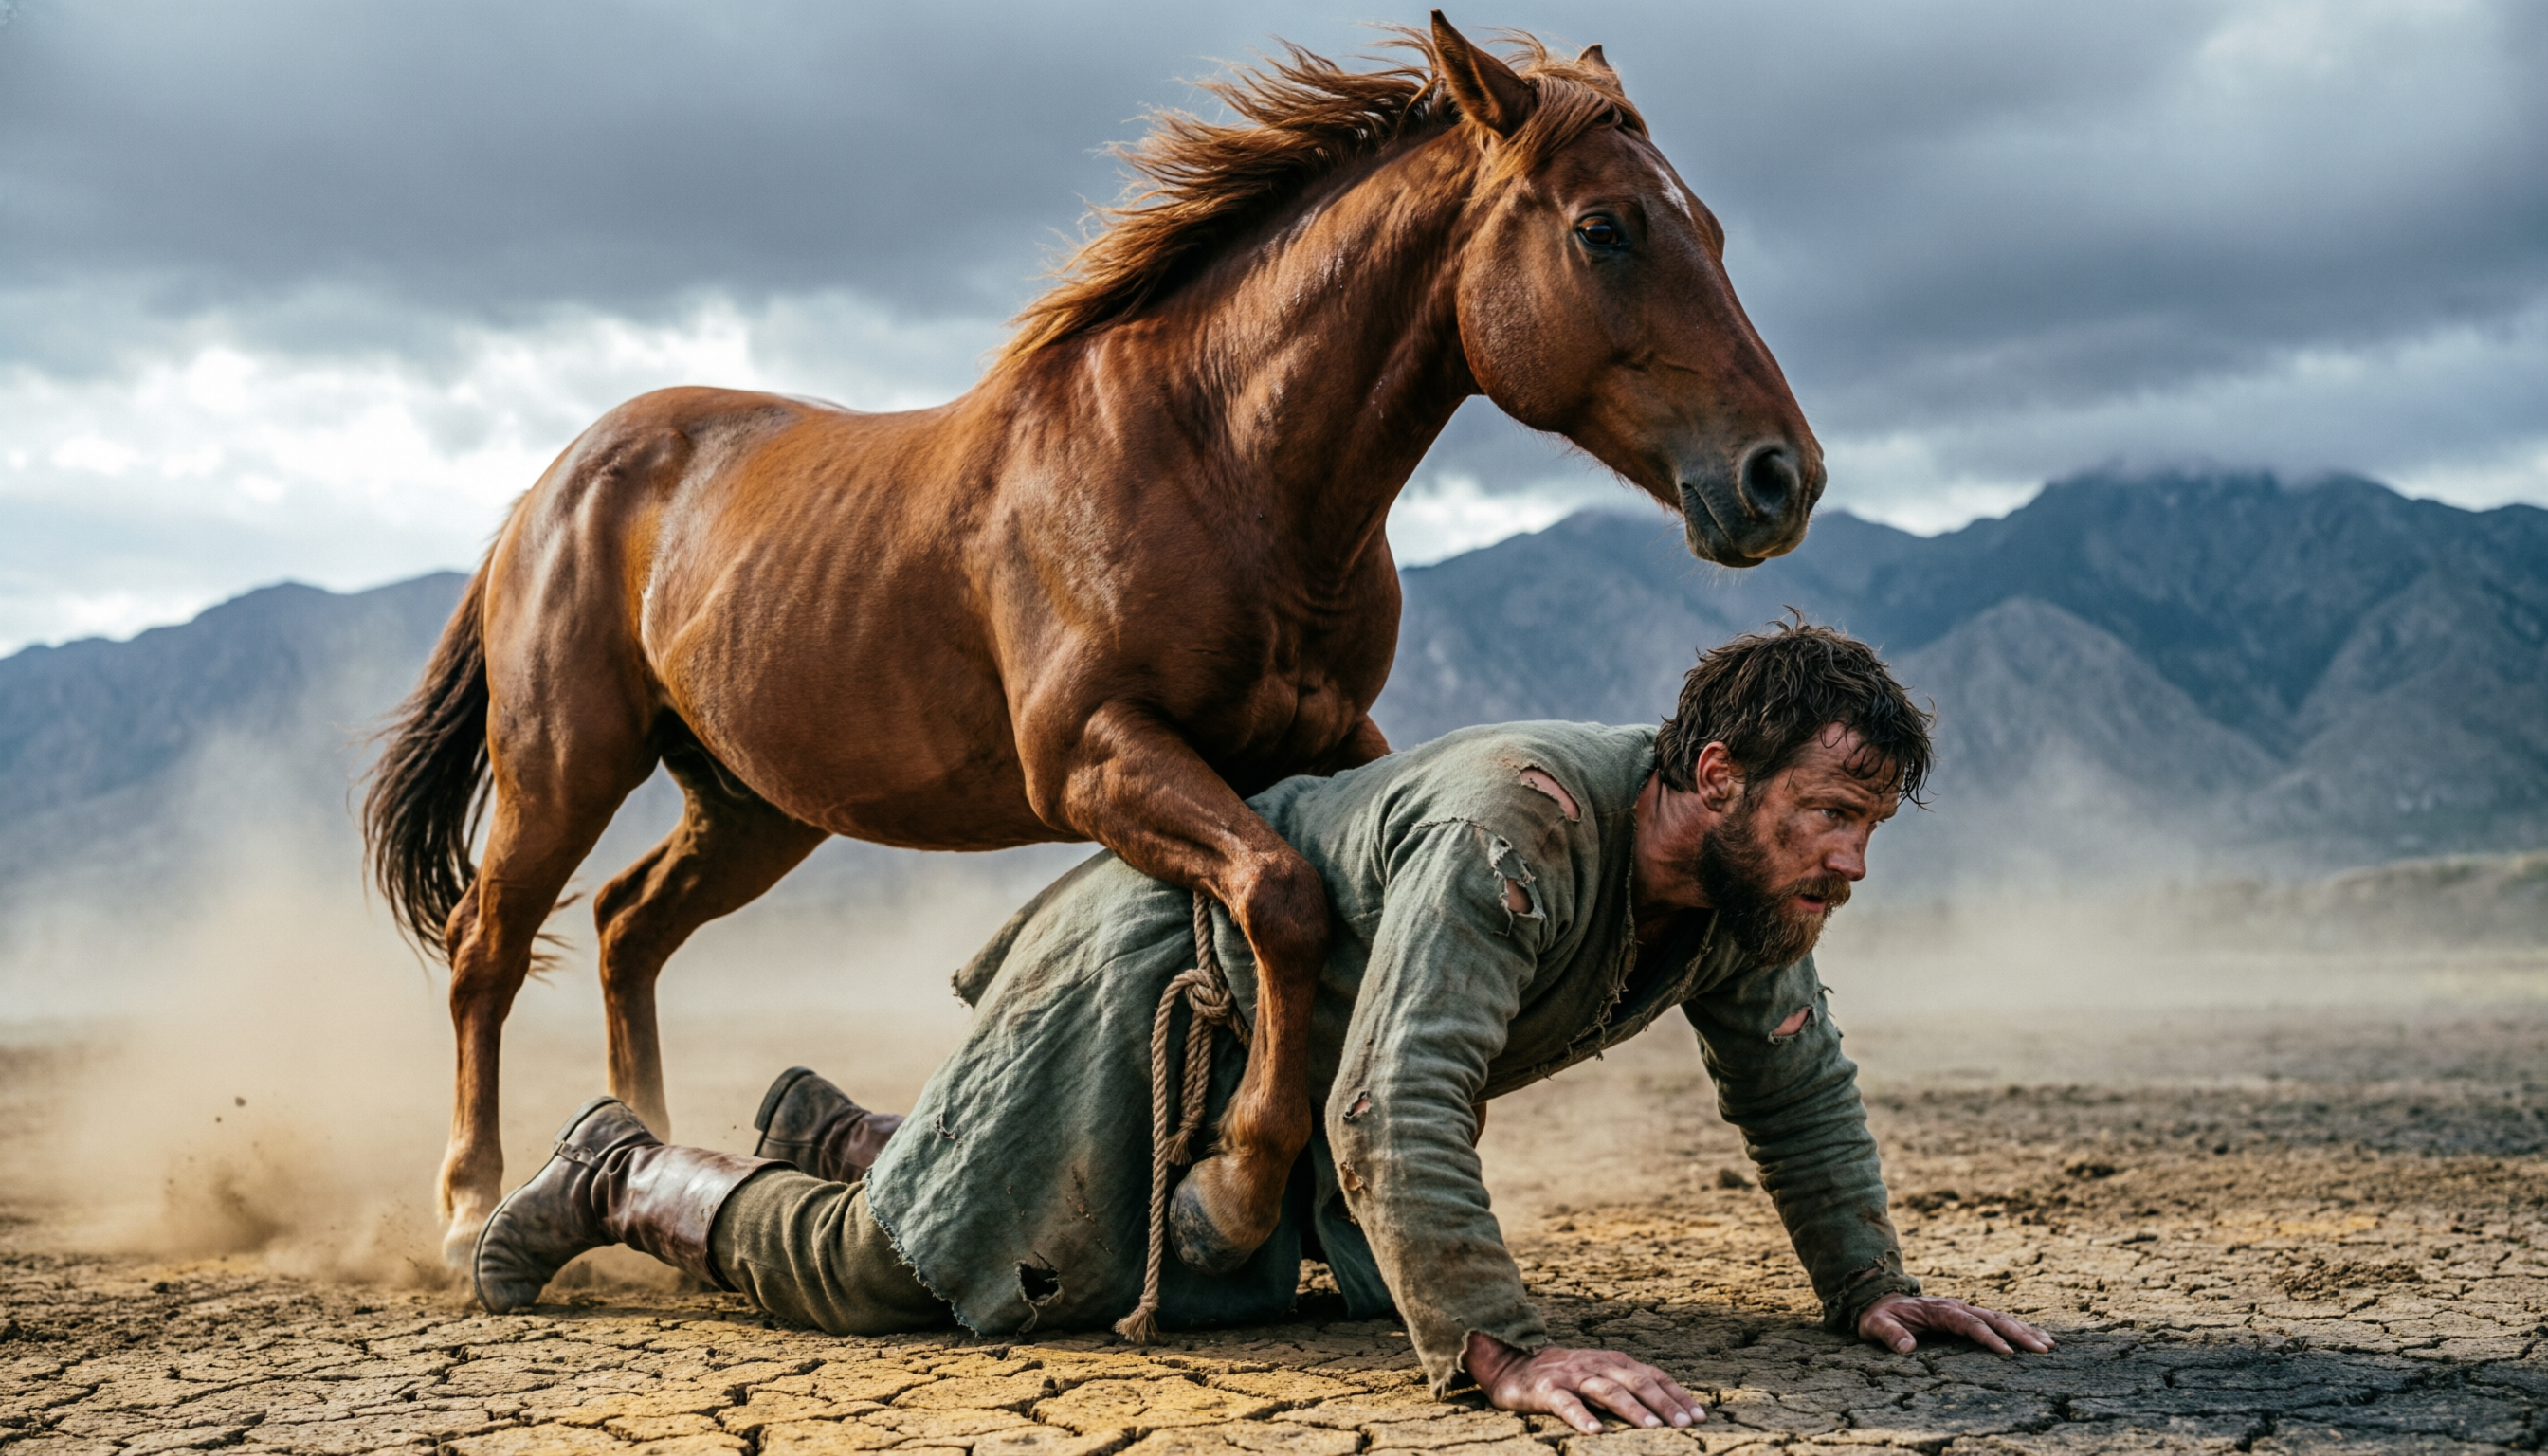
To recap, we’ve introduced five key characteristics of Qwen-Image-2.0’s text rendering capabilities: precision (“准”), complexity (“多”), aesthetics (“美”), realism (“真”), and alignment (“齐”). Beyond text rendering, Qwen-Image-2.0 also delivers significantly improved photorealism in non-text scenarios. For example, in this “horse riding a human” prompt:
Qwen-Image-2.0 not only accurately models the “riding” action but also meticulously renders the horse’s musculature and hair, the man’s facial expression, and the cracked earth texture. Another example:
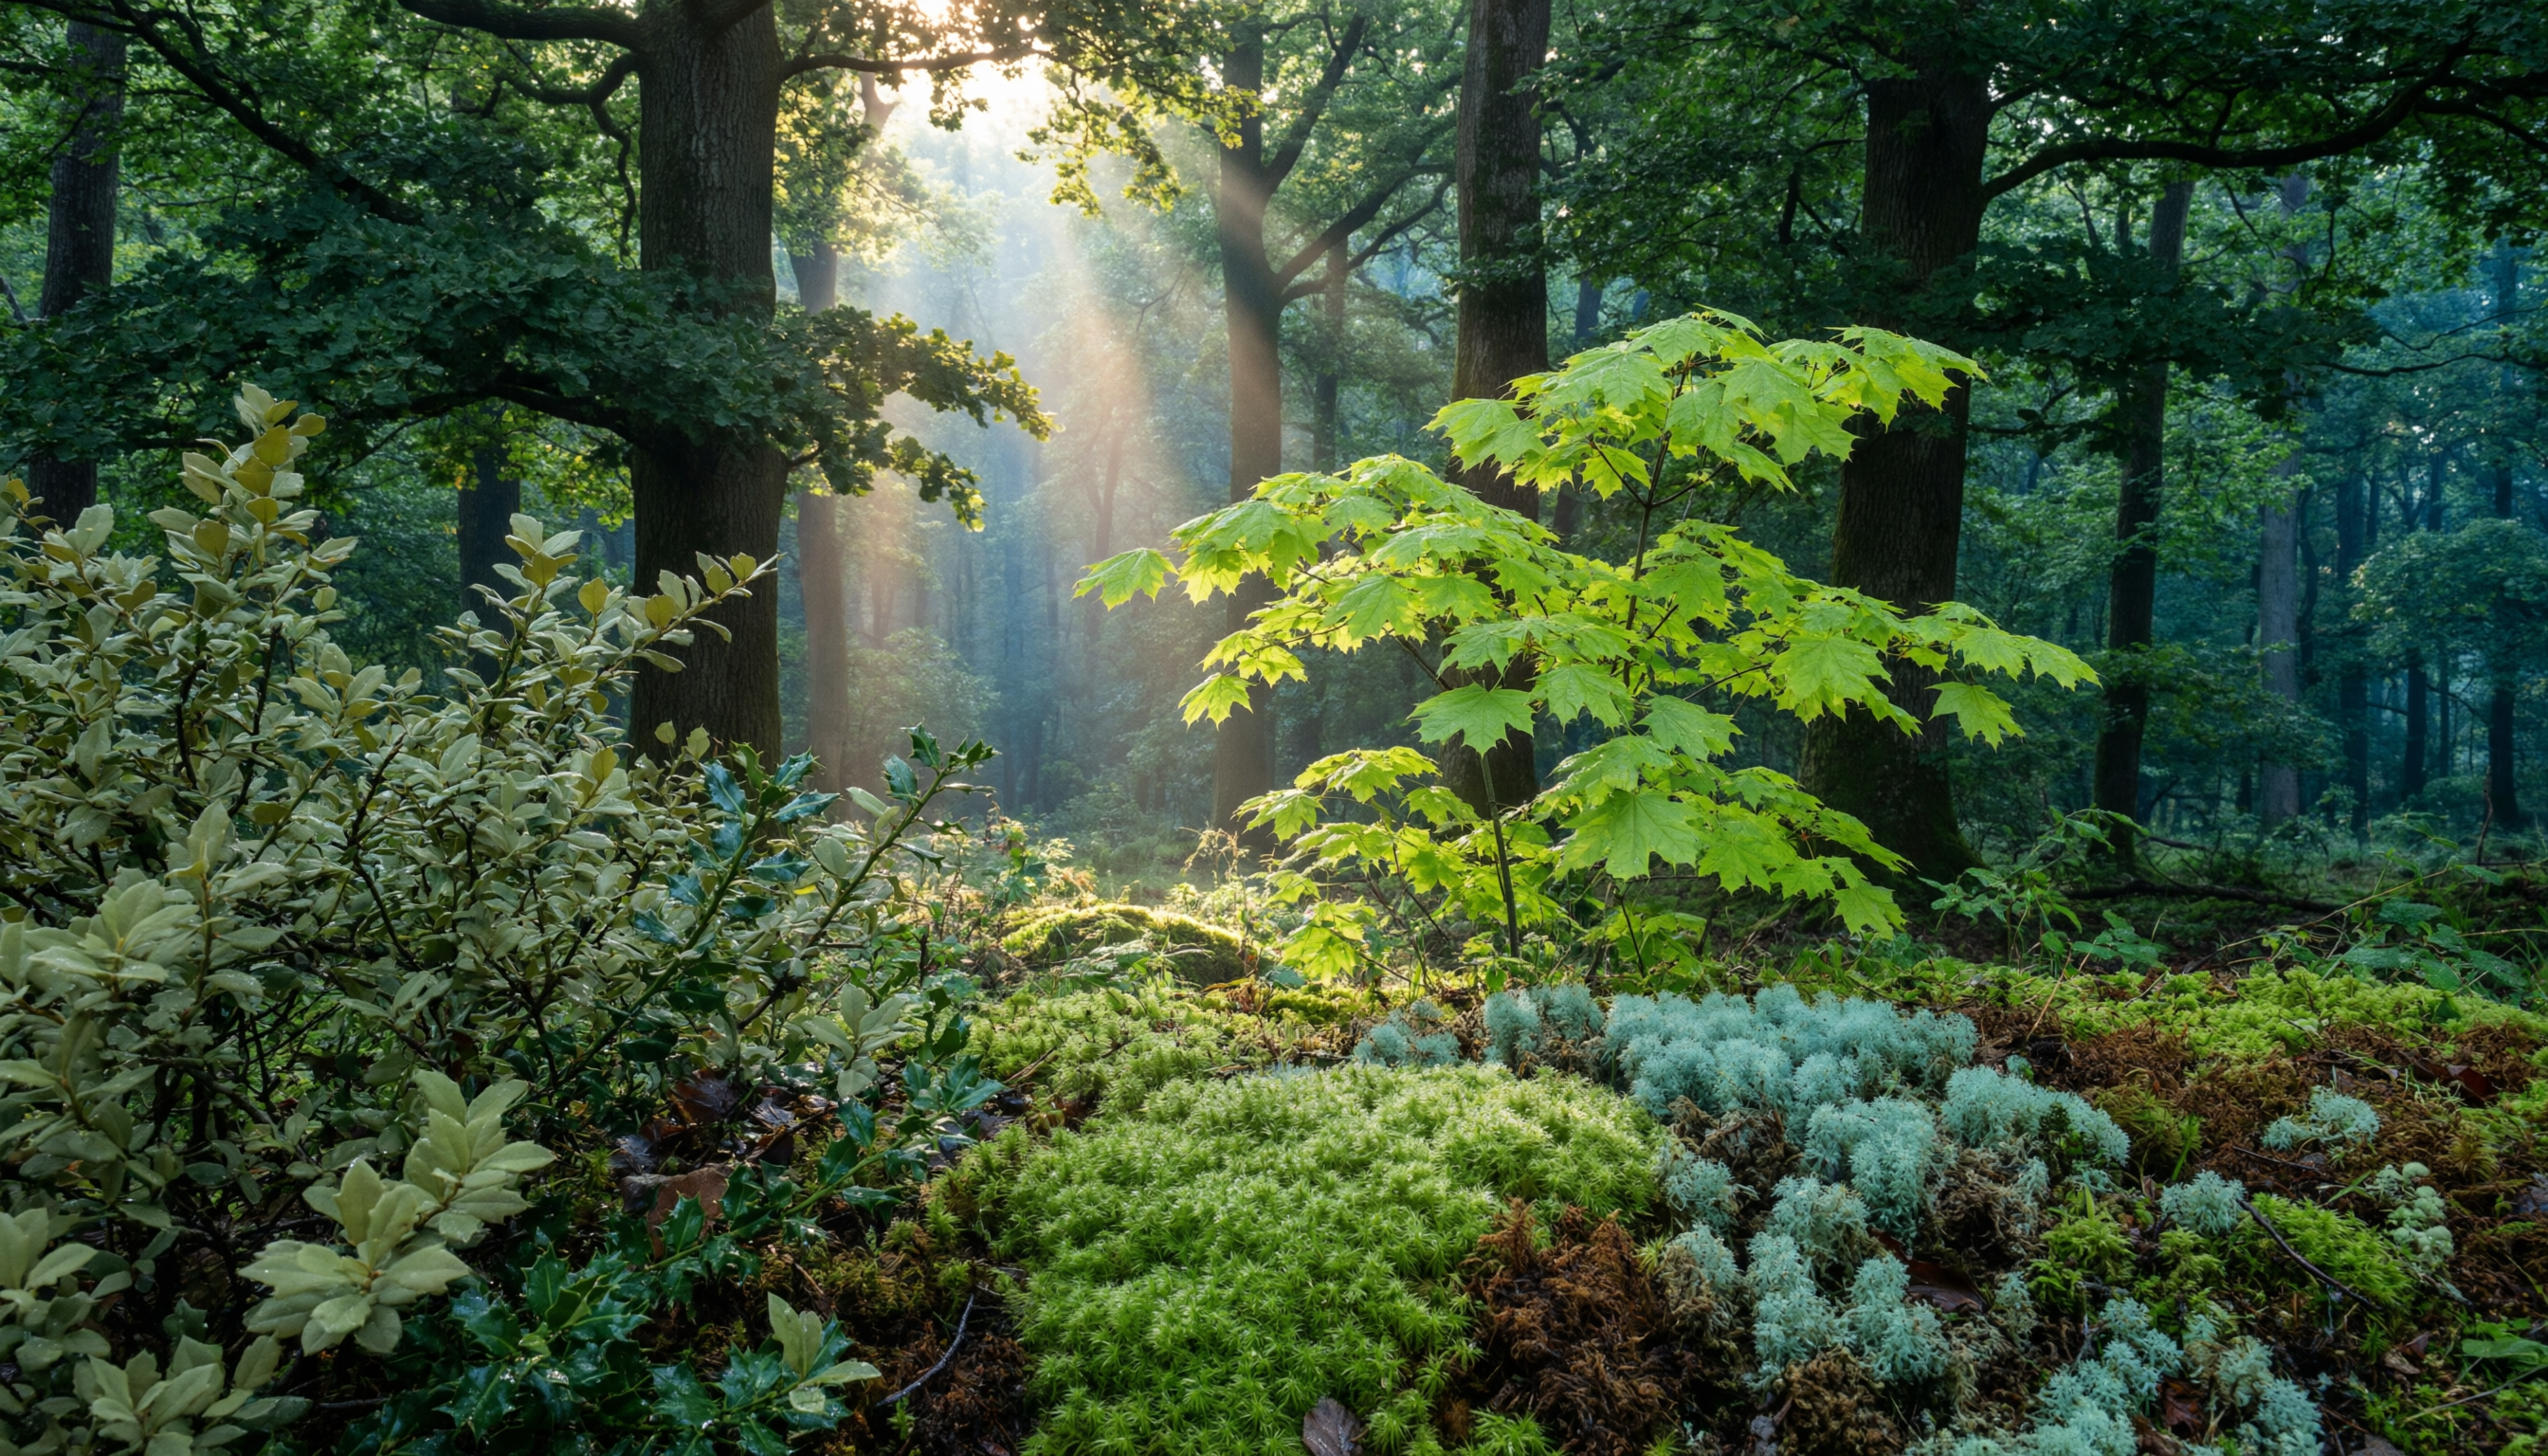
Qwen-Image-2.0 models over 23 distinct shades of green, with natural details rendered in exquisite fidelity.
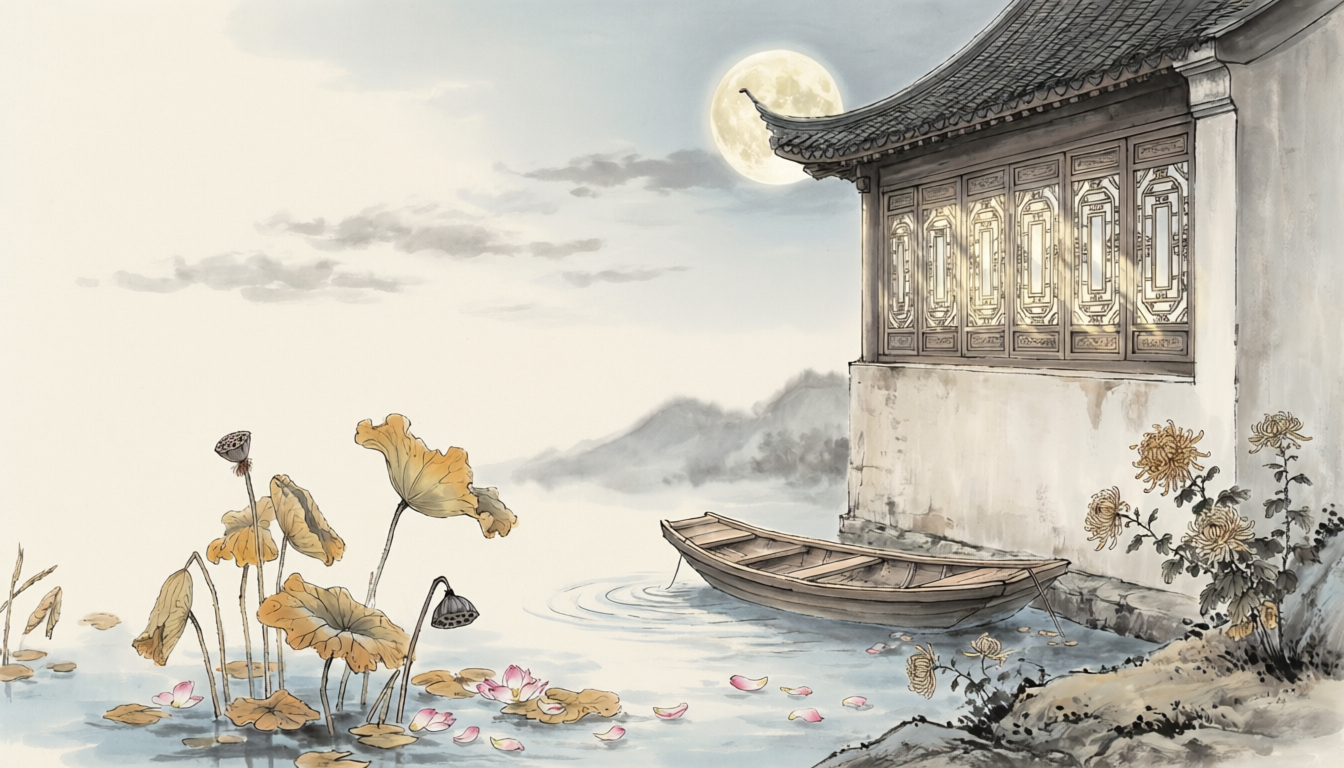
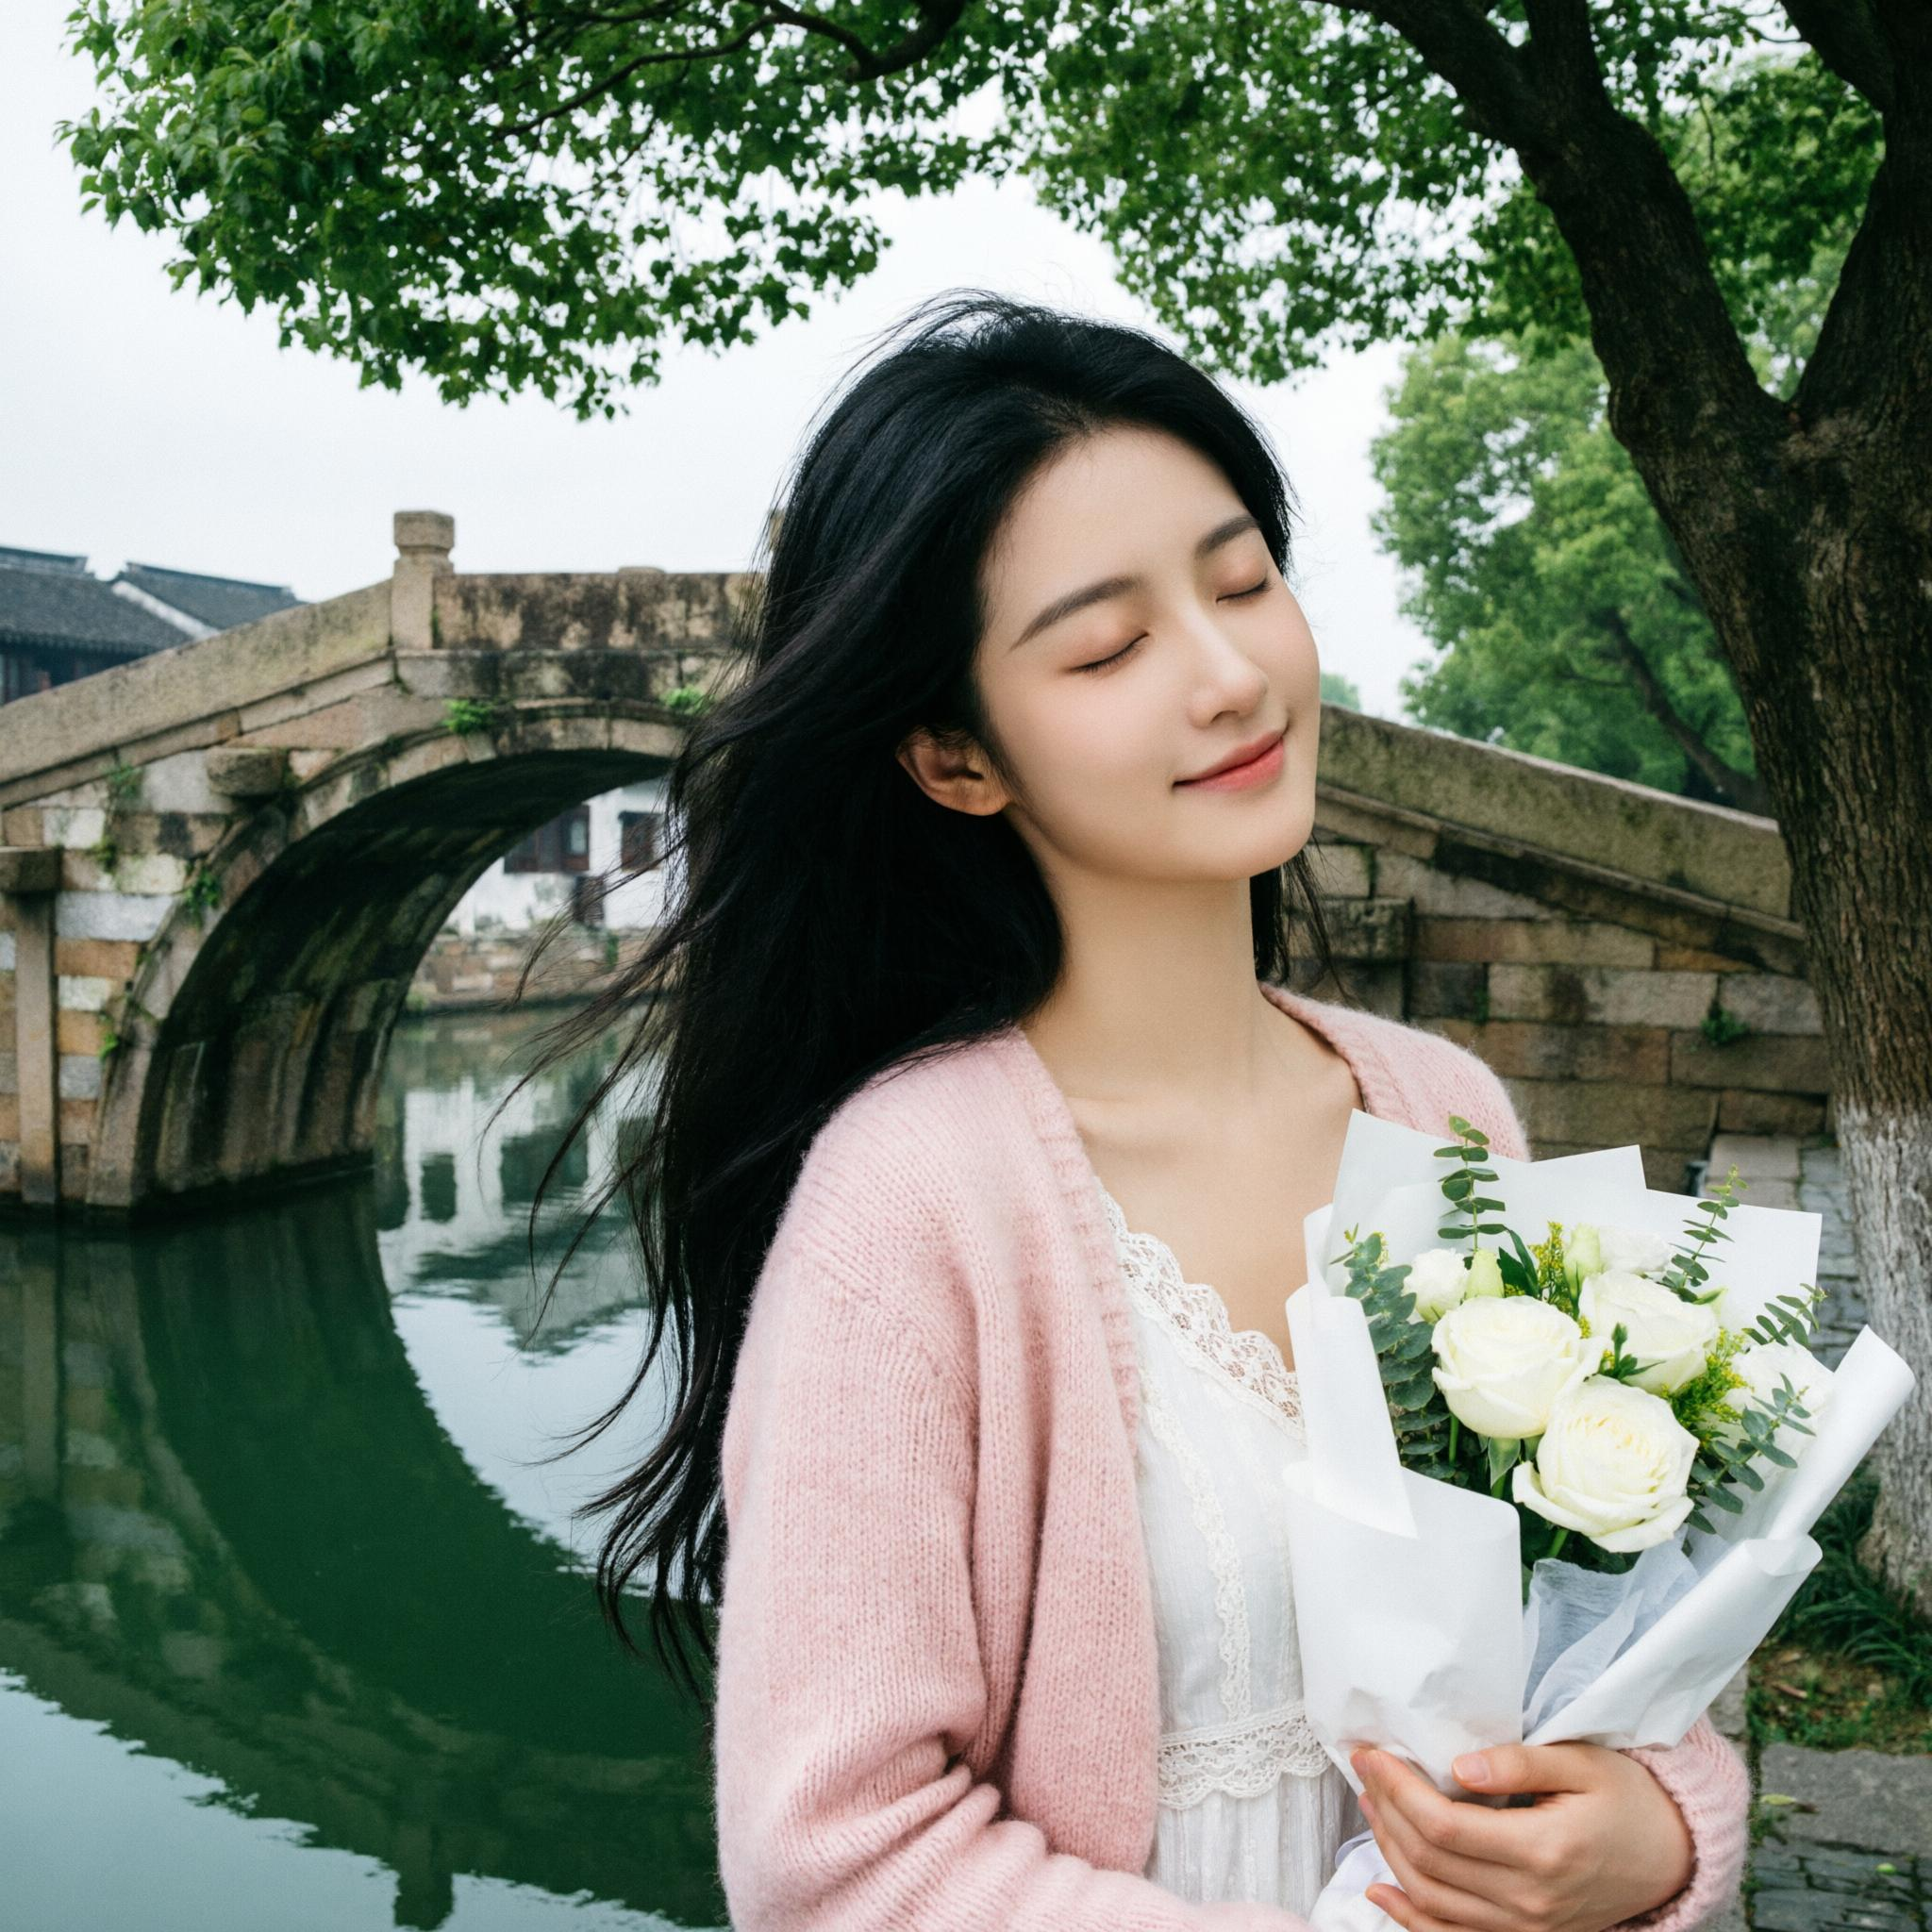
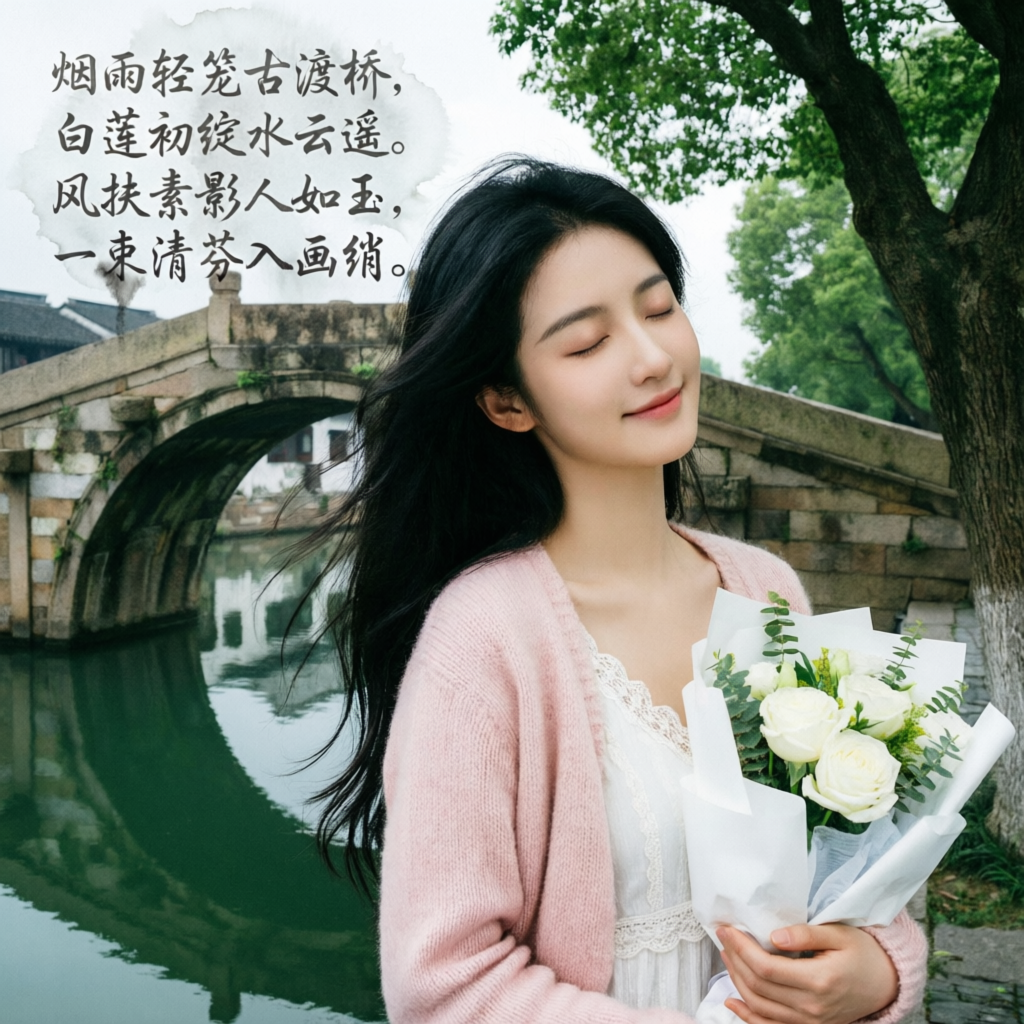
Beyond text-to-image generation, Qwen-Image-2.0 also delivers enhanced image editing capabilities. Excitingly, because this is a unified generation-and-editing (omni) model, improvements in text rendering and photorealism from the generation side directly benefit editing tasks across the board. For instance, thanks to enhanced text rendering, the model can directly inscribe poetry onto an existing image:
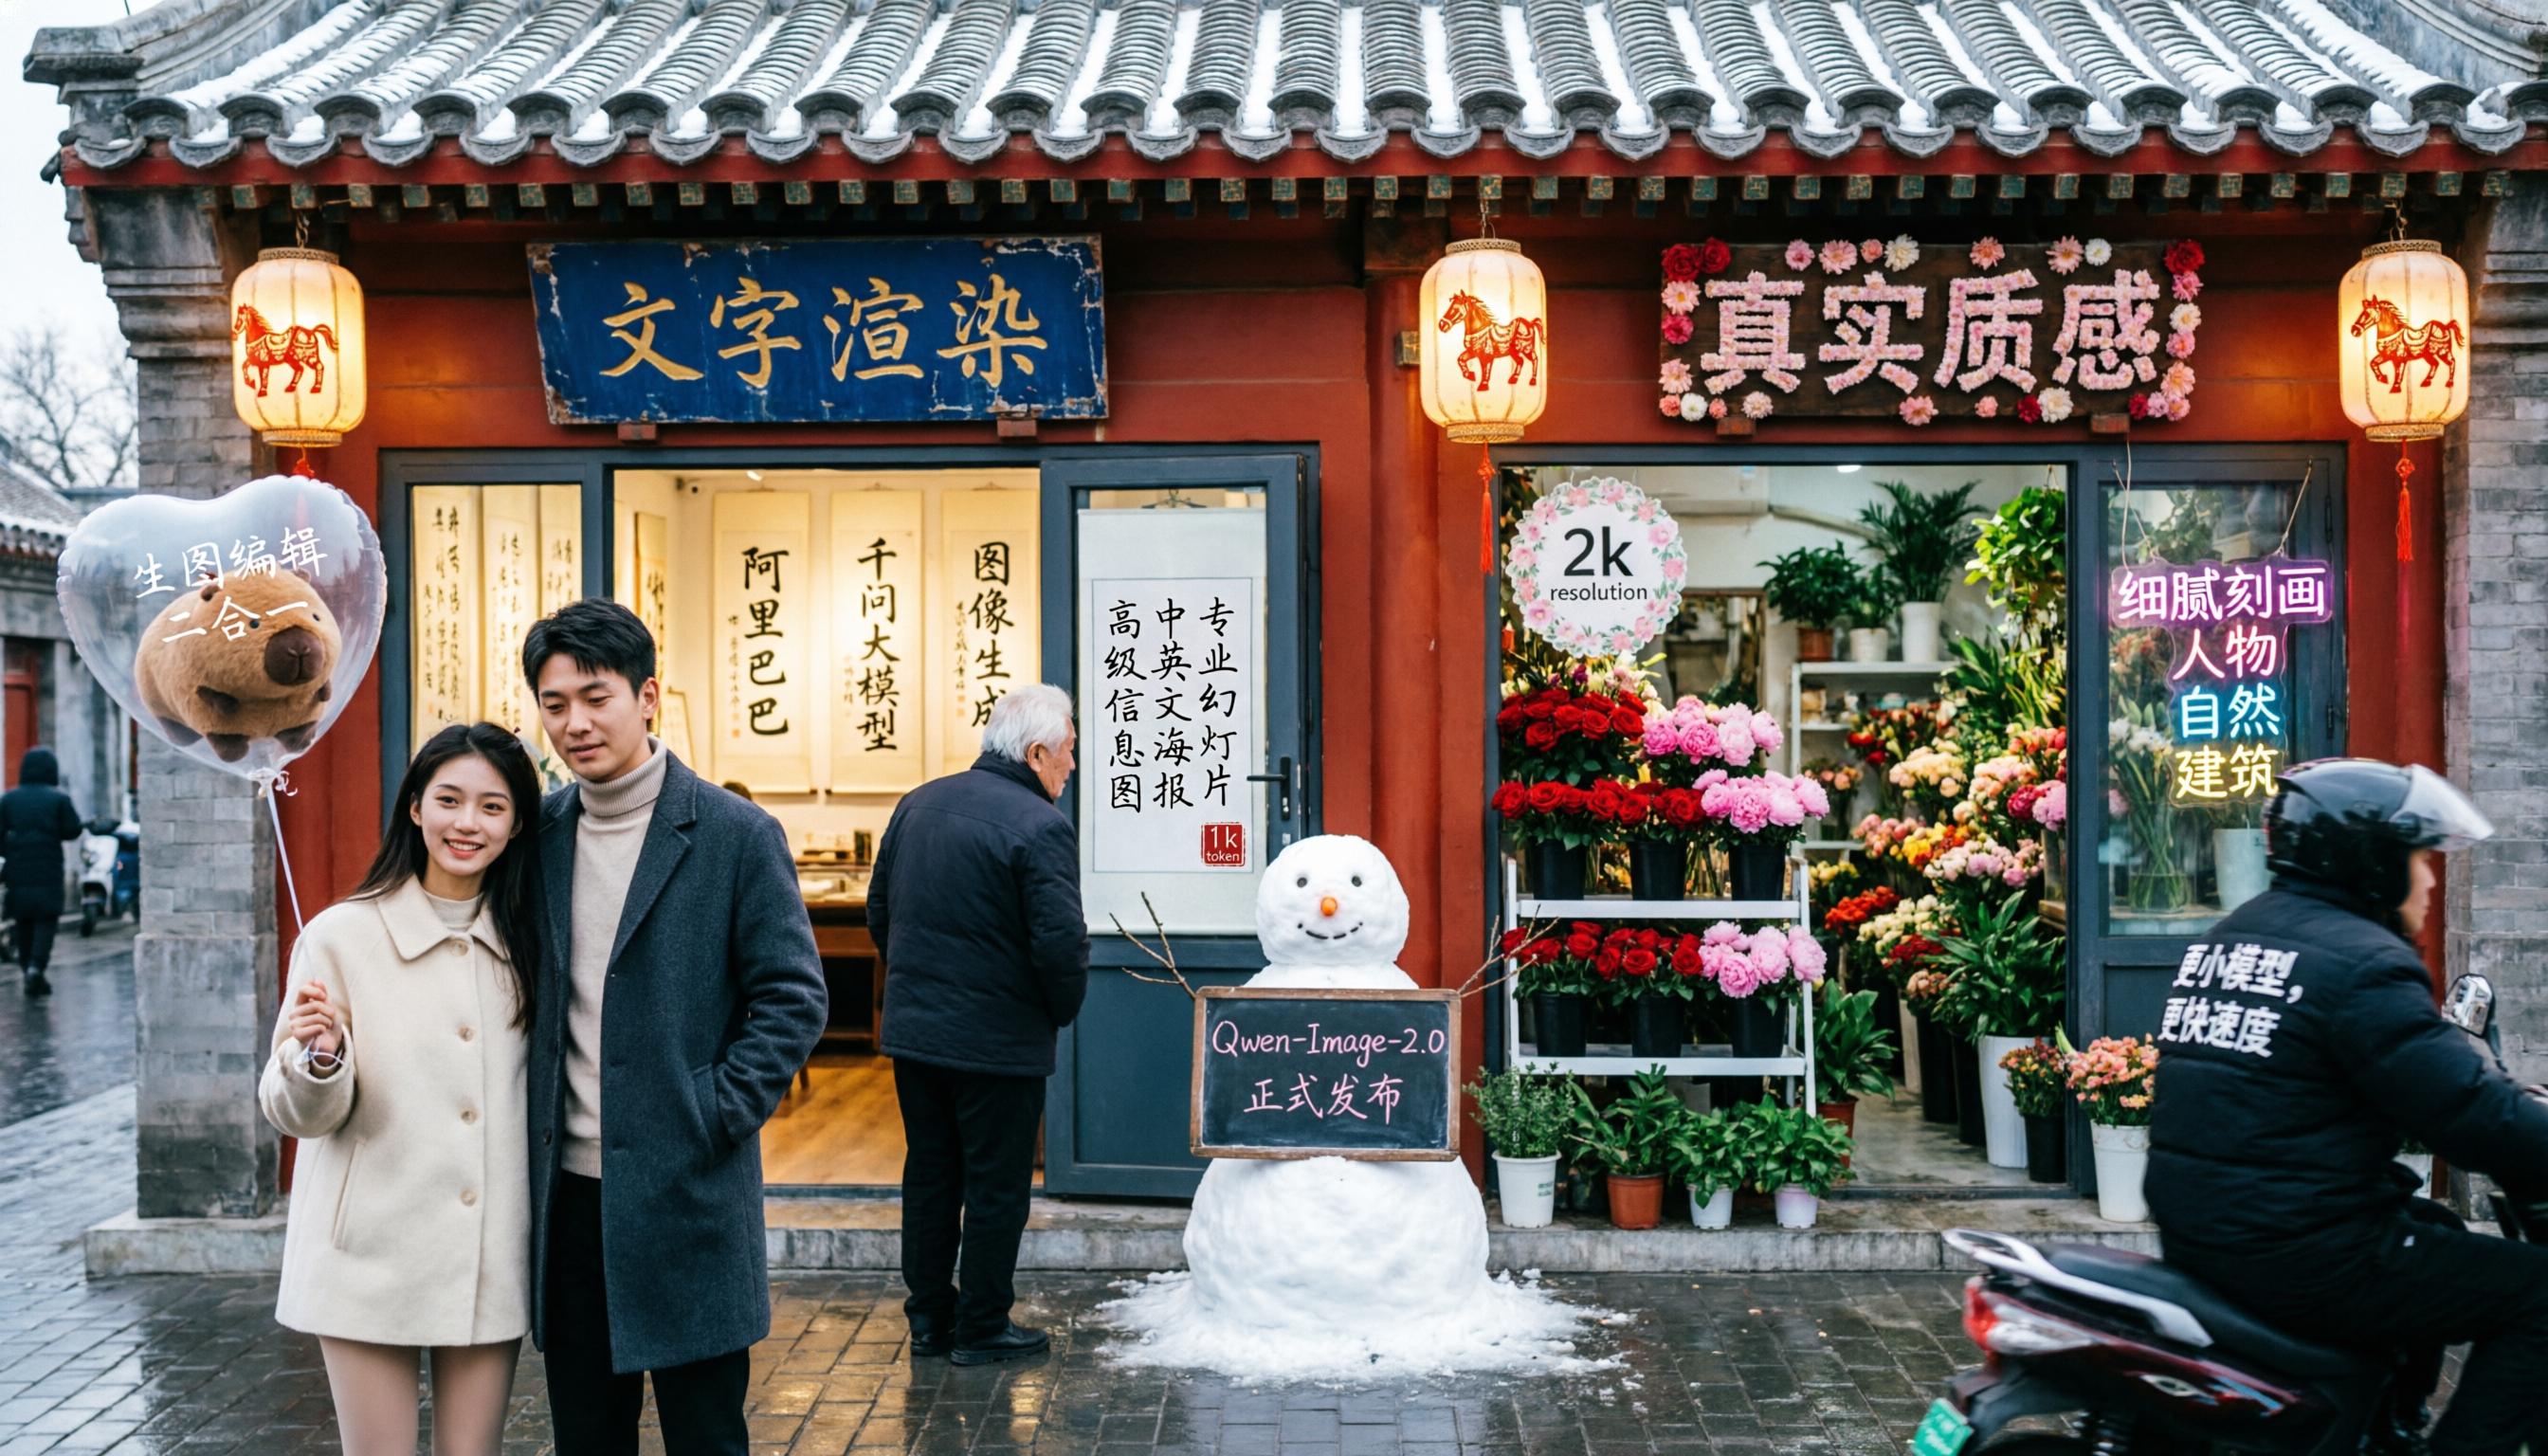
This report is quite lengthy—thank you for reading this far! Finally, we’d like to share the blog’s header image prompt for “Qwen Street” (we’re sure some of you will ask for it):
If Qwen-Image-2.0 proves helpful in your research, we’d greatly appreciate your citation 📝 :)
@misc{wu2025qwenimagetechnicalreport,title={Qwen-Image Technical Report},author={Chenfei Wu and Jiahao Li and Jingren Zhou and Junyang Lin and Kaiyuan Gao and Kun Yan and Sheng-ming Yin and Shuai Bai and Xiao Xu and Yilei Chen and Yuxiang Chen and Zecheng Tang and Zekai Zhang and Zhengyi Wang and An Yang and Bowen Yu and Chen Cheng and Dayiheng Liu and Deqing Li and Hang Zhang and Hao Meng and Hu Wei and Jingyuan Ni and Kai Chen and Kuan Cao and Liang Peng and Lin Qu and Minggang Wu and Peng Wang and Shuting Yu and Tingkun Wen and Wensen Feng and Xiaoxiao Xu and Yi Wang and Yichang Zhang and Yongqiang Zhu and Yujia Wu and Yuxuan Cai and Zenan Liu},year={2025},eprint={2508.02324},archivePrefix={arXiv},primaryClass={cs.CV},url={https://arxiv.org/abs/2508.02324},}