Qwen3.6-27B: Flagship-Level Coding in a 27B Dense Model
文章目录
QWEN STUDIO HUGGING FACE MODELSCOPE DISCORD
Following the launch of Qwen3.6-Plus and Qwen3.6-35B-A3B, we are excited to open-source Qwen3.6-27B — a dense 27-billion-parameter multimodal model at the scale the community has been asking for most. Still supporting both multimodal thinking and non-thinking modes, Qwen3.6-27B delivers flagship-level agentic coding performance, surpassing the previous-generation open-source flagship Qwen3.5-397B-A17B (397B total / 17B active MoE) across all major coding benchmarks. As a dense architecture, it is straightforward to deploy without MoE routing complexity, making it an ideal choice for developers who need top-tier coding capabilities at a practical, widely-deployable scale. Qwen3.6-27B is now live on Qwen Studio, available through our API, and released as open weights for the community.
- Qwen3.6-27B is a fully open-source dense model (27B parameters), featuring:
- flagship-level agentic coding that surpasses Qwen3.5-397B-A17B
- strong text and multimodal reasoning ability
- You can chat interactively on Qwen Studio, call via API on Alibaba Cloud Model Studio API (coming soon), or download weights from Hugging Face and ModelScope.
Performance#
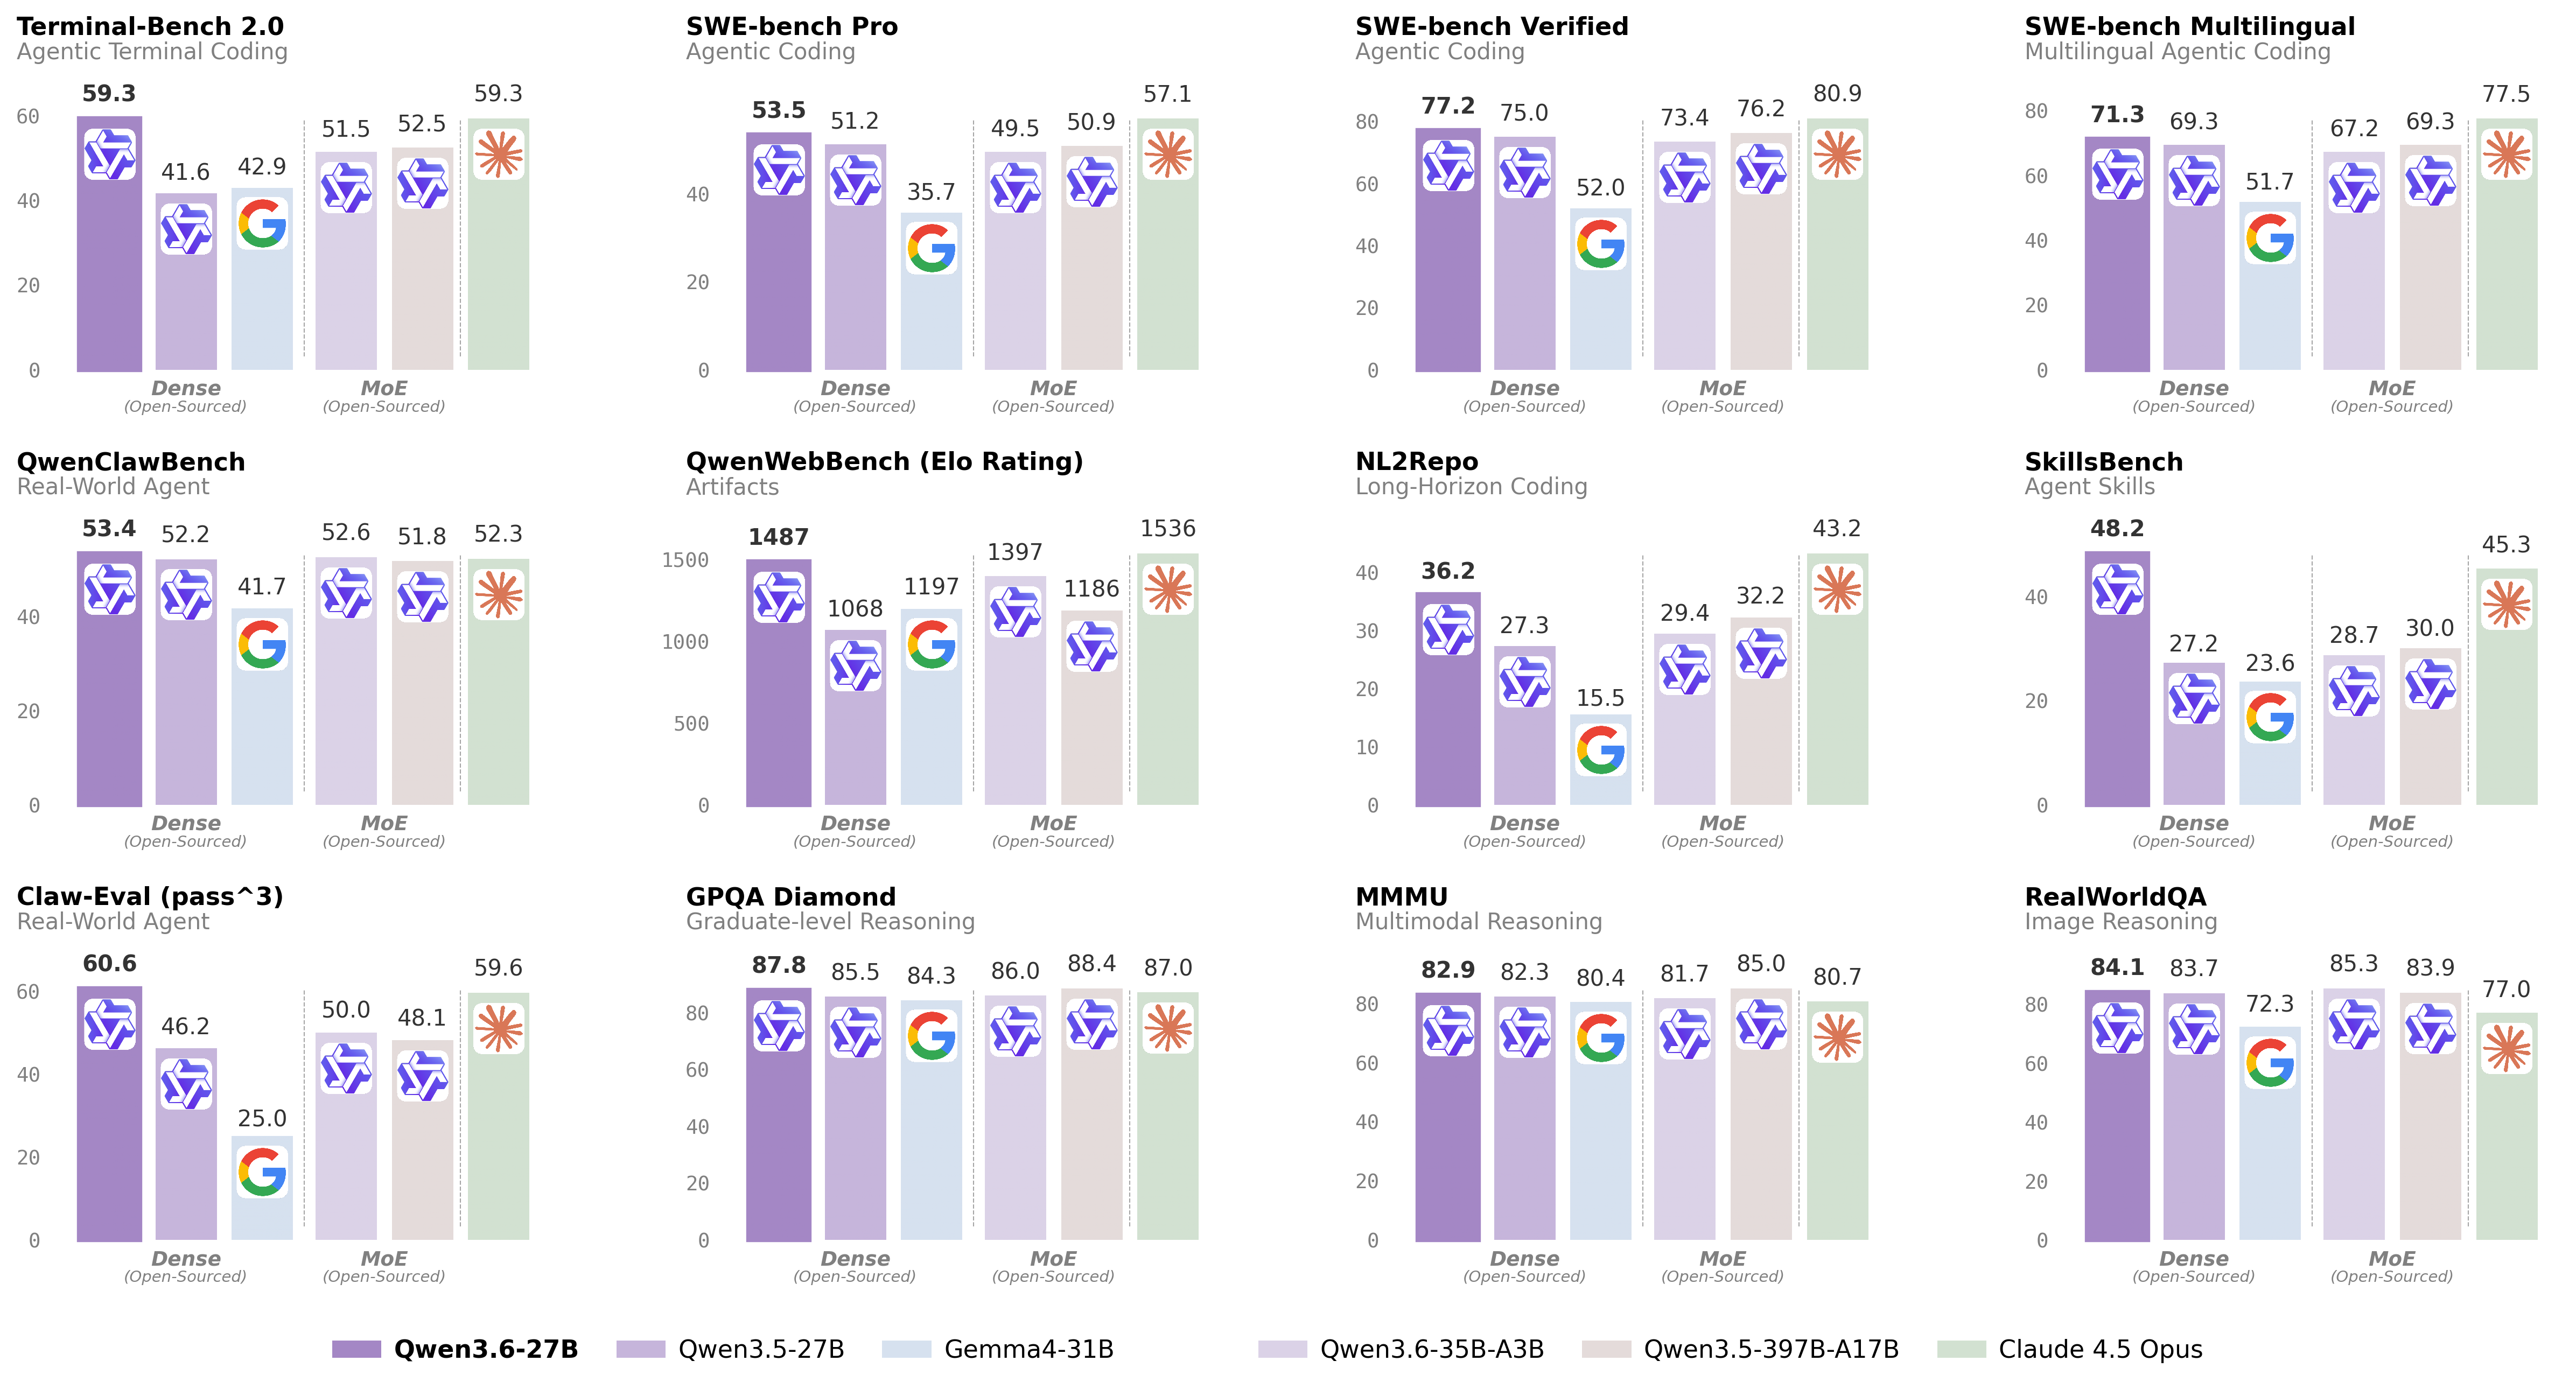
Below we present comprehensive evaluations of Qwen3.6-27B against both dense and MoE baselines, including our previous-generation open-source flagship Qwen3.5-397B-A17B. Qwen3.6-27B delivers remarkable improvements across agentic coding benchmarks, surpassing models with up to 15x its total parameter count.
Language#
Qwen3.6-27B achieves a breakthrough in agentic coding for dense models. With only 27B parameters, it outperforms the Qwen3.5-397B-A17B (397B total / 17B active) on every major coding benchmark — including SWE-bench Verified (77.2 vs. 76.2), SWE-bench Pro (53.5 vs. 50.9), Terminal-Bench 2.0 (59.3 vs. 52.5), and SkillsBench (48.2 vs. 30.0). It also surpasses all peer-scale dense models by a wide margin. On reasoning tasks, Qwen3.6-27B achieves 87.8 on GPQA Diamond, competitive with models several times its size.
| Qwen3.5-27B | Qwen3.5-397B-A17B | Gemma4-31B | Claude 4.5 Opus | Qwen3.6-35B-A3B | Qwen3.6-27B | |
|---|---|---|---|---|---|---|
| Coding Agent | ||||||
| SWE-bench Verified | 75.0 | 76.2 | 52.0 | 80.9 | 73.4 | 77.2 |
| SWE-bench Pro | 51.2 | 50.9 | 35.7 | 57.1 | 49.5 | 53.5 |
| SWE-bench Multilingual | 69.3 | 69.3 | 51.7 | 77.5 | 67.2 | 71.3 |
| Terminal-Bench 2.0 | 41.6 | 52.5 | 42.9 | 59.3 | 51.5 | 59.3 |
| SkillsBench Avg5 | 27.2 | 30.0 | 23.6 | 45.3 | 28.7 | 48.2 |
| QwenWebBench | 1068 | 1186 | 1197 | 1536 | 1397 | 1487 |
| NL2Repo | 27.3 | 32.2 | 15.5 | 43.2 | 29.4 | 36.2 |
| Claw-Eval Avg | 64.3 | 70.7 | 48.5 | 76.6 | 68.7 | 72.4 |
| Claw-Eval Pass^3 | 46.2 | 48.1 | 25.0 | 59.6 | 50.0 | 60.6 |
| QwenClawBench | 52.2 | 51.8 | 41.7 | 52.3 | 52.6 | 53.4 |
| Knowledge | ||||||
| MMLU-Pro | 86.1 | 87.8 | 85.2 | 89.5 | 85.2 | 86.2 |
| MMLU-Redux | 93.2 | 94.9 | 93.7 | 95.6 | 93.3 | 93.5 |
| SuperGPQA | 65.6 | 70.4 | 65.7 | 70.6 | 64.7 | 66.0 |
| C-Eval | 90.5 | 93.0 | 82.6 | 92.2 | 90.0 | 91.4 |
| STEM & Reasoning | ||||||
| GPQA Diamond | 85.5 | 88.4 | 84.3 | 87.0 | 86.0 | 87.8 |
| HLE | 24.3 | 28.7 | 19.5 | 30.8 | 21.4 | 24.0 |
| LiveCodeBench v6 | 80.7 | 83.6 | 80.0 | 84.8 | 80.4 | 83.9 |
| HMMT Feb 25 | 92.0 | 94.8 | 88.7 | 92.9 | 90.7 | 93.8 |
| HMMT Nov 25 | 89.8 | 92.7 | 87.5 | 93.3 | 89.1 | 90.7 |
| HMMT Feb 26 | 84.3 | 87.9 | 77.2 | 85.3 | 83.6 | 84.3 |
| IMOAnswerBench | 79.9 | 80.9 | 74.5 | 84.0 | 78.9 | 80.8 |
| AIME26 | 92.6 | 93.3 | 89.2 | 95.1 | 92.7 | 94.1 |
* SWE-Bench Series: Internal agent scaffold (bash + file-edit tools); temp=1.0, top_p=0.95, 200K context window. We correct some problematic tasks in the public set of SWE-bench Pro and evaluate all baselines on the refined benchmark.
* Terminal-Bench 2.0: Harbor/Terminus-2 harness; 3h timeout, 32 CPU/48 GB RAM; temp=1.0, top_p=0.95, top_k=20, max_tokens=80K, 256K ctx; avg of 5 runs.
* SkillsBench: Evaluated via OpenCode on 78 tasks (self-contained subset, excluding API-dependent tasks); avg of 5 runs.
* NL2Repo: Others are evaluated via Claude Code (temp=1.0, top_p=0.95, max_turns=900).
* QwenClawBench: A real-user-distribution Claw agent benchmark; temp=0.6, 256K ctx.
* QwenWebBench: An internal front-end code generation benchmark; bilingual (EN/CN), 7 categories (Web Design, Web Apps, Games, SVG, Data Visualization, Animation, and 3D); auto-render + multimodal judge (code/visual correctness); BT/Elo rating system.
* AIME 26: We use the full AIME 2026 (I & II), where the scores may differ from Qwen 3.5 notes.
Vision Language#
Qwen3.6-27B is natively multimodal, supporting both vision-language thinking and non-thinking modes in a single unified checkpoint — the same as Qwen3.6-35B-A3B. It handles images and video alongside text, enabling multimodal reasoning, document understanding, and visual question answering.
| Qwen3.5-27B | Qwen3.5-397B-A17B | Gemma4-31B | Claude 4.5 Opus | Qwen3.6-35B-A3B | Qwen3.6-27B | |
|---|---|---|---|---|---|---|
| STEM & Puzzle | ||||||
| MMMU | 82.3 | 85.0 | 80.4 | 80.7 | 81.7 | 82.9 |
| MMMU-Pro | 75.0 | 79.0 | 76.9 | 70.6 | 75.3 | 75.8 |
| MathVista mini | 87.8 | -- | 79.3 | -- | 86.4 | 87.4 |
| DynaMath | 87.7 | 86.3 | 79.5 | 79.7 | 82.8 | 85.6 |
| VlmsAreBlind | 96.9 | -- | 87.2 | -- | 96.6 | 97.0 |
| General VQA | ||||||
| RealWorldQA | 83.7 | 83.9 | 72.3 | 77.0 | 85.3 | 84.1 |
| MMStar | 81.0 | 83.8 | 77.3 | 73.2 | 80.7 | 81.4 |
| MMBenchEN-DEV-v1.1 | 92.6 | -- | 90.9 | -- | 92.8 | 92.3 |
| SimpleVQA | 56.0 | 67.1 | 52.9 | 65.7 | 58.9 | 56.1 |
| Document Understanding | ||||||
| CharXiv RQ | 79.5 | 80.8 | 67.9 | 68.5 | 78.0 | 78.4 |
| CC-OCR | 81.0 | 82.0 | 75.7 | 76.9 | 81.9 | 81.2 |
| OCRBench | 89.4 | -- | 86.1 | -- | 90.0 | 89.4 |
| Spatial Intelligence | ||||||
| ERQA | 60.5 | 67.5 | 57.5 | 46.8 | 61.8 | 62.5 |
| CountBench | 97.8 | 97.2 | 96.1 | 90.6 | 96.1 | 97.8 |
| RefCOCO avg | 90.9 | 92.3 | -- | -- | 92.0 | 92.5 |
| EmbSpatialBench | 84.5 | -- | -- | -- | 84.3 | 84.6 |
| RefSpatialBench | 67.7 | -- | 4.7 | -- | 64.3 | 70.0 |
| Video Understanding | ||||||
| VideoMME(w sub.) | 87.0 | 87.5 | -- | 77.7 | 86.6 | 87.7 |
| VideoMMMU | 82.3 | 84.7 | 81.6 | 84.4 | 83.7 | 84.4 |
| MLVU | 85.9 | 86.7 | -- | 81.7 | 86.2 | 86.6 |
| MVBench | 74.6 | 77.6 | -- | 67.2 | 74.6 | 75.5 |
| Visual Agent | ||||||
| V* | 93.7 | 95.8 | -- | 67.0 | 90.1 | 94.7 |
| AndroidWorld | 64.2 | -- | -- | -- | -- | 70.3 |
* Empty cells (--) indicate scores not yet available or not applicable.
Build with Qwen3.6-27B#
- Qwen3.6-27B is coming soon to Alibaba Cloud Model Studio. Please stand by until we are fully ready.
Qwen3.6-27B is available as open weights on Hugging Face and ModelScope for self-hosting, and through the Alibaba Cloud Model Studio API. You can also try it instantly on Qwen Studio.
The model can be seamlessly integrated with popular third-party coding assistants, including OpenClaw, Claude Code, and Qwen Code, to streamline development workflows and enable efficient, context-aware coding experiences.
API Usage#
This release supports the preserve_thinking feature: preserving thinking content from all preceding turns in messages, which is recommended for agentic tasks.
Alibaba Cloud Model Studio
Alibaba Cloud Model Studio supports industry-standard protocols, including chat completions and responses APIs compatible with OpenAI’s specification, as well as an API interface compatible with Anthropic.
Example code for chat completions API is provided below:
"""
Environment variables (per official docs):
  DASHSCOPE_API_KEY: Your API Key from https://modelstudio.console.alibabacloud.com
  DASHSCOPE_BASE_URL: (optional) Base URL for compatible-mode API.
    - Beijing: https://dashscope.aliyuncs.com/compatible-mode/v1
    - Singapore: https://dashscope-intl.aliyuncs.com/compatible-mode/v1
    - US (Virginia): https://dashscope-us.aliyuncs.com/compatible-mode/v1
  DASHSCOPE_MODEL: (optional) Model name; override for different models.
"""
from openai import OpenAI
import os

api_key = os.environ.get("DASHSCOPE_API_KEY")
if not api_key:
    raise ValueError(
        "DASHSCOPE_API_KEY is required. "
        "Set it via: export DASHSCOPE_API_KEY='your-api-key'"
    )

client = OpenAI(
    api_key=api_key,
    base_url=os.environ.get(
        "DASHSCOPE_BASE_URL",
        "https://dashscope-intl.aliyuncs.com/compatible-mode/v1",
    ),
)

messages = [{"role": "user", "content": "Introduce vibe coding."}]

model = os.environ.get(
    "DASHSCOPE_MODEL",
    "qwen3.6-27b",
)
completion = client.chat.completions.create(
    model=model,
    messages=messages,
    extra_body={
        "enable_thinking": True,
        # "preserve_thinking": True,
    },
    stream=True
)

reasoning_content = ""  # Full reasoning trace
answer_content = ""  # Full response
is_answering = False  # Whether we have entered the answer phase
print("\n" + "=" * 20 + "Reasoning" + "=" * 20 + "\n")

for chunk in completion:
    if not chunk.choices:
        print("\nUsage:")
        print(chunk.usage)
        continue

    delta = chunk.choices[0].delta

    # Collect reasoning content only
    if hasattr(delta, "reasoning_content") and delta.reasoning_content is not None:
        if not is_answering:
            print(delta.reasoning_content, end="", flush=True)
        reasoning_content += delta.reasoning_content

    # Received content, start answer phase
    if hasattr(delta, "content") and delta.content:
        if not is_answering:
            print("\n" + "=" * 20 + "Answer" + "=" * 20 + "\n")
            is_answering = True
        print(delta.content, end="", flush=True)
        answer_content += delta.content
For more information, please visit the API doc.
Coding & Agents#
Qwen3.6-27B features excellent agentic coding capabilities and can be seamlessly integrated into popular third-party coding assistants, including OpenClaw, Claude Code, and Qwen Code.
OpenClaw
Qwen3.6-27B is compatible with OpenClaw (formerly Moltbot / Clawdbot), a self-hosted open-source AI coding agent. Connect it to Model Studio to get a full agentic coding experience in the terminal. Get started with the following script:
# Node.js 22+
curl -fsSL https://molt.bot/install.sh | bash   # macOS / Linux

# Set your API key
export DASHSCOPE_API_KEY=<your_api_key>

# Launch OpenClaw
openclaw dashboard # web browser
# openclaw tui # Open a new terminal and start the TUI
On first use, edit ~/.openclaw/openclaw.json to point OpenClaw at Model Studio.
Find or create the following fields and merge them — do not overwrite the entire file
to preserve your existing settings:
{
  "models": {
    "mode": "merge",
    "providers": {
      "modelstudio": {
        "baseUrl": "https://dashscope-intl.aliyuncs.com/compatible-mode/v1",
        "apiKey": "DASHSCOPE_API_KEY",
        "api": "openai-completions",
        "models": [
          {
            "id": "qwen3.6-27b",
            "name": "qwen3.6-27b",
            "reasoning": true,
            "input": ["text", "image"],
            "contextWindow": 131072,
            "maxTokens": 16384
          }
        ]
      }
    }
  },
  "agents": {
    "defaults": {
      "model": {
        "primary": "modelstudio/qwen3.6-27b"
      },
      "models": {
        "modelstudio/qwen3.6-27b": {}
      }
    }
  }
}
Qwen Code
Qwen3.6-27B is compatible with Qwen Code, an open-source AI agent designed for the terminal and deeply optimized for the Qwen Series. Get started with the following script:
# Node.js 20+
npm install -g @qwen-code/qwen-code@latest

# Start Qwen Code (interactive)
qwen

# Then, in the session:
/help
/auth
On first use, you’ll be prompted to sign in. You can run /auth anytime to switch authentication methods.
Claude Code
Qwen APIs also support the Anthropic API protocol, meaning you can use it with tools like Claude Code for elevated coding experience:
# Install Claude Code
npm install -g @anthropic-ai/claude-code

# Configure environment
export ANTHROPIC_MODEL="qwen3.6-27b"
export ANTHROPIC_SMALL_FAST_MODEL="qwen3.6-27b"
export ANTHROPIC_BASE_URL=https://dashscope-intl.aliyuncs.com/apps/anthropic
export ANTHROPIC_AUTH_TOKEN=<your_api_key>

# Launch the CLI
claude
Summary#
Qwen3.6-27B demonstrates that a well-trained dense model can surpass much larger predecessors on the tasks that matter most for developers. At 27 billion parameters — the most widely deployed open-source scale — it outperforms the 397B-parameter Qwen3.5-397B-A17B on every major agentic coding benchmark, while remaining straightforward to deploy and serve. With Qwen3.6-27B joining the roster, the Qwen3.6 open-source family now offers a comprehensive range of models, underscoring a generation where agentic coding achieved breakthroughs across every scale — from the 3B-active Qwen3.6-35B-A3B to the API-accessible Qwen3.6-Plus and Qwen3.6-Max-Preview. We are grateful for the community’s feedback and look forward to seeing what you build with these models. Stay tuned for more from the Qwen team!
Citation#
Feel free to cite the following article if you find Qwen3.6-27B helpful:
@misc{qwen36_27b,
    title = {{Qwen3.6-27B}: Flagship-Level Coding in a 27B Dense Model},
    url = {https://qwen.ai/blog?id=qwen3.6-27b},
    author = {{Qwen Team}},
    month = {April},
    year = {2026}
}
原文来自 千问 Qwen Team,版权归原作者。
正文采集于 ,内容更新以原文为准。