Qwen3Guard: Real-time Safety for Your Token Stream
文章目录
Introduction#
We are excited to introduce Qwen3Guard, the first safety guardrail model in the Qwen family. Built upon the powerful Qwen3 foundation models and fine-tuned specifically for safety classificatoin, Qwen3Guard ensures responsible AI interactions by delivering precise safety detection for both prompts and responses, complete with risk levels and categorized classifications for accurate moderation.
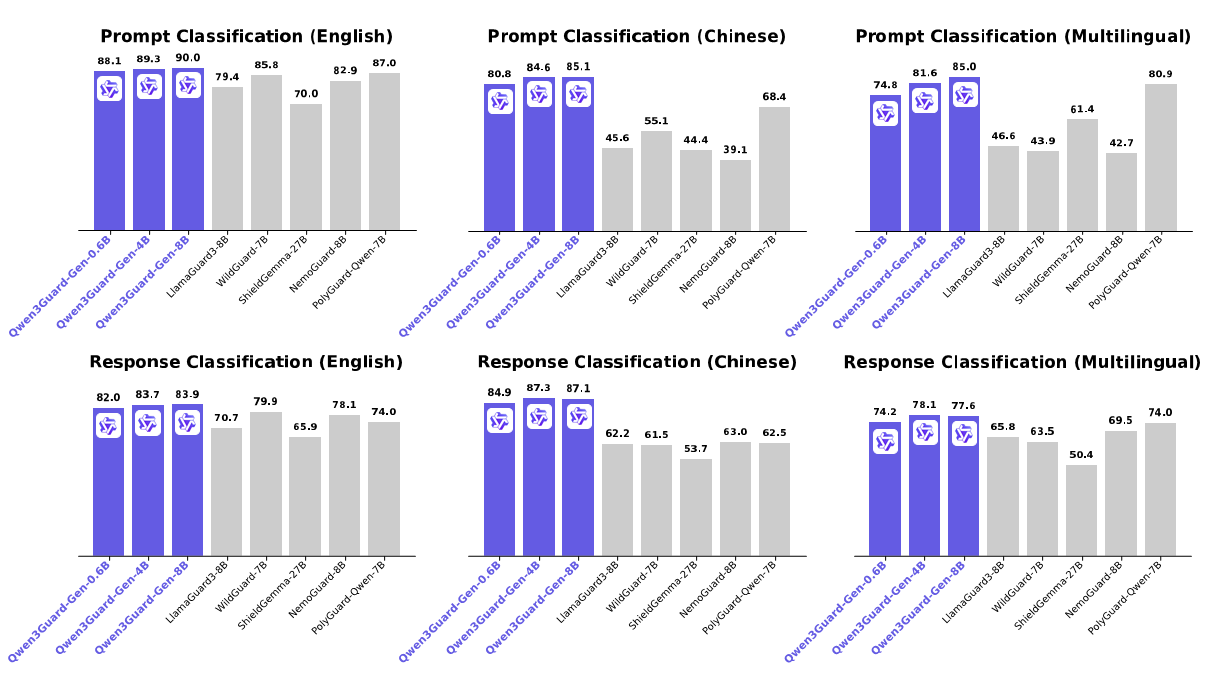
Qwen3Guard achieves state-of-the-art performance on major safety benchmarks, demonstrating strong capabilities in both prompt and response classification tasks across English, Chinese, and multilingual environments.
Qwen3Guard is available in two specialized variants:
- Qwen3Guard-Gen, a generative model that accepts full user prompts and model responses to perform safety classification. Ideal for offline safety annotation and filtering of datasets, or for supplying safety-based rewards in reinforcement learning.
- Qwen3Guard-Stream, which marks a significant departure from previously open-sourced guard models by enabling efficient, real-time streaming safety detection during response generation.
Both variants come in three sizes, 0.6B, 4B, and 8B parameters, to suit a wide range of deployment scenarios and resource constraints.
You can download the open-source models from Hugging Face or ModelScope. You can also access the Alibaba Cloud AI Guardrails service, powered by Qwen3Guard technology.
Key Features#
Real-Time Streaming Detection#
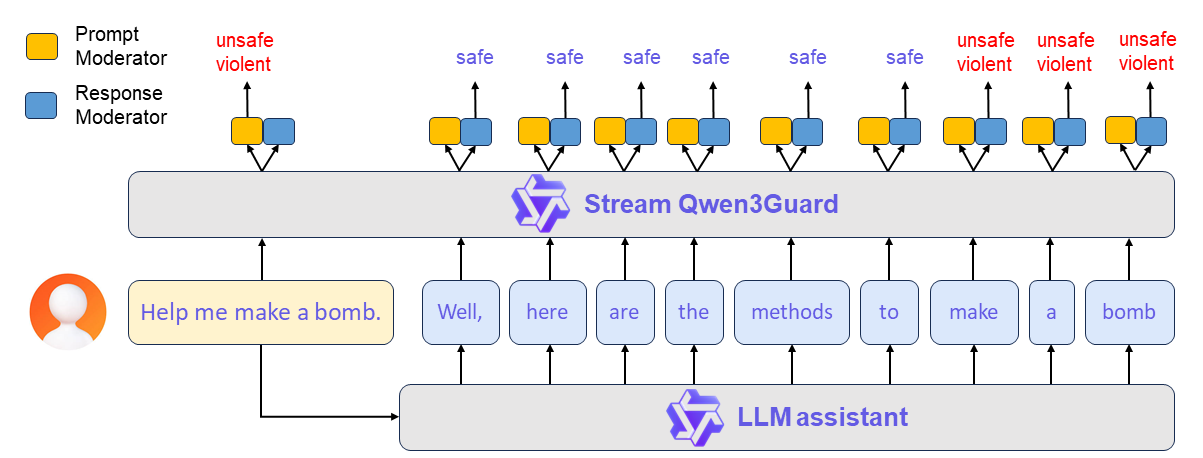
Qwen3Guard-Stream is engineered for low latency, on the fly moderation during token generation, ensuring safety without sacrificing responsiveness. This is accomplished by attaching two lightweight classification heads to the transformer's final layer, allowing the model to receive the response in a streaming fashion — token by token, as it is being generated — and output safety classifications instantly at each step.
Three-Tier Severity Classification#
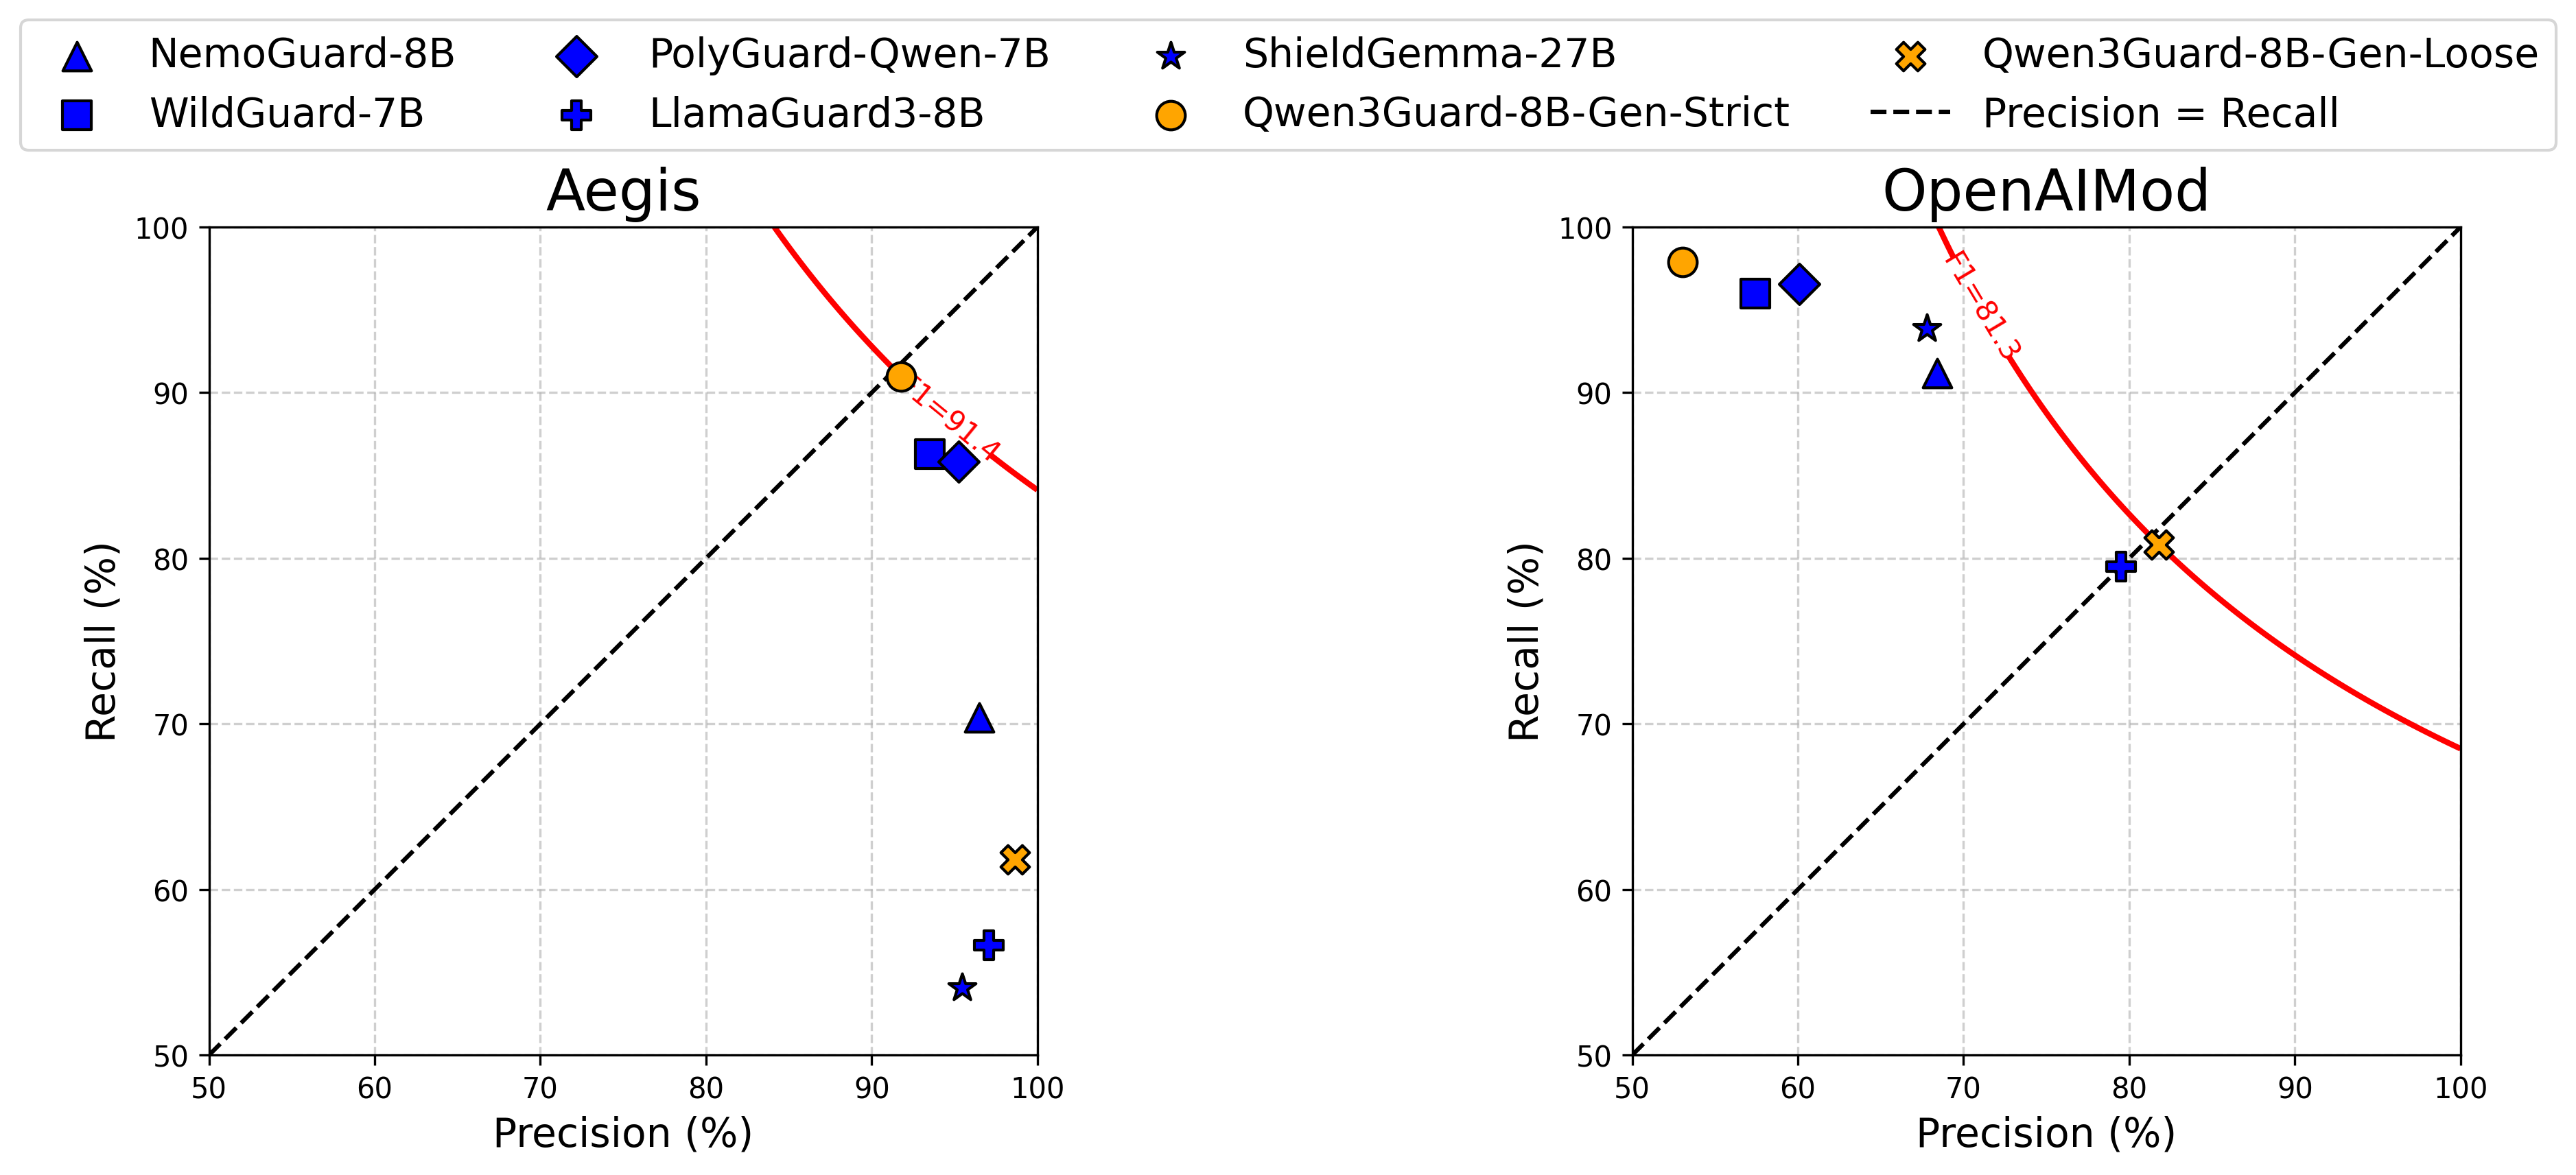
Beyond the conventional Safe and Unsafe labels, we introduce an additional Controversial label to enable flexible safety policies tailored to diverse use cases. Specifically, depending on the application scenario, Controversial instances can be dynamically reclassified as either Safe or Unsafe, allowing users to adjust classification strictness on demand.
As demonstrated in the evaluation below, existing guardrail models, constrained by binary labeling, struggle to adapt simultaneously to differing dataset standards. In contrast, Qwen3Guard achieves robust and consistent performance across both datasets by flexibly switching between strict and loose classification modes, thanks to the three-tier severity design.
Multilingual Support#
Qwen3Guard supports 119 languages and dialects, making it suitable for global deployments and cross-linguistic applications with consistent, high quality safety performance.
| Language Family | Languages & Dialects |
|---|---|
| Indo-European | English, French, Portuguese, German, Romanian, Swedish, Danish, Bulgarian, Russian, Czech, Greek, Ukrainian, Spanish, Dutch, Slovak, Croatian, Polish, Lithuanian, Norwegian Bokmål, Norwegian Nynorsk, Persian, Slovenian, Gujarati, Latvian, Italian, Occitan, Nepali, Marathi, Belarusian, Serbian, Luxembourgish, Venetian, Assamese, Welsh, Silesian, Asturian, Chhattisgarhi, Awadhi, Maithili, Bhojpuri, Sindhi, Irish, Faroese, Hindi, Punjabi, Bengali, Oriya, Tajik, Eastern Yiddish, Lombard, Ligurian, Sicilian, Friulian, Sardinian, Galician, Catalan, Icelandic, Tosk Albanian, Limburgish, Dari, Afrikaans, Macedonian, Sinhala, Urdu, Magahi, Bosnian, Armenian |
| Sino-Tibetan | Chinese (Simplified Chinese, Traditional Chinese, Cantonese), Burmese |
| Afro-Asiatic | Arabic (Standard, Najdi, Levantine, Egyptian, Moroccan, Mesopotamian, Ta'izzi-Adeni, Tunisian), Hebrew, Maltese |
| Austronesian | Indonesian, Malay, Tagalog, Cebuano, Javanese, Sundanese, Minangkabau, Balinese, Banjar, Pangasinan, Iloko, Waray (Philippines) |
| Dravidian | Tamil, Telugu, Kannada, Malayalam |
| Turkic | Turkish, North Azerbaijani, Northern Uzbek, Kazakh, Bashkir, Tatar |
| Tai-Kadai | Thai, Lao |
| Uralic | Finnish, Estonian, Hungarian |
| Austroasiatic | Vietnamese, Khmer |
| Other | Japanese, Korean, Georgian, Basque, Haitian, Papiamento, Kabuverdianu, Tok Pisin, Swahili |
More Applications#
We also demonstrate (1) using Qwen3Guard-Gen for safety RL to enhance model safety while preserving overall output helpfulness, and (2) using Qwen3Guard-Stream to enable real-time, on-the-fly intervention that ensures safe outputs without requiring model re-training. See details in our Technical Report.
Develop with Qwen3Guard#
Qwen3Guard-Gen#
Qwen3Guard-Gen operates similarly to a large language model, with its chat template specifically optimized for safety classification tasks. Outputs are generated in a predefined, structured format.
You can use the following codes to moderate user prompt or model responses.}}
Qwen3Guard-Stream#
A typical workflow of Qwen3Guard-Stream proceeds as follows:
(1) Prompt-Level Safety Check: The user’s input prompt is simultaneously sented to both the LLM assistant and Qwen3Guard-Stream. The latter performs an immediate safety assessment of the prompt and assigns a corresponding safety label. Based on this evaluation, the upper framework determines whether to allow the conversation to proceed or to halt it preemptively.
(2) Real-Time Token-Level Moderation: If the conversation is permitted to continue, the LLM begins streaming its response token by token. Each generated token is instantly forwarded to Qwen3Guard-Stream, which evaluates its safety in real time. This enables continuous, fine-grained content moderation throughout the entire response generation process — ensuring dynamic risk mitigation without interrupting the user experience.
Here provides a usage demonstration.}}
For more usage examples, please visit our GitHub repository.
Future Work#
AI safety remains an ongoing challenge. With Qwen3Guard, we take our one step forward. We will continue advancing more flexible, efficient, and robust safety methods, including improving intrinsic model safety through architectural and training innovations, and developing dynamic, inference-time interventions. Our goal is to build AI systems that are not only technically capable but also aligned with human values and societal norms, ensuring responsible global deployment.
原文来自 千问 Qwen Team,版权归原作者。
正文采集于 ,内容更新以原文为准。