Qwen2.5-VL-32B: Smarter and Lighter
待判断 · 查看依据
标题摘要信号不足,保留待判断;未命中不代表不相关。
仅依据标题和摘要,未审核全文。标签不改变收录、搜索或订阅;待判断不代表不相关。 如需更正,请在 GitHub Issue 提供原文与说明。规则版本:content-signals-trial-1。
文章目录
Introduction#
At the end of January this year, we launched the Qwen2.5-VL series of models, which received widespread attention and positive feedback from the community. Building on the Qwen2.5-VL series, we continued to optimize the model using reinforcement learning and open-sourced the new VL model with the beloved 32B parameter scale under the Apache 2.0 license — Qwen2.5-VL-32B-Instruct. Compared to the previously released Qwen2.5-VL series models, the features of this 32B VL model are as follows:
- Responses More Aligned with Human Preferences: Adjusted the output style to provide more detailed, better-formatted answers that align more closely with human preferences.
- Mathematical Reasoning: Significant improvement in the accuracy of solving complex mathematical problems.
- Fine-grained Image Understanding and Reasoning: Enhanced accuracy and detailed analysis in tasks such as image parsing, content recognition, and visual logic deduction.
Performance#
Extensive benchmarking against state-of-the-art (SoTA) models of comparable scale, Qwen2.5-VL-32B-Instruct has demonstrated superiority over baselines, e.g., Mistral-Small-3.1-24B and Gemma-3-27B-IT, even surpassing the larger Qwen2-VL-72B-Instruct. Notably, it achieves significant advantages in multimodal tasks such as MMMU, MMMU-Pro, and MathVista, which focus on complex, multi-step reasoning. On MM-MT-Bench, a benchmark emphasizing subjective user experience evaluation, Qwen2.5-VL-32B-Instruct outperforms its predecessor Qwen2-VL-72B-Instruct by a substantial margin.
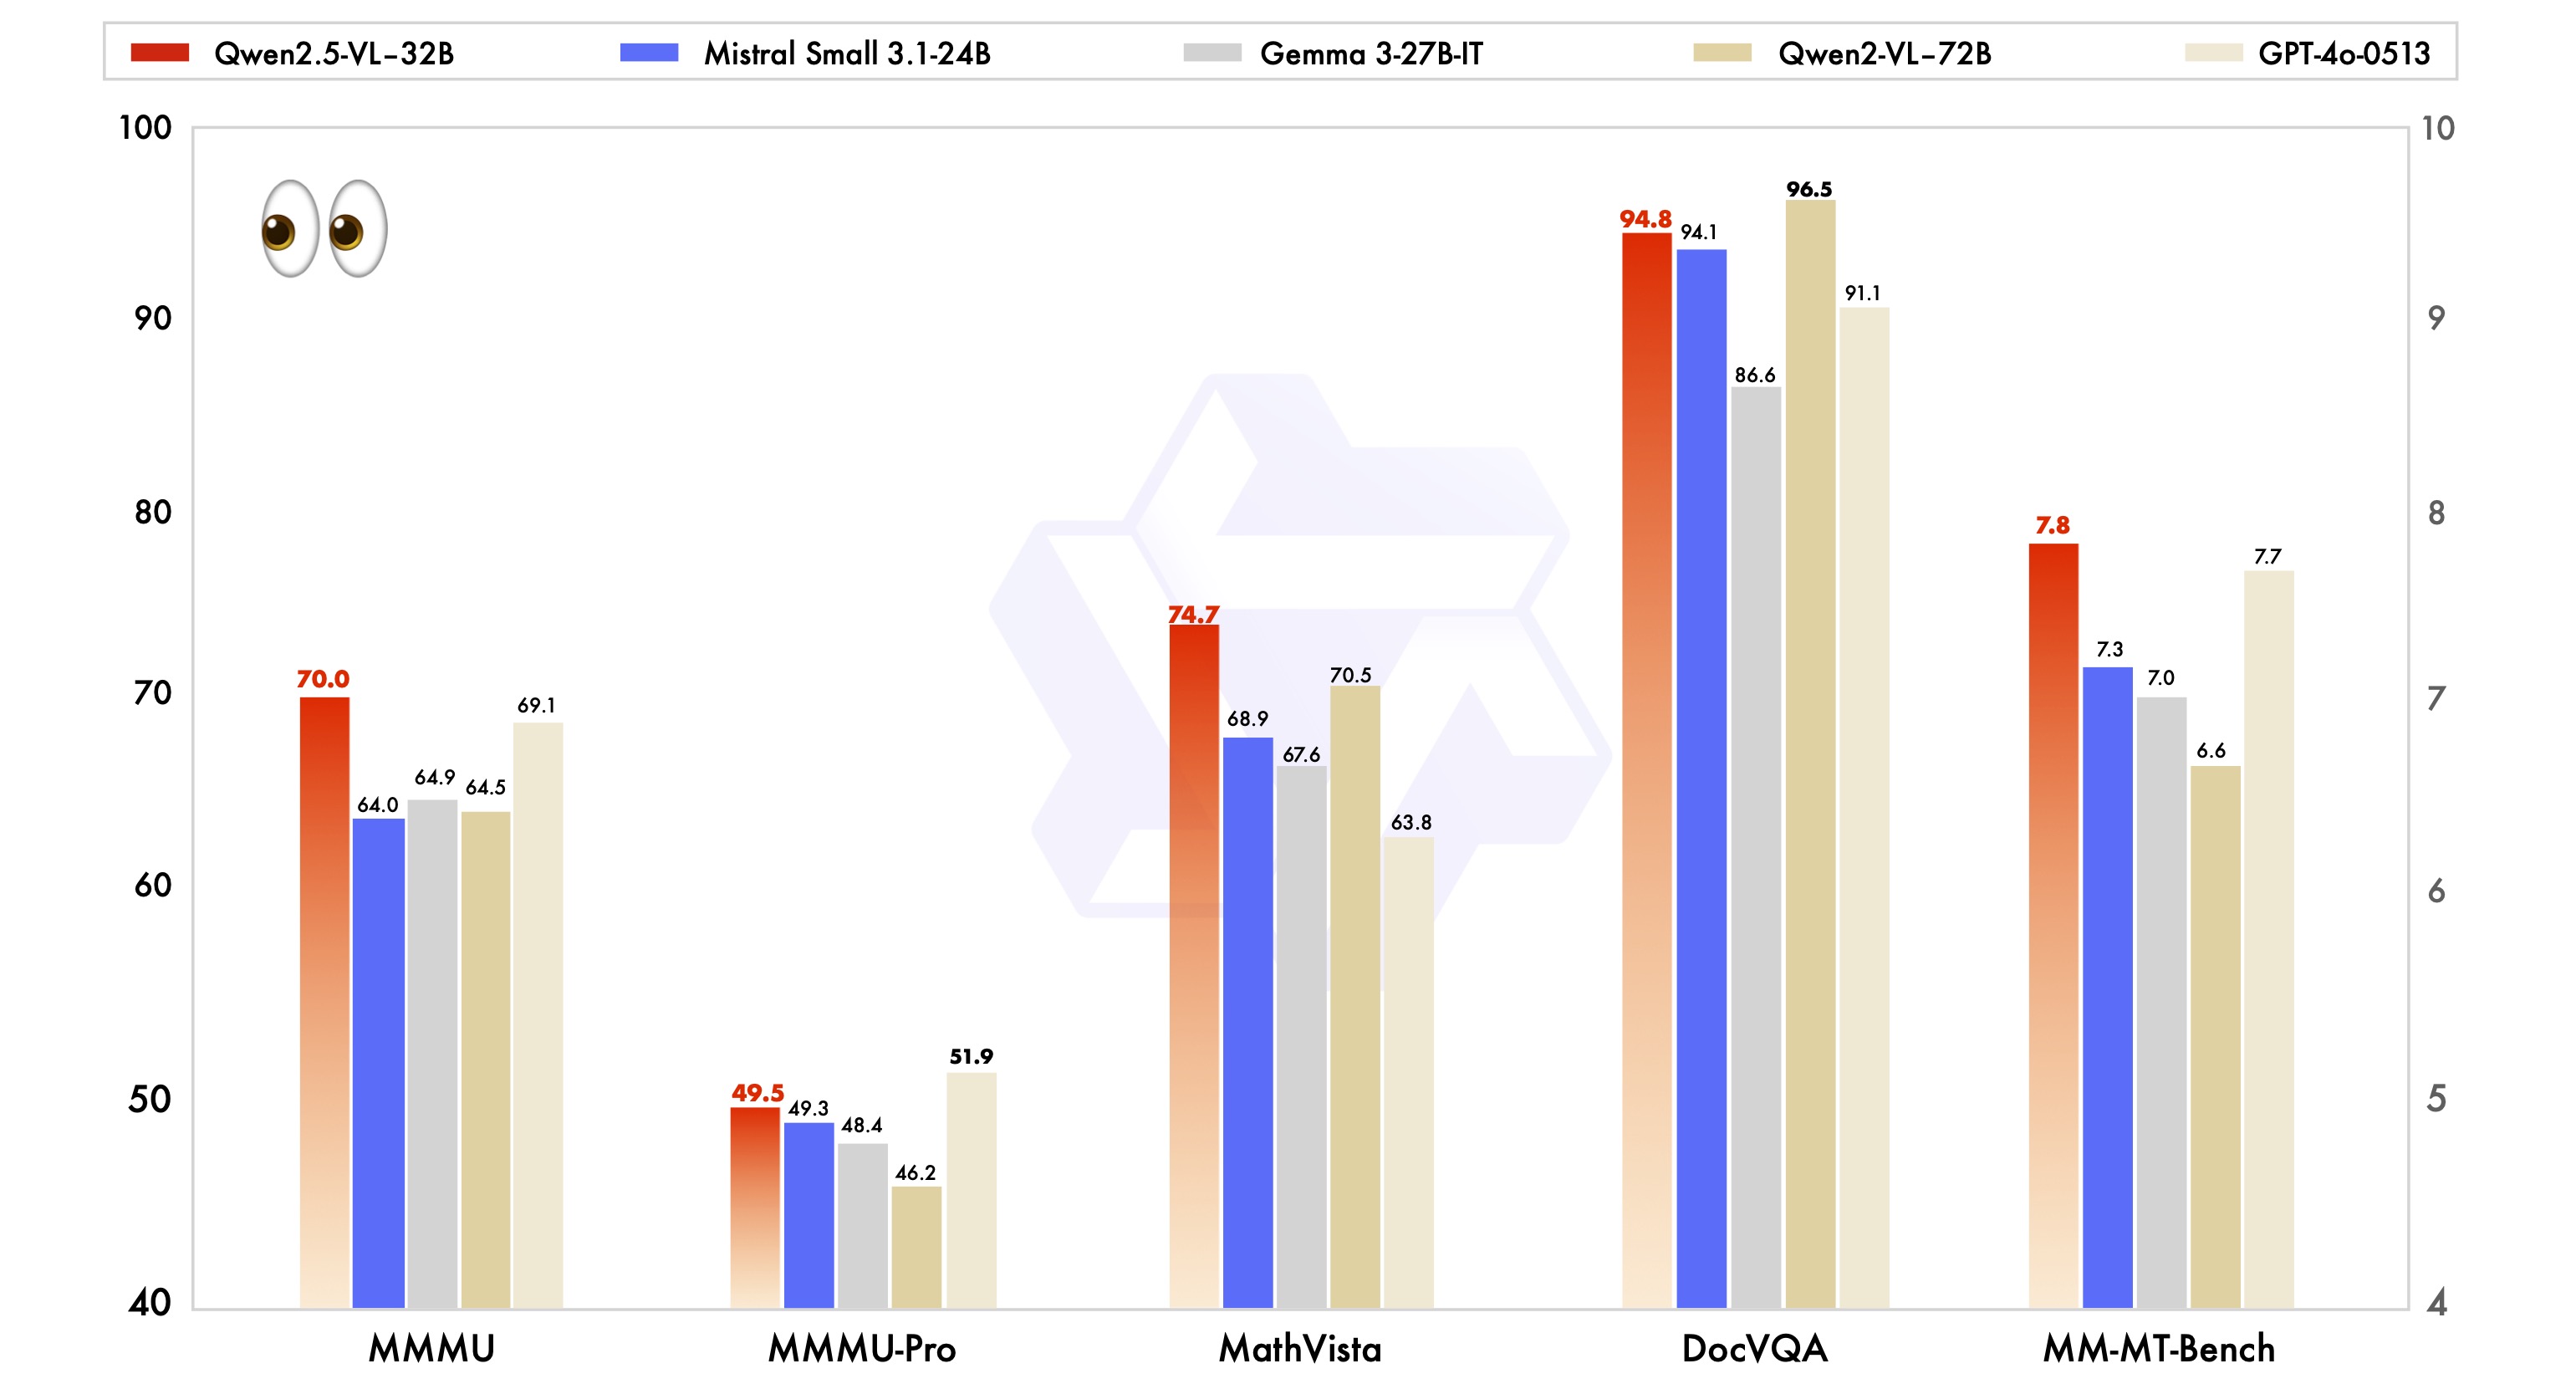
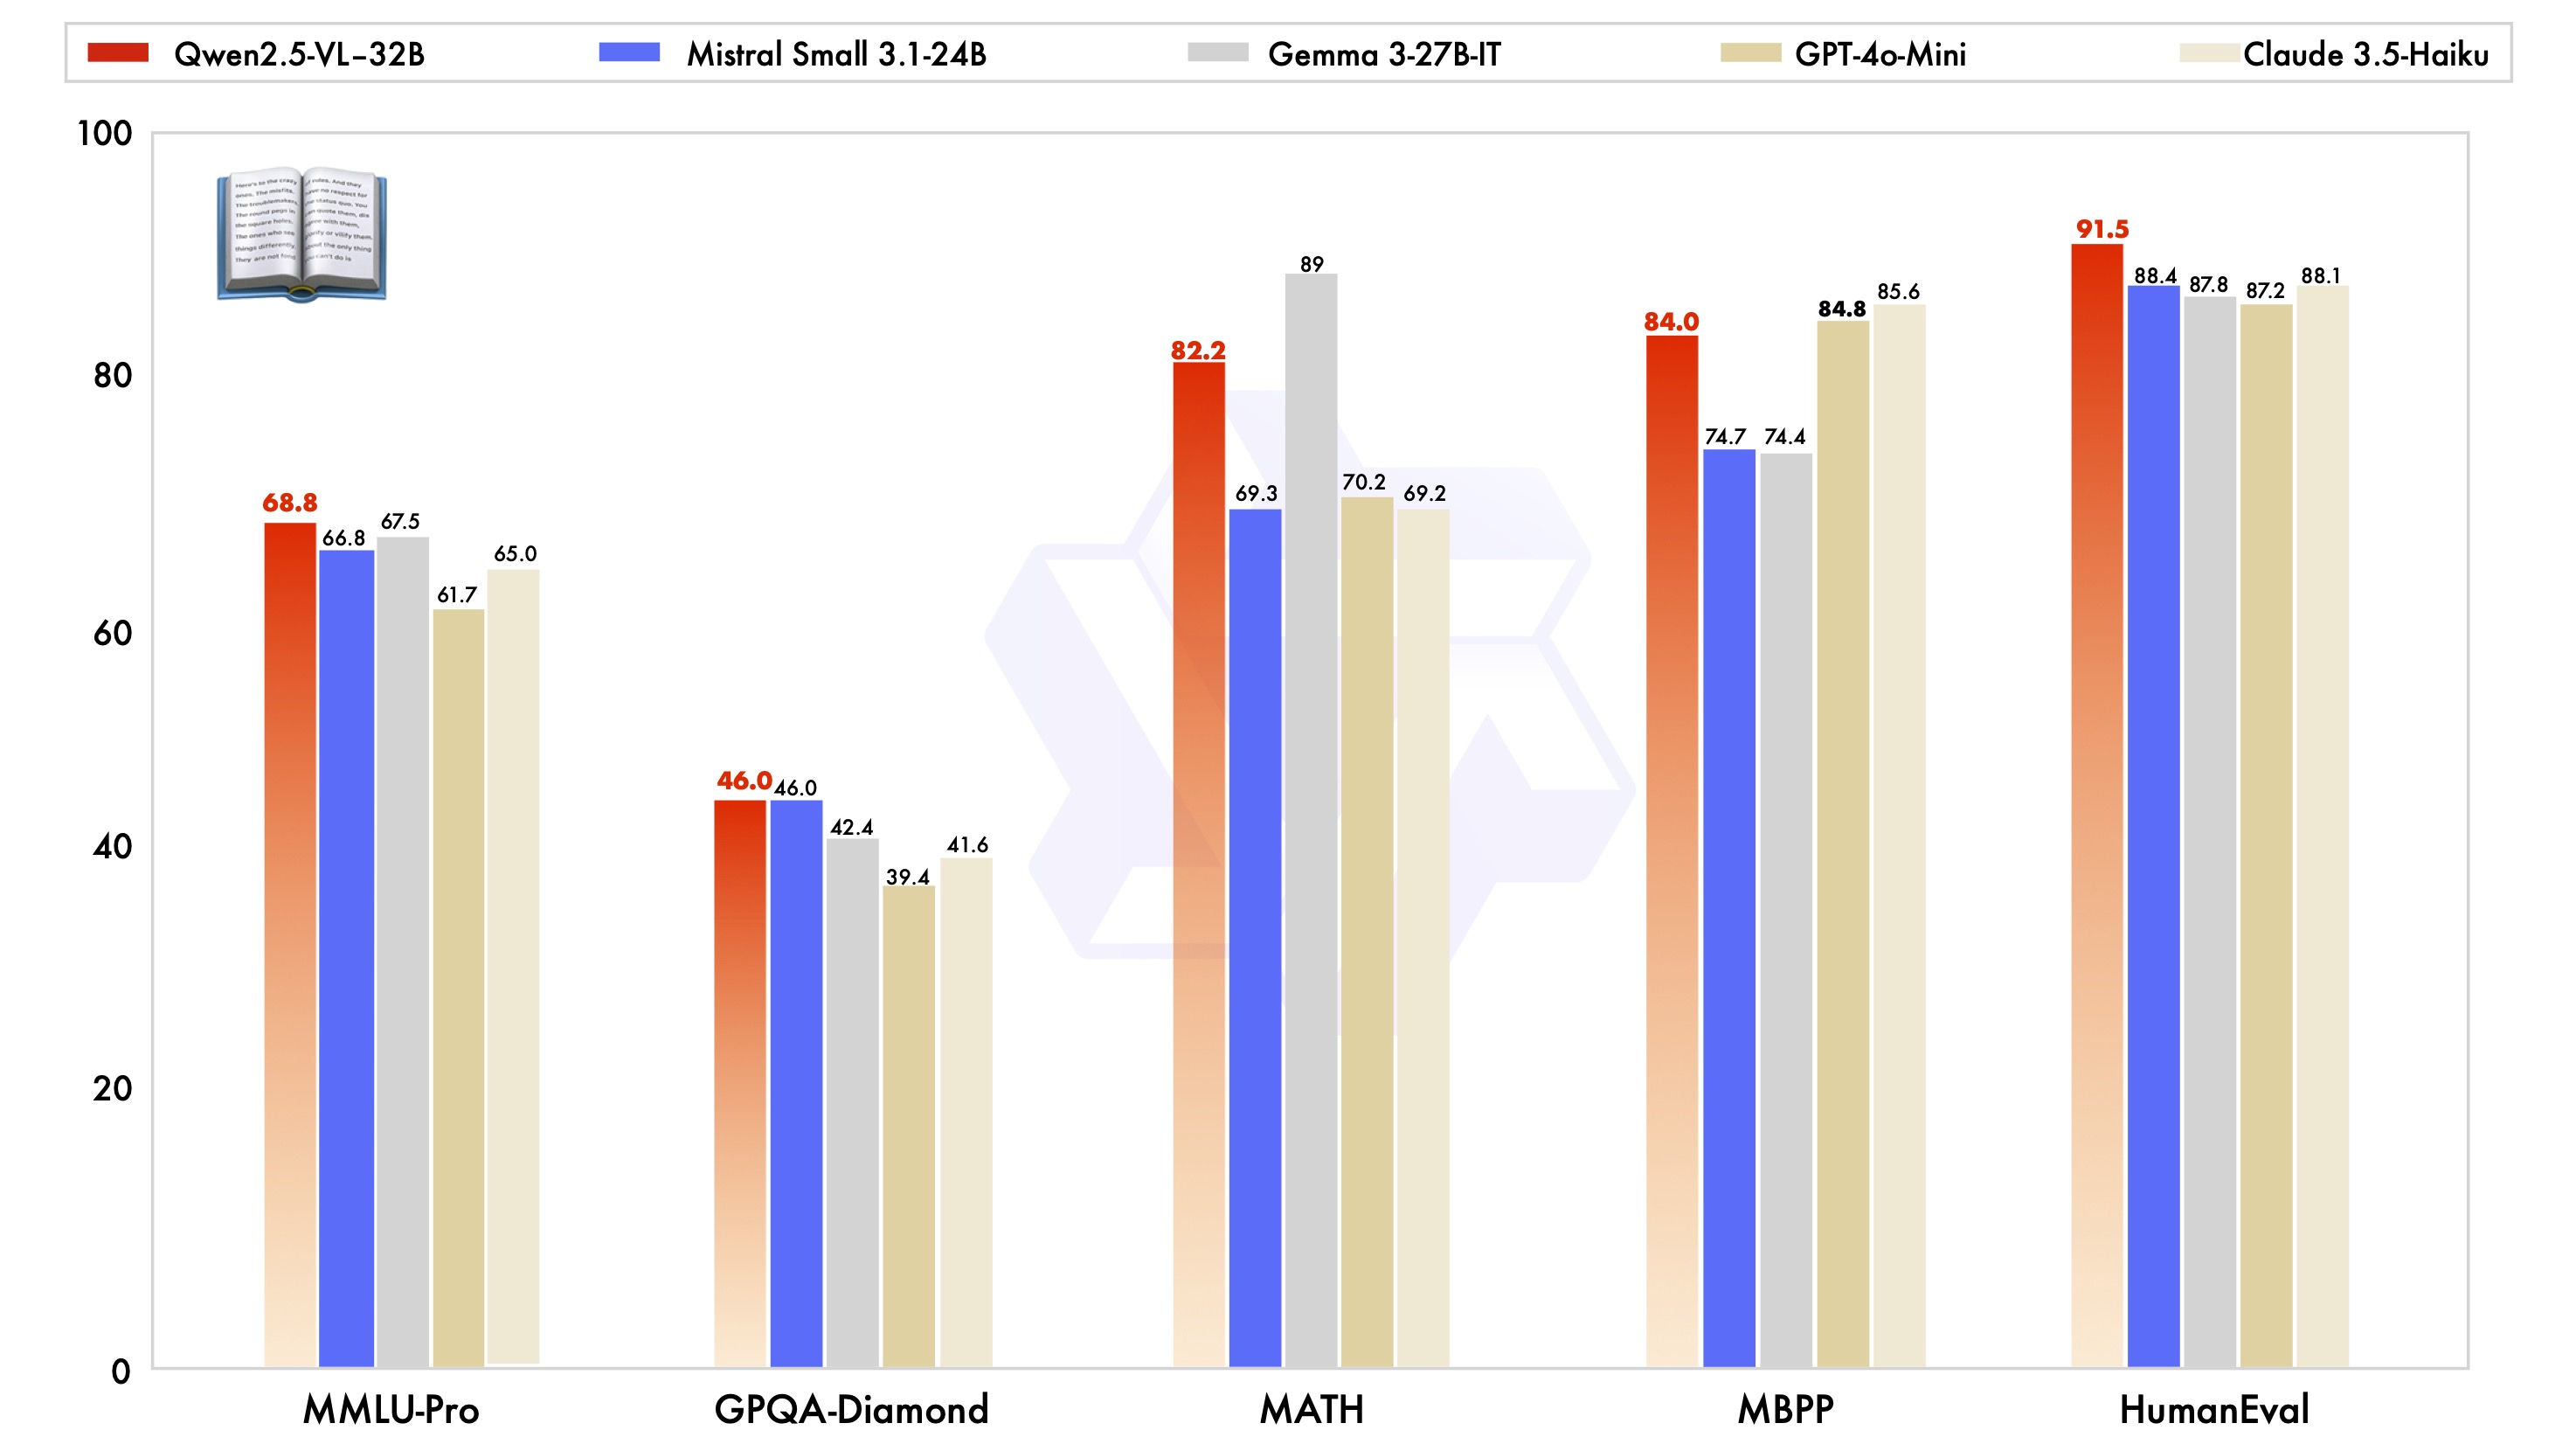
In addition to excelling in visual capabilities, Qwen2.5-VL-32B-Instruct has also achieved top-tier performance in pure text capabilities at the same scale.
Next Step#
While Qwen2.5-VL-32B has focused on optimizing subjective experience and mathematical reasoning through reinforcement learning—operating within the paradigm of "fast thinking". Our next research direction will prioritize long and effective reasoning processes to push the boundaries of visual models in tackling highly complex, multi-step visual reasoning tasks.
Citation#
If you find our model helpful, feel free to cite it:}}
原文来自 千问 Qwen Team,版权归原作者。
正文采集于 ,内容更新以原文为准。