Qwen-RobotWorld: Boundless Worlds for Embodied Agents
文章目录


Embodied intelligence requires agents to perceive, reason about, and act within physical environments. World models offer a scalable path forward — but current approaches face a fundamental tension. General video generation models learn rich visual priors but lack the ability to model embodied physics. Domain-specific embodied models are tailored to individual scenarios and cannot generalize across embodiments.
Qwen-RobotWorld bridges this gap by treating natural language as a universal action interface. A single instruction like "pick up the red cup and place it on the shelf" implicitly encodes the complete action sequence, goal state, and physical constraints — no robot-specific control interface needed. This allows manipulation, autonomous driving, and indoor navigation to be trained jointly, with each domain's physical knowledge reinforcing the others.
Language unifies the action space: world knowledge and embodied knowledge reinforce each other within a single model, enabling cross-scenario, cross-task physical generalization.
Key Highlights#
- Language-Driven Unified Action Interface — natural language standardizes 20+ robot embodiments and 500+ action categories into one interface, enabling joint cross-scenario training
- Dual-Stream Diffusion World Model — MMDiT with Qwen2.5-VL as action encoder, combining deep language understanding with internalized physical world knowledge
- Cross-Scenario Physical Generalization — manipulation, driving, navigation, and human-to-robot transfer jointly trained under 8.6M video-text pairs
- Multi-View Geometrically Consistent Generation — synchronized 2–4 camera streams with 3D-consistent object identity and motion trajectories
Model Architecture#
Dual-Stream Diffusion World Model#
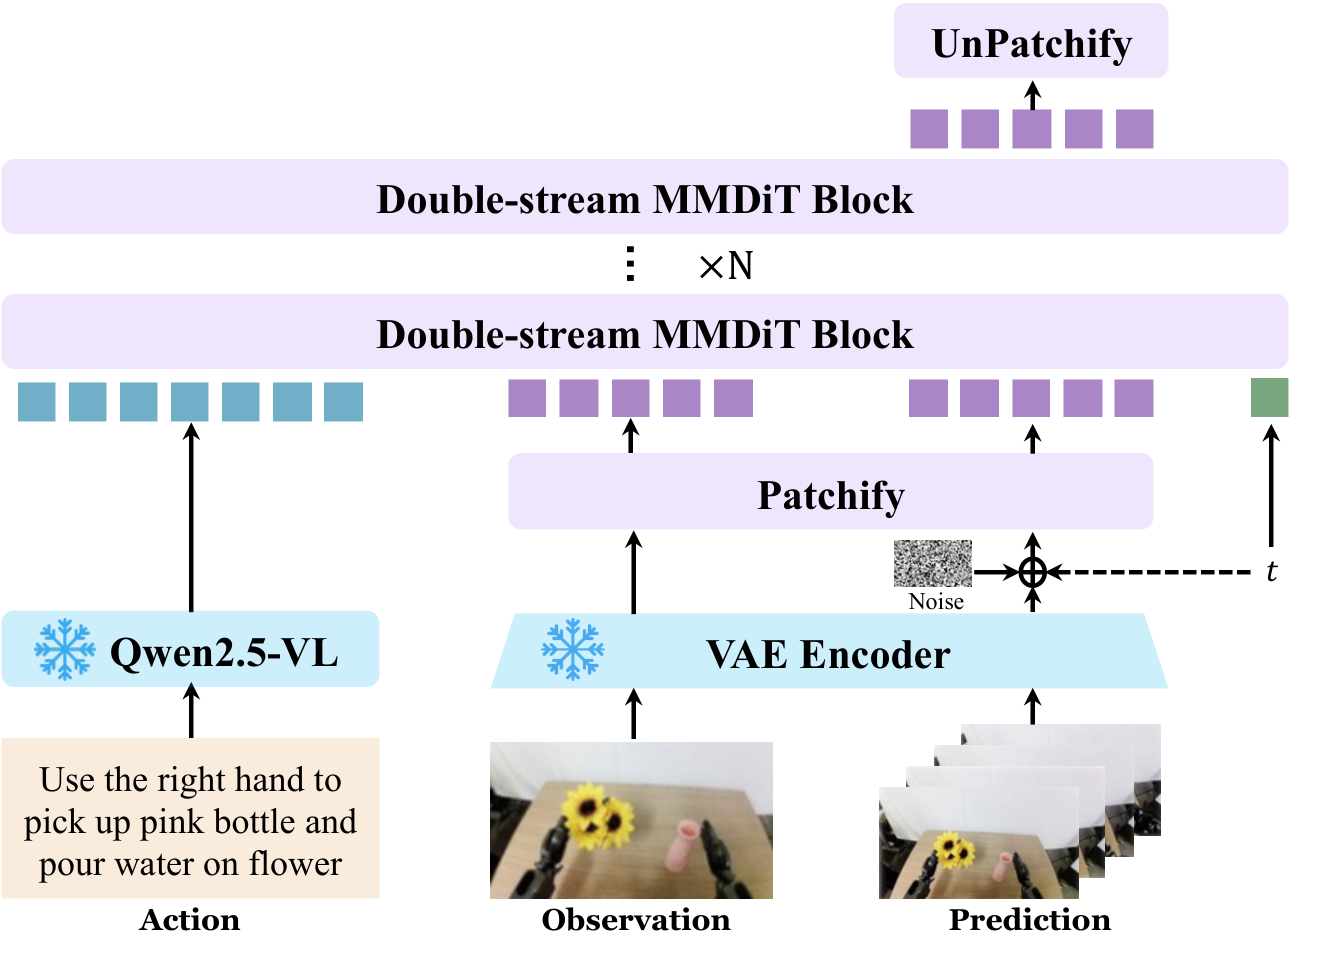
Qwen-RobotWorld adopts a dual-stream Multimodal Diffusion Transformer (MMDiT):
- Understanding stream processes semantic features from a frozen Qwen2.5-VL encoder, representing the language action $a_t$.
- Generation stream processes visual latents from a video-compatible VAE, representing the visual state $s_t$.
The two streams interact via joint attention at every layer, enabling bidirectional cross-modal fusion throughout the denoising process.
Using an MLLM as the action encoder — rather than lightweight encoders like T5 or CLIP — provides two key advantages: (1) deep language understanding accurately parses complex, compositional instructions into precise condition signals; (2) internalized world knowledge (e.g., that robot arms are rigid bodies with fixed joint constraints) implicitly constrains physically plausible transitions, preventing common failure modes like object deformation across frames.
Scene2Robot: Human-to-Robot Transfer#
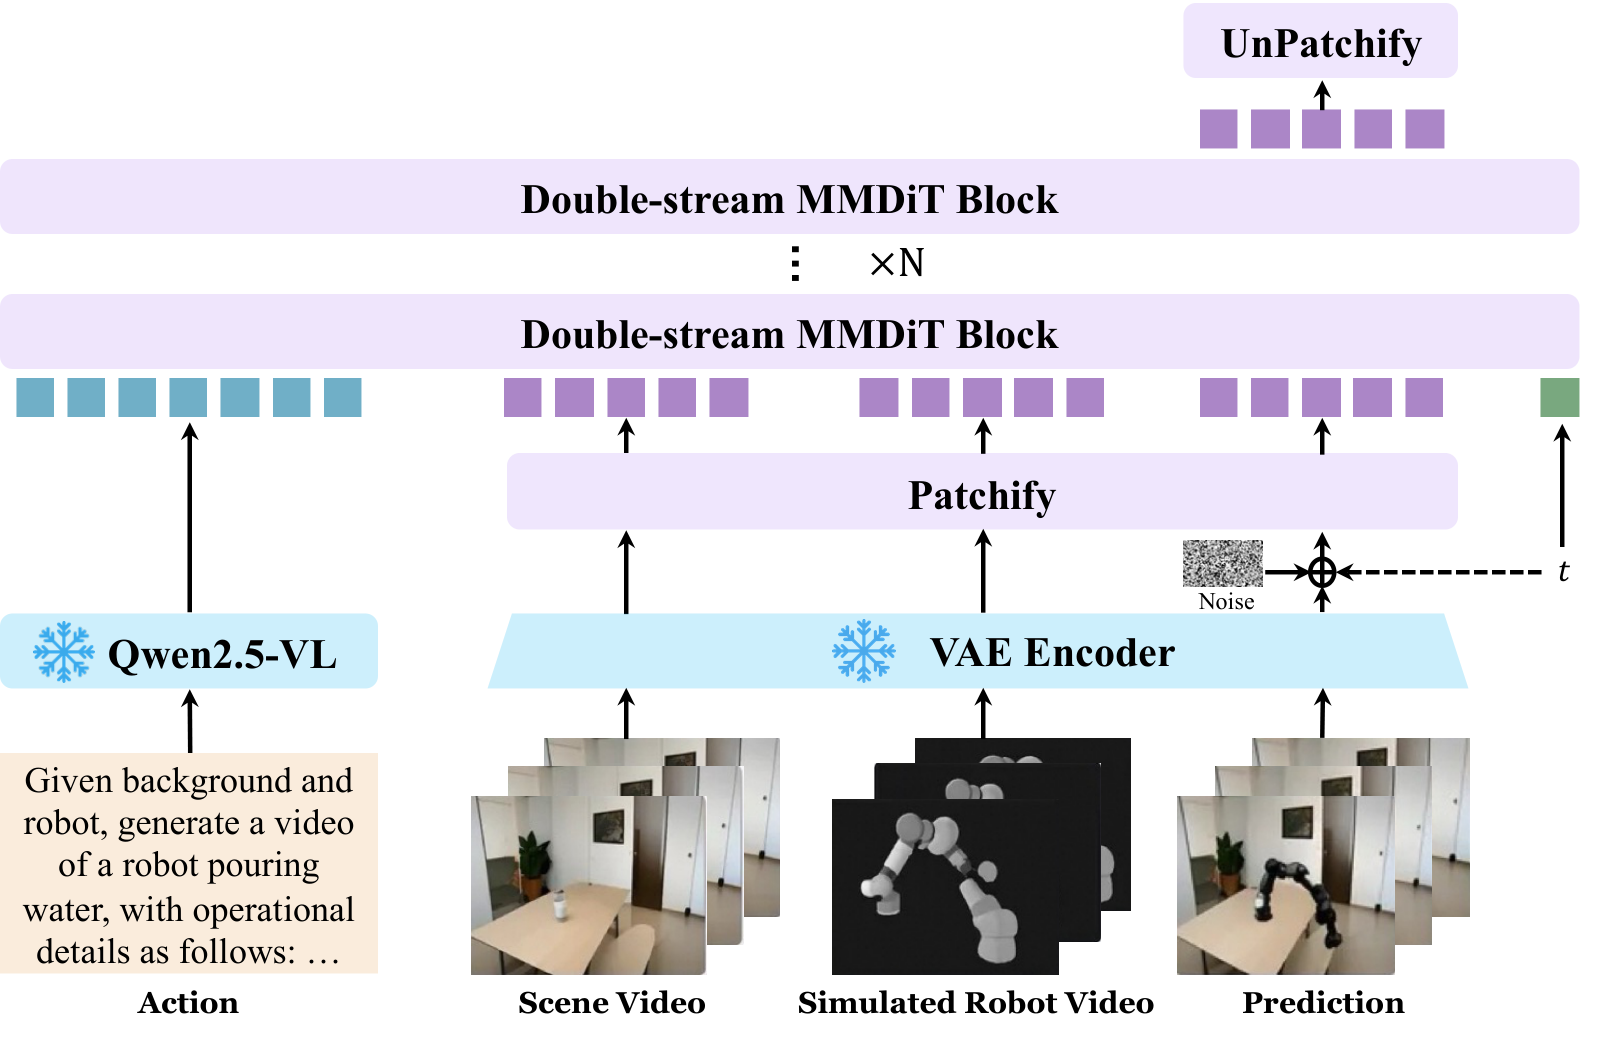
Scene2Robot enables cross-embodiment video editing: human demonstrations are retargeted to 14 robot morphologies via a multi-segment conditioning mechanism, where joint attention allows the generation to simultaneously attend to scene appearance and robot motion trajectory. This capability both serves as a data scaling engine during training and enables human-to-robot transfer at inference time.
Multi-View Geometrically Consistent Generation#
Single-camera observation inevitably occludes critical contact and spatial details. Qwen-RobotWorld generates 2–4 synchronized camera streams — main view, wrist-mounted views, and third-person views — with geometrically consistent object identity and motion across all viewpoints. During training, synchronized frames from multiple cameras are spatially concatenated into a single input; the model generates all views simultaneously, with asymmetric 3D RoPE providing spatial encoding and attention layers naturally establishing cross-view correspondence — without any architectural modification. This cross-view consistency further acts as a geometric regularizer, teaching the model object shape, depth, and spatial layout.
Data: Embodied World Knowledge#
EWK Dataset#

The Embodied World Knowledge (EWK) dataset is organized along four complementary axes, each targeting a distinct source of physical variation:
- Multi-Embodiment — human hands, 7 robot arm configurations, ego vehicles, mobile agents, spanning 20+ distinct robot models
- Multi-Task — atomic manipulation skills, long-horizon compositions, locomotion, dynamic/deformable interactions across 500+ action categories
- Multi-Scenario — real-world first, sim-augmented: kitchens, workshops, outdoor settings, plus photorealistic simulation for downstream VLA evaluation
- Multi-View — main, wrist, and synchronized multi-view streams (~1.6M of 6M embodied samples include 2–4 view concatenations)
View Detailed Dataset Inventory
| Dataset | Embodiment | Views | Contribution |
|---|---|---|---|
| Manipulation (~5.9M samples) | |||
| EgoHOD, EPIC-Kitchens, Egocentric-10k | Human hands | Egocentric | Dexterity & coordination prior |
| Bridge V2, RH20T, Droid | Single-arm grippers | 3rd-person + wrist | Interaction primitives |
| Robomind, RoboCoin | Single/dual-arm, humanoids | Ego + 3rd-person | Cross-embodiment generalization |
| Agibot-World, Galaxea | Single-arm (gripper + dexterous) | Synced ego + wrist + 3rd | Temporal & multi-view consistency |
| Qwen-Aloha (internal) | Dual-arm grippers | Head + dual wrist | Multi-view grasping prior |
| ActionNet, OpenLoong | Dexterous hands | Wrist + 3rd-person | Fine-grained dexterity |
| Autonomous Driving (~200K samples) | |||
| Waymo, NVIDIA PhysicalAI-AD, Bench2Drive, Sekai | Ego vehicle | Surround-view | Large-scale ego-motion & multi-agent dynamics |
| Indoor Navigation (6K+ episodes) | |||
| VLNVerse | Mobile agent | Egocentric | Room-scale spatial reasoning |
| Human-to-Robot Transfer | |||
| Scene2Robot (synthesized) | 14 robot morphologies | Multi-view | Cross-embodiment video editing |
Action-Language Mapping#
The central challenge in building a universal world model is representational heterogeneity: manipulation uses joint angles, driving uses steering commands, navigation uses heading vectors — each requiring a separate model. Our action-language mapping framework resolves this by projecting all action signals onto a shared natural language space, so that videos from a Franka gripper, an autonomous vehicle, and a navigation agent all become instances of the same language-conditioned video generation task.
A hierarchical five-layer annotation pipeline ensures caption quality and precision:
During training, comprehensive and concise descriptions are sampled with equal probability, so the model handles both detailed trajectory specifications and brief task-level commands.
Training#
Training follows a general-to-expert progressive curriculum:
| Stage | Phase | Data Mix | Objective |
|---|---|---|---|
| Pretraining | T2I / T2V / TI2V joint | General data | Build foundational visual priors |
| Human interaction | Ego4D, EPIC-Kitchen, etc. | Grasping & tool-use priors | |
| SFT | Phase 1: Single-view manipulation | Embodied + general joint training | Core manipulation physics |
| Phase 2: Multi-view expansion | Broaden viewpoint coverage | ||
| Phase 3: Multi-view concatenation | Cross-view geometric consistency | ||
| Phase 4: Complex cross-domain | Long-horizon & cross-scenario |
Pretraining on general data and human interaction videos (Ego4D, EPIC-Kitchen) builds broad visual priors — the T2I task specifically anchors object geometry that transfers to video generation through the shared backbone. SFT then progressively deepens embodied expertise across four phases while keeping general data in every batch, ensuring both capabilities advance together rather than trade off.
Demos#
Fine-Grained Language Grounding#
Given identical initial frames, the model produces qualitatively distinct videos when a single keyword differs. It also handles complex, multi-step instructions requiring long-horizon reasoning.
Contrastive Instruction Following:
L: Pick up the red strawberry
R: Pick up the yellow potato
L: Place pen on the wooden tray
R: Place pen on the white paper
L: Hand glue to the person
R: Place glue into the penholder
Complex Multi-Step Instructions:
Sequentially pick up the red and yellow bell peppers, place them on the table from left to right
Grab the yellow-and-blue stacked block, position it above the green-and-blue stacked block
Cross-Domain Generalization#
(A) Cross-Embodiment:
(B) Cross-Task × Cross-Environment:
(C) Multi-View Consistency:
(D) Zero-Shot Robustness:
Ours
LVP
Cosmos2.5-14B
Human-to-Robot Transfer#
The Scene2Robot mechanism preserves task intent from a human demonstration (left) while adapting motion to embodiment-specific kinematic constraints (right).
Beyond Manipulation: Driving and Navigation#
The learned world model generalizes beyond robot manipulation to broader mobility scenarios.
Autonomous Driving. Generated driving episodes from Bench2Drive, NVIDIA PhysicalAI-AD, Sekai, and Waymo demonstrate coherent scene dynamics and vehicle behaviors.
Indoor Navigation. Egocentric navigation episodes from VLNVerse show the model’s ability to simulate first-person movement through complex indoor environments.
From tabletop manipulation to autonomous driving and indoor navigation — Qwen-RobotWorld demonstrates that a unified world model can generalize beyond a single morphology or scenario family.
Performance#
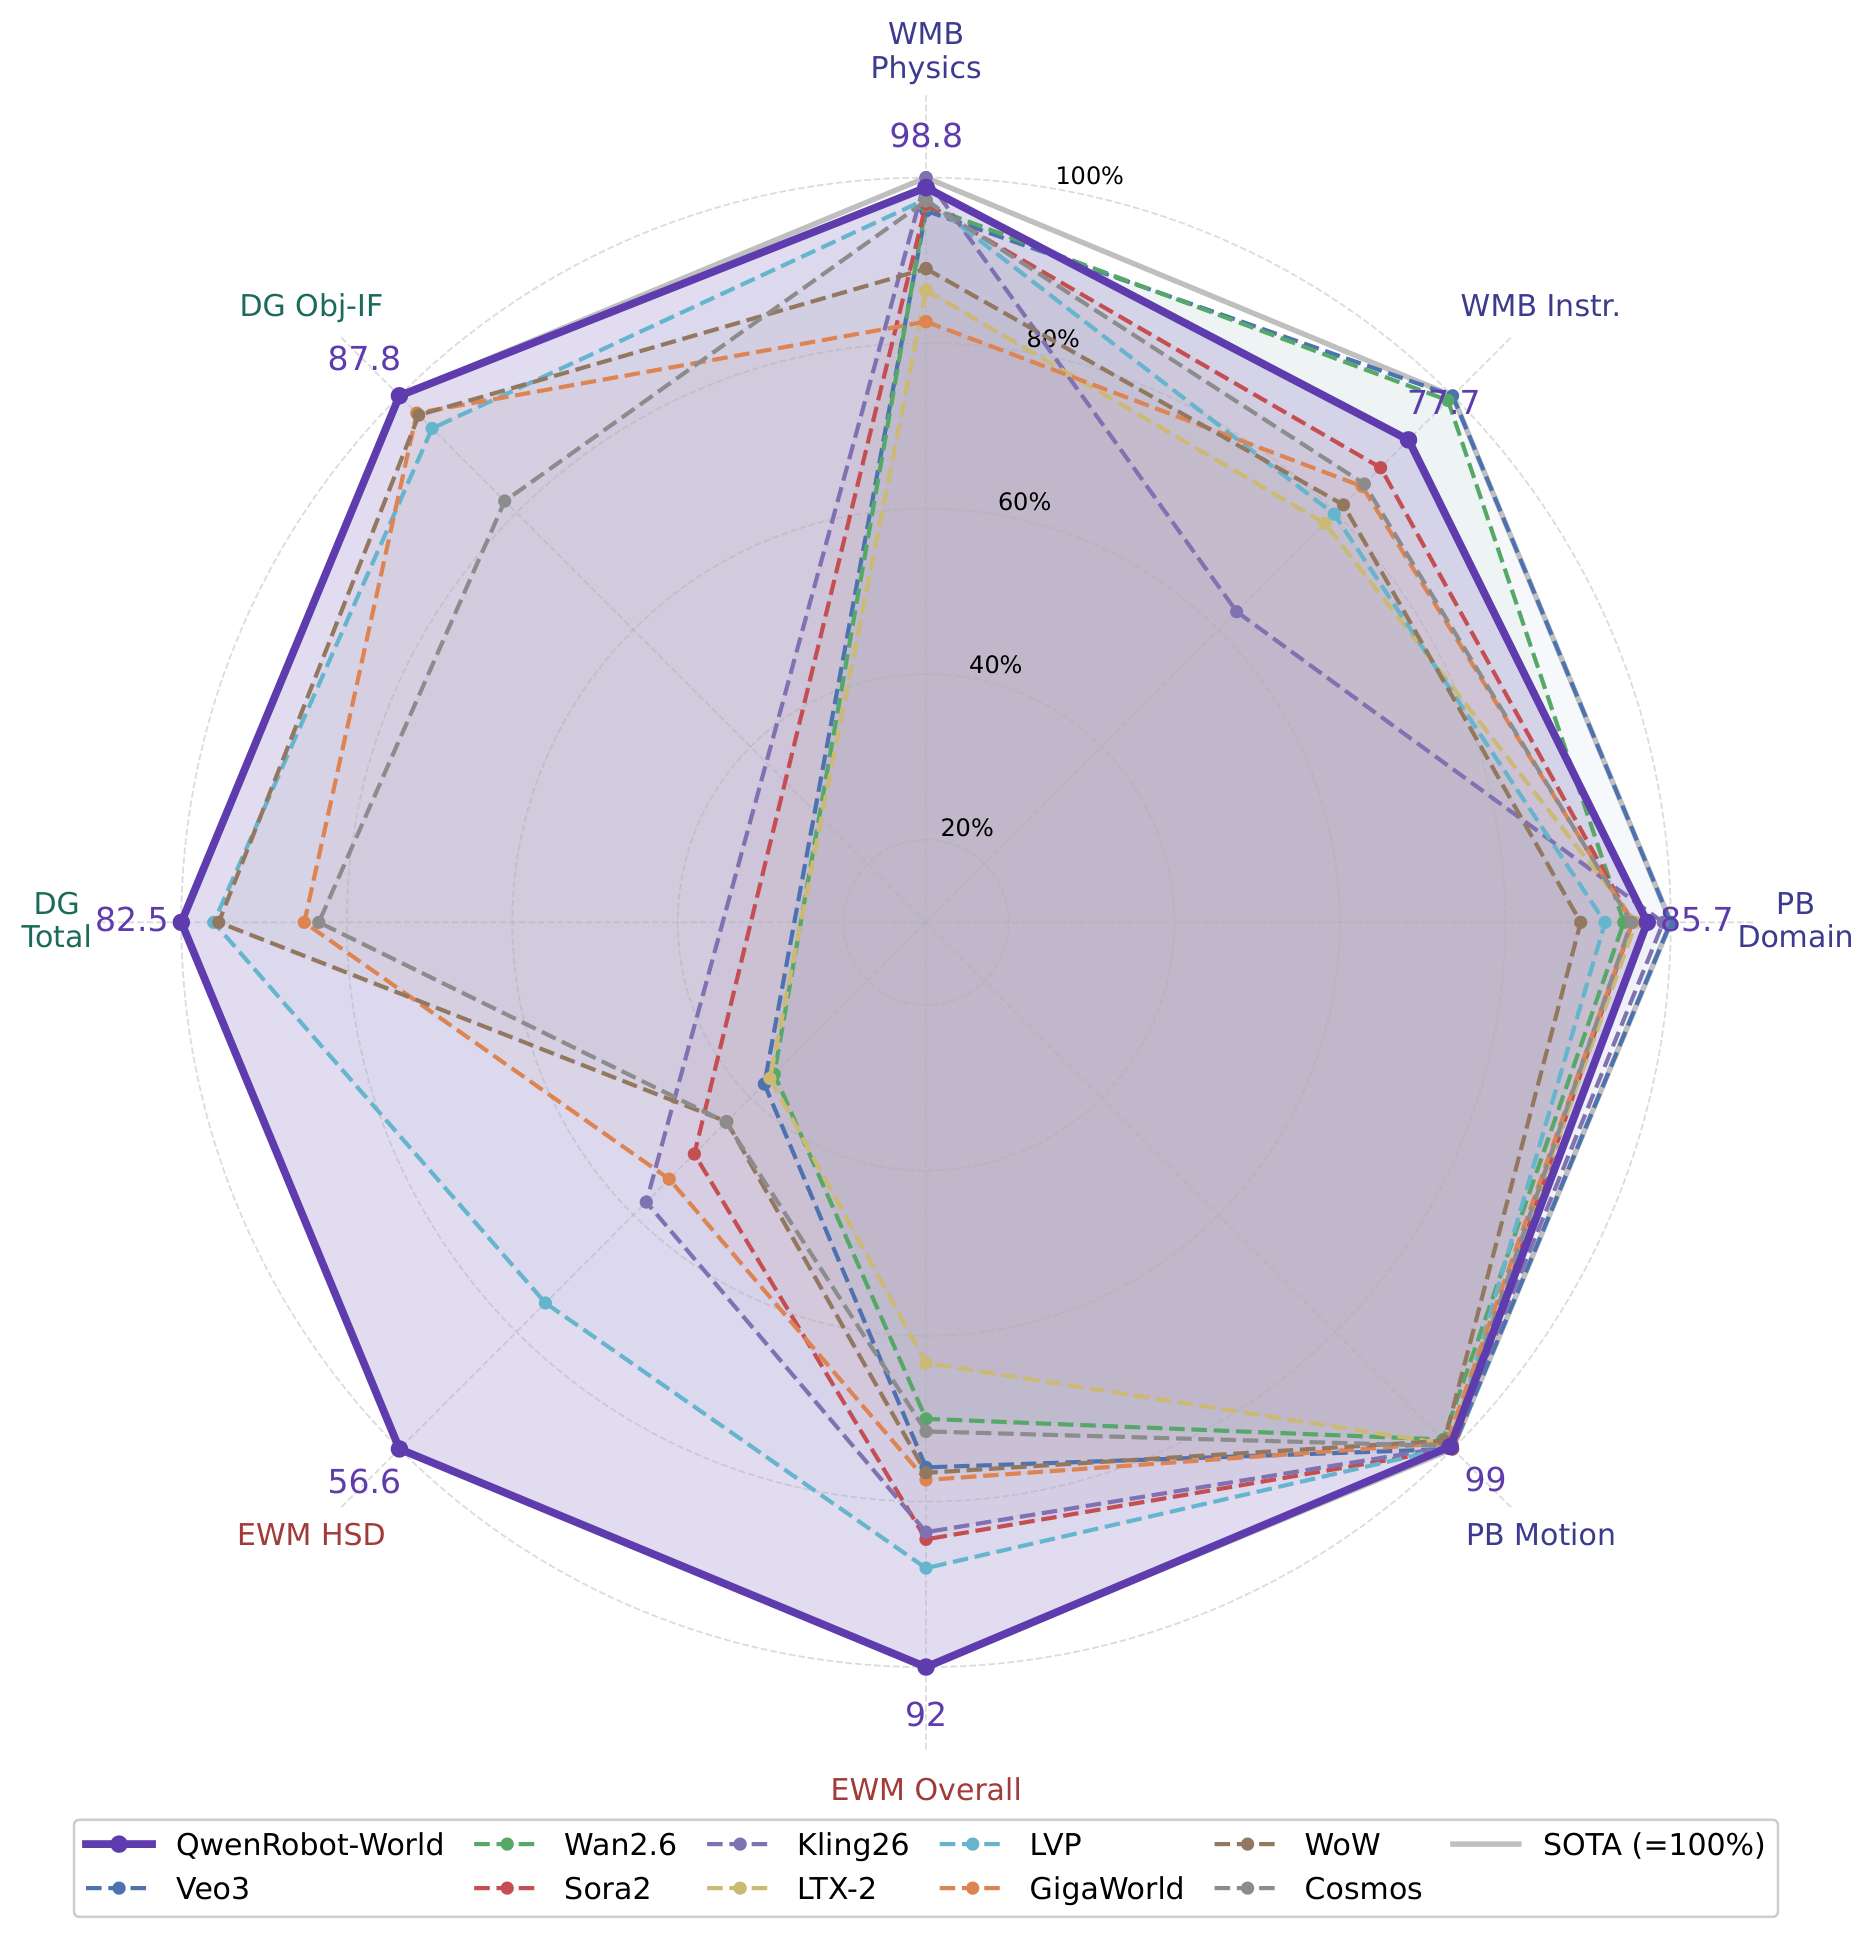
We evaluate against general video generation models (Sora2, Veo3, Wan2.6, Kling, LTX-2) and embodied world models (Cosmos, LVP, GigaWorld, Vidar, Wow) across four benchmarks.
EWMBench
| Type | Model | SceneC | HSD | Dyn | nDTW | Diversity | BLEU | CLIP | Logics | Overall |
|---|---|---|---|---|---|---|---|---|---|---|
| General | Veo3 | 0.842 | 0.213 | 0.193 | 0.161 | 0.022 | 0.214 | 0.897 | 0.947 | 3.49 |
| Wan2.6 | 0.671 | 0.203 | 0.090 | 0.172 | 0.050 | 0.162 | 0.874 | 1.000 | 3.22 | |
| Kling | 0.821 | 0.327 | 0.182 | 0.342 | 0.017 | 0.259 | 0.901 | 1.000 | 3.85 | |
| LTX-2 | 0.785 | 0.208 | 0.128 | 0.244 | 0.012 | 0.143 | 0.887 | 0.500 | 2.91 | |
| Sora2 | 0.853 | 0.281 | 0.349 | 0.275 | 0.031 | 0.247 | 0.910 | 0.947 | 3.89 | |
| Embodied | Cosmos | 0.796 | 0.250 | 0.205 | 0.253 | 0.080 | 0.123 | 0.846 | 0.733 | 3.29 |
| GigaWorld | 0.871 | 0.305 | 0.085 | 0.278 | 0.028 | 0.205 | 0.887 | 0.900 | 3.56 | |
| LVP | 0.880 | 0.425 | 0.043 | 0.623 | 0.009 | 0.218 | 0.900 | 0.952 | 4.05 | |
| Vidar | 0.734 | 0.188 | 0.152 | 0.177 | 0.065 | 0.161 | 0.882 | 0.941 | 3.30 | |
| Wow | 0.887 | 0.249 | 0.053 | 0.257 | 0.027 | 0.193 | 0.900 | 0.952 | 3.52 | |
| Ours | 0.914 | 0.566 | 0.343 | 0.671 | 0.011 | 0.208 | 0.883 | 1.000 | 4.60 |
Strong motion fidelity (HSD 0.566), high scene consistency (0.914), and perfect logic constraint satisfaction.
DreamGen Bench
| Model | GR1-Env PA | GR1-Env IF | GR1-Object PA | GR1-Object IF | GR1-Behavior PA | GR1-Behavior IF | Total |
|---|---|---|---|---|---|---|---|
| Cosmos-sft | 0.709 | 0.655 | 0.775 | 0.720 | 0.649 | 0.621 | 4.129 |
| LVP | 0.810 | 0.772 | 0.745 | 0.829 | 0.713 | 0.889 | 4.758 |
| Vidar | 0.445 | 0.647 | 0.478 | 0.726 | 0.394 | 0.651 | 3.341 |
| GigaWorld | 0.621 | 0.933 | 0.500 | 0.852 | 0.426 | 0.884 | 4.216 |
| Wow | 0.793 | 0.826 | 0.755 | 0.849 | 0.809 | 0.696 | 4.728 |
| Ours | 0.828 | 0.793 | 0.840 | 0.878 | 0.781 | 0.832 | 4.952 |
Strong object-level compositional generalization (GR1-Object IF: 0.878), with consistent physics alignment across all subsets.
WorldModelBench
| Type | Model | Instr. (0-3) | Frame | Temp | Newton | Mass | Fluid | Penetr. | Grav. | Phys. | Total |
|---|---|---|---|---|---|---|---|---|---|---|---|
| General | Veo3 | 2.52 | 0.98 | 0.95 | 1.00 | 0.89 | 0.99 | 0.91 | 1.00 | 4.80 | 9.25 |
| Wan2.6 | 2.50 | 0.99 | 0.95 | 1.00 | 0.89 | 0.99 | 0.94 | 1.00 | 4.83 | 9.27 | |
| Sora2 | 2.21 | 0.96 | 0.93 | 1.00 | 0.91 | 0.99 | 0.95 | 1.00 | 4.84 | 8.93 | |
| Kling | 1.59 | 0.97 | 1.00 | 1.00 | 1.00 | 1.00 | 1.00 | 1.00 | 5.00 | 8.55 | |
| LTX-2 | 1.97 | 0.69 | 0.62 | 0.99 | 0.60 | 1.00 | 0.73 | 1.00 | 4.32 | 7.61 | |
| Embodied | Cosmos | 2.14 | 1.00 | 0.94 | 1.00 | 0.92 | 1.00 | 0.94 | 1.00 | 4.86 | 8.94 |
| LVP | 2.01 | 0.89 | 0.91 | 1.00 | 0.93 | 0.99 | 0.95 | 1.00 | 4.87 | 8.67 | |
| GigaWorld | 2.13 | 0.59 | 0.46 | 1.00 | 0.48 | 0.99 | 0.69 | 0.98 | 4.13 | 7.31 | |
| Vidar | 1.62 | 0.54 | 0.45 | 1.00 | 0.56 | 1.00 | 0.85 | 1.00 | 4.40 | 7.01 | |
| Wow | 2.05 | 0.76 | 0.65 | 1.00 | 0.65 | 0.99 | 0.81 | 1.00 | 4.45 | 7.91 | |
| Ours | 2.33 | 0.87 | 0.85 | 1.00 | 1.00 | 1.00 | 0.94 | 1.00 | 4.94 | 8.99 |
PBench
| Type | Model | I2V-Bg | I2V-S | Aes | Img | Bg-Con | Mot | Sub-Con | O-Con | Quality | Domain | Overall |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| General | Veo3 | 0.975 | 0.980 | 0.526 | 0.698 | 0.938 | 0.994 | 0.927 | 0.128 | 0.771 | 0.882 | 0.827 |
| Wan2.6 | 0.856 | 0.843 | 0.514 | 0.719 | 0.906 | 0.978 | 0.843 | 0.136 | 0.724 | 0.832 | 0.778 | |
| Sora2 | 0.981 | 0.973 | 0.487 | 0.672 | 0.961 | 0.994 | 0.954 | 0.129 | 0.769 | 0.841 | 0.805 | |
| Kling | 0.982 | 0.979 | 0.521 | 0.699 | 0.920 | 0.990 | 0.927 | 0.124 | 0.768 | 0.874 | 0.821 | |
| LTX-2 | 0.948 | 0.955 | 0.506 | 0.622 | 0.932 | 0.986 | 0.904 | 0.118 | 0.746 | 0.845 | 0.796 | |
| Embodied | LVP | 0.979 | 0.981 | 0.515 | 0.679 | 0.954 | 0.991 | 0.962 | 0.116 | 0.772 | 0.812 | 0.792 |
| GigaWorld | 0.957 | 0.944 | 0.495 | 0.641 | 0.925 | 0.984 | 0.892 | 0.128 | 0.746 | 0.841 | 0.794 | |
| Wow | 0.967 | 0.957 | 0.517 | 0.689 | 0.941 | 0.980 | 0.929 | 0.111 | 0.761 | 0.786 | 0.774 | |
| Vidar | 0.935 | 0.922 | 0.501 | 0.573 | 0.912 | 0.982 | 0.863 | 0.120 | 0.726 | 0.810 | 0.768 | |
| Cosmos | 0.974 | 0.973 | 0.470 | 0.663 | 0.940 | 0.989 | 0.931 | 0.160 | 0.763 | 0.840 | 0.802 | |
| Ours | 0.956 | 0.943 | 0.455 | 0.649 | 0.956 | 0.990 | 0.933 | 0.124 | 0.751 | 0.857 | 0.804 |
Strong domain understanding (0.857) and motion smoothness (0.990), reflecting consistent temporal coherence across physical scenarios.
Citation#
If you find our work helpful, feel free to give us a cite.
@article{qwenrobot-world,
  title={Qwen-RobotWorld Technical Report: Unifying Embodied World Modeling through Language-Conditioned Video Generation},
  author={Qwen Team},
  year={2026}
}
原文来自 千问 Qwen Team,版权归原作者。
正文采集于 ,内容更新以原文为准。